
Making robot policies less spatially dumb and more 3D-aware 🤠 Doing a PhD with Yue Wang @ USC Becoming full-stack roboticist https://xitter.cf/t.co/wm3qeJdn8P
Joined January 2023
- Tweets51
- Following400
- Followers338
- Likes17.4K



Pinned Tweet
A paradox in robot learning:
robot policies are spatially dumb and data-inefficient but their image features are spatially robust and semantically rich.
Image encoders are spatially smart — features embed semantics + geometry + are multiview-consistent ...
but robot policies we build upon them are spatially dumb — hundreds of demos to learn simple pick+place and a small camera bump breaks them
To better bridge this gap, check out BIND: a new action head that binds each candidate robot action to its projecting 2D image feature(s)
BIND basically offers the network the info of '‘choosing this candidate robot action would move the robot EEF to this image feature."
Result: policies much more data efficient and robust to OOD viewpoints and OOD object positions (same rgb input, no 3D sensors, dense EEF trajectories out) 🧵
Cameron Smith retweeted

Sharing our new work OpenTac; a tactile sensor + ecosystem that let’s you automatically design, customize, and deploy tactile skins on any robot surface!
Work led by @arikslep and in collaboration with a large group of robotics faculty new-and-not-new @JohnsHopkins. This also is my first preprint since I started my faculty position @JHUCompSci @HopkinsDSAI and setup SciPhy lab this Fall.
OpenTac is a piezoresistive robot skin that can accurately estimate normal and shear forces, can be adapted to sensorize any developable robot surface, and based on how sparse your contact is, adaptively readout at kilohertz-rate.
All of our software, hardware, and firmware is made available under open, permissive licenses for research or commercial use. 🧵


Cameron Smith retweeted

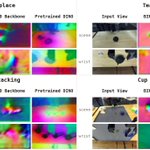
DINO features are so good at correspondence matching since they are spatially aware!
One reason why you should use BIND for policy-learning is the features are trajectory-aware!
Cool analysis from @omcamsmith on the BIND paper: cameronosmith.github.io/bind…

A cool thing about our BIND action head: the image features seem to better encode the full trajectories in their 2D feature maps
Here I’m plotting the feature map PCA from DINO with BIND action head vs at init: you can see the full trajectory of the task encoded in the feature maps
E.g. check out the top left cup stack, you can see the path from the EEF to the cup and from the cup to the plate;
For the teapot you can see even for the small teabag the path from the EEF from the teapot lid, to the place we drop the lid off on the right of the teapot, and from the teabag to the teapot
Here’s what I like about it: most of the heavy lifting of the action space is being done in the 2D image encoder rather than some beefy action head, which is good because we’re tapping into the backbone that sees the most data rather than our from-scratch action head weights
More info on the BIND head at xitter.cf/omcamsmith/status/2106…
A paradox in robot learning:
robot policies are spatially dumb and data-inefficient but their image features are spatially robust and semantically rich.
Image encoders are spatially smart — features embed semantics + geometry + are multiview-consistent ...
but robot policies we build upon them are spatially dumb — hundreds of demos to learn simple pick+place and a small camera bump breaks them
To better bridge this gap, check out BIND: a new action head that binds each candidate robot action to its projecting 2D image feature(s)
BIND basically offers the network the info of '‘choosing this candidate robot action would move the robot EEF to this image feature."
Result: policies much more data efficient and robust to OOD viewpoints and OOD object positions (same rgb input, no 3D sensors, dense EEF trajectories out) 🧵
here’s something small but useful I built with claude-as-cad:
I wanted the camera pose and intrinsics relative to some cheap-amazon camera’s CAD/step file
so I built a tiny camera calibration jig where it’s mounted relative onto some known place and observes some aruco board in a known place — from it we can get the camera pose and intrinsics relative to the mounting place
cad agent passed it to the calibration agent to write the detection script to run this automatically and save it
in addition to some policy use cases, one tricky thing is knowing where to place the wrist camera in CAD to make sure it has good observation
I had another agent make a localhost program where I can move/drag the camera around in mujoco and view the corresponding render of exactly what the wrist camera will observe when mounted
once I lock in the pose, the script sends the camera pose to the cad agent to update the EEF's wrist camera position with it
this is one example that I think illustrates why you want a proper CAD agent and interface across the full robotics stack
introducing claude-as-cad
i've been actually building robots and parts without knowing any CAD, using a claude-as-cad recipe -- here's how and you can too:
language-based prompting for CAD-agents is a good start, but it's imprecise -- these builds are difficult to steer exactly, among other issues
instead, you should have claude build you a claude-native CAD interface.
i've had success with this and found 3 important ingredients:
1. click to reference -- click any part of the build and the [3D coordinate, mesh face, object id] are copied to your clipboard to paste into chat
➡️ lets you be hyper-specific about what part you are referring to in chat
2. 3D primitive editor -- reposition/reorient any existing object; add a cube to the scene and scale/position for claude to use for reference
➡️ often times its hard to describe a position/transform in language and easier to illustrate it yourself to claude
3. hierarchical notes -- claude organizes separate builds into nested folders and writes skills that survive conversation compacting
➡️ saving different builds in folders with common skills, e.g. servo mounts, means once you get it right and save it, you can always reference it easily
link to install to your agent setup below ⬇️
cameronosmith.github.io/clau…
see more examples about the features above animated/interactive here on the website
these features obviously aren't exhaustively 1:1 with a CAD software, but I believe software in this AI age should meet you where you at your skill/need and customize the software on the fly : need an interactive fillet tool? add it, it's one prompt away! etc

Moving beyond simple pick and place, check out these other tasks. Teapot requires really high precision (tiny grasp point on the lid). Fold towel is bimanual
Cup spill is reorienting a fallen cup and wiping up a spill. Cup stack involves rotating the smaller measuring cup into the bigger cup.
<= 40 training demos for each task.
The method is super simple and basically just two steps:
1. Use action classification instead of regression (e.g. discretize some EEF volume and use next-voxel classification)
2. Project each candidate 3D action onto its corresponding 2D image feature before scoring the action.
It's basically the same number of parameters as a typical global action token regression, with the only difference that we're scoring combinations of [action, image feature] instead of just regressing the action from some global token, to more directly combine the action space and image feature space
Check out the website and paper: cameronosmith.github.io/bind
Grateful to work with my awesome mentors/collaborators at USC and TRI!!
Next steps: scaling up to data beyond simple action primitives, embedding it in a generative/diffusion framework
Inferring a robot’s 3D state (robot↔camera pose + joint angles / link poses) is still weirdly clunky
Introducing Fiducial Exoskeletons: Image-Centric Robot State Estimation!
cameronosmith.github.io/fidu…
FidEx makes it fast + robust from a single image 🧵
I've found it incredibly useful in my recent experiments -- camera pose and intrinsics from a single image and even moving camera stream, as well as for really easy one-second robot re-calibration
IMO this is a much needed quality-of-life upgrade to the 3D-aware robotics stack for the new paradigm of vision-based robot control
Thanks as always to the great mentor team of @basilevanh @vitorguizilini @yuewang314