

phd @mbzuai | multimodal in research & life.
Joined November 2020
- Tweets577
- Following911
- Followers450
- Likes2.6K




Pinned Tweet
🤖🤚 Give a video generation model a scene and a goal. Can it generate egocentric execution to get the job done?
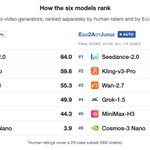
We tested 110 real-world scenarios on 6 SoTA models to see how they perform.
Introducing Ego2Act, a goal-directed video generation benchmark 👇
🌐 ego2act.github.io
🧪 alphaxiv.org/abs/2610.01092
🤗 huggingface.co/datasets/ego2…
[🧵Thread]
patrick retweeted

This is the most valuable free resource we've created on AI Evals 🎉 (not exaggerating!)
I organized our public materials into this guide. It allows you to find answers to your eval problems w/o searching aimlessly.
Humans: pick the row that sounds like you.
Agents: point it at the post
The material draw on 60+ hours of office hours from our Evals course, where @sh_reya and I have taught 5k engineers and PMs Evals.
We add new material often, with 15 FAQs added in the last two weeks. Recent additions are marked with a "New" badge. You can find all of these and more here:
hamel.dev/blog/posts/evals-f…

patrick retweeted
I've been looking into public benchmarks and am astounded by the poor quality vs. how much we rely on them as an industry.
@xeophon pointed me to this excellent site epoch.ai/benchmarks/ which is an independent third party which scrutinizes benchmarks and "looks at the data" 💪
For example, here are some popular benchmarks we all rely on. Before trusting a benchmark its worth running them and inspecting examples the grader failed carefully, to get a sense of the quality.
I'm continuing to look more into this, and will write something up eventually once I've collected more data, but I think this is an important subject.

patrick retweeted

have we exhausted the mine of low-hanging verifiability for building evals and rl environment?
any thoughts?

I really wanna be an ambidextrous writer so im doing a 30d challenge (gonna post daily)
super chopped but lets see how it goes😭🙏


We're open-sourcing RL360, the RL infrastructure behind K2 Horizon's six domain experts: 8,192 concurrent sandboxes, 150 steps in 7 days, ~1.3M rollouts.
Long-horizon agentic RL runs thousands of agents in real sandboxes on tasks that take minutes. Some of those sandboxes crash mid-task, and a crash arrives as the same low score as a wrong answer.
Without infrastructure that can keep up, GPUs are underutilized and the model gets penalized for system crashes rather than its own mistakes.
RL360 is built for this. We share how it works, what broke at scale, and what we learned in the thread.
Code: github.com/ifm-ai/RL360
Run: wandb.ai/mbzuai-llm/rl360-pu…
interesting read, summary:
- $500 only for defeating Ender Dragon, wow
- finished at 27 hours
- half of the run is for the final fight, with most deaths cluster there
- multi-agent collaboration on long-horizon tasks (though there are only 50-80 chats between them)
- self organization on how they divide tasks / labors emerges
limitations:
- collaboration is still a hurdle
- not vision-based agents like VPT or MineDojo-style setup
- brute force is cheap here (605 deaths)

If this is not a wakeup call to the uppers, idk what else, udah terlalu ketara dari kancah global bahwa nusantara sedang tidak baik" saja
Yall been saying "its okay its okay as long as the finance is good" and look how the tables have turned 🚨🫢


patrick retweeted

Everyone wants to have solved a hard problem, but almost nobody wants to live inside the grind of actually solving it. The breakthroughs belong to the few who are obsessed with the process, not just the idea of the outcome

assuming from linkedin that they have 6k (?) total employees, 2k MTS (~30% of the team, which lets say all of em code at same freq) thats a WHOPPING 15 PRs per engineer per day which means roughly ~2 PR per hour 😩😤
such a crazy velocity on shipping high quality stuffs (even with help of agents/AI). frontiers for a reason

New on our Engineering blog: Creating in-house source control.
In May, we merged around 2,500 code changes per day. In September, we merged more than 30,000 per day. As a result, we became bottlenecked by developer infrastructure built for human (rather than agent) scale.
Here, we share how we built a new version control system—and fully migrated our monorepo from git—in five months: anthropic.com/engineering/re…

RL-ed a BC-VPT agent to chop a tree with pixels only verification using SIMA-2 reward rubric, and it goes something like
1. "oh a white blocky thing, let's punch the 'log' yay"
2. "dang, why no birch in my bag… that was a sheep..."
3. "aight, I'll punch the right one somewhere"
4. until my step budget (500) is out
No log collected but 3.7-flash and Qwen-3.5 rewards success
A stronger (verifiable RL-ed) baseline also break the log only after 700 inefficient movement steps
Still so much to solve in embodied (fine-grained) verification + long-horizon task completion 🤩
Co-evolving loop has gained significant interest recently, but current methods seem to focus more on enablement across domains rather than addressing the true gaps (verifiability, etc.)
Working on this space and will share findings soon ✌️

Self-improving agents have always needed a human to write the grader.
A new AWS + HSBC paper removes that step: the grader evolves alongside the agent from 10 labeled examples and trains it about as well as ground truth.
Double Ratchet evolves the grader alongside the agent's skills, building it from small, mostly rule-based checks for 1 failure type each. A grader version is chosen for agreeing with 10 labeled examples, never for raising the agent's score.
It kept 88% to 110% of the gain that ground truth or a rubric gave the same skill loop, across code, SQL, and reports. With the safeguards removed, the grader passed 97% to 100% of outputs yet trained skills as well.

patrick retweeted

Introducing RSI-Anything: Unlocking Recursive Self-Improvement with World Models 🚀
Can AI learn to improve itself by predicting the consequences of its actions?
Built on JEPA-Anything, RSI-Anything uses world models to guide action selection and learning. Feedback improves the policy or workflow and, when needed, the world model. Validated updates carry forward to shape the next round of experience.
Across code, GUI interaction, laboratory planning, and reaction optimization:
• Code-repair success: 26.3% → 31.2%, with the coder fixed
• GUI agent task: 39.4% fewer actions, with higher completion
• Lab-planning scores: 21.80% → 46.01% over five policy versions
• Mean best observed reaction yield: 96.15% vs. 82.16% for Bayesian optimization, under the same 40-experiment budget
📄 Paper: arxiv.org/abs/2610.13912
💻 Code: github.com/Gen-Verse/RSI-Any…
Watch the video below 👇
#RSI #WorldModels #RSI #AIAgents #AIforScience #JEPA
patrick retweeted

Wrote little blogpost of what I've been working on in kernels and found small but interesting thing about it on MI210s.
erland366.github.io/blog/fli…


patrick retweeted

These days, you can pretty much solve any task by defining an eval and hillclimbing over it, instead of directly defining the deterministic/agentic workflow to solve it.
The data provider companies' entire job is to define evals for all economic activity to make the frontier models capable of doing anything.
Your job then becomes pointing frontier intelligence in the right direction - defining what to solve, and how to measure what good looks like.
Agent application interfaces will evolve to capture this. The most complex processes will still need some sort of explicit workflow builder interface, but most tasks can be compressed into goals and eval instructions.
patrick retweeted

decision models, now open and multimodal!

Today we release Open d1: two open-weight multimodal models in our d1 decision model family.
> d1-3B: text + vision
> d1-omni-600M: text + image or text + audio
> Real-time decision making anywhere, from data centers such as @nvidia DGX to RTX workstations to Jetson at the edge.
1/
