

Also on https://xitter.cf/t.co/4M0VoYFWQj
Boston, MA
Joined March 2011
- Tweets32.3K
- Following441
- Followers5K
- Likes10.1K




Last Call - join us this upcoming Thursday for a great event!

Agentic AI builders! Join us October 29th at Red Hat's Boston (Seaport) office for a jam packed meetup.
luma.com/gtk6vysw
Talks about @openclaw, Agent Memory, Sandboxing, and more!

Agentic AI builders! Join us October 29th at Red Hat's Boston (Seaport) office for a jam packed meetup.
luma.com/gtk6vysw
Talks about @openclaw, Agent Memory, Sandboxing, and more!
If you're in town for Pytorch, this is a can't miss event. Join us!

PyTorch moved from research labs to running enterprise AI. On Monday Oct 19, @RedHat, @NVIDIAAI, and @IBM host a day in San Jose: @vllm_project economics, @_llm_d_ at scale, and agents in production, with the @PyTorch maintainers behind them.
Register: luma.com/wjmtvwvw

Pete Cheslock retweeted

PyTorch moved from research labs to running enterprise AI. On Monday Oct 19, @RedHat, @NVIDIAAI, and @IBM host a day in San Jose: @vllm_project economics, @_llm_d_ at scale, and agents in production, with the @PyTorch maintainers behind them.
Register: luma.com/wjmtvwvw
Boston’s AI agent ecosystem is moving fast and we’re bringing the builders together! 🤖
Launching Agentic Builders Boston!
Speakers from @OpenClaw, @RedHat, @Google & WhiteRoom on memory, sandboxes & safety.
📅 Oct 29 | 5 PM 📍 Red Hat Seaport
🎟️ RSVP: luma.com/gtk6vysw
AI is reshaping vulnerability management at machine speed. Join us on November 12, 2026, to see how to evolve your security operating model from provenance to remediation.
Register for the virtual event. sprou.tt/1swiAuOh7ku

Pete Cheslock retweeted

We're starting to open up our product Skyway to more customers after a long time of quietly building!
Skyway helps customers negotiate, manage, and forecast AI and cloud contracts.
Learn more about it in thread. Shoot me a DM if you'd like to try it out.
Pete Cheslock retweeted

Open source is helping change the economics of #AI.
Projects like @_llm_d_ are bringing open, collaborative innovation to LLM inference, helping organizations get more from the infrastructure they already have.
Learn how: red.ht/4xh75zF
#OpenSource #AI #GenerativeAI

Pete Cheslock retweeted

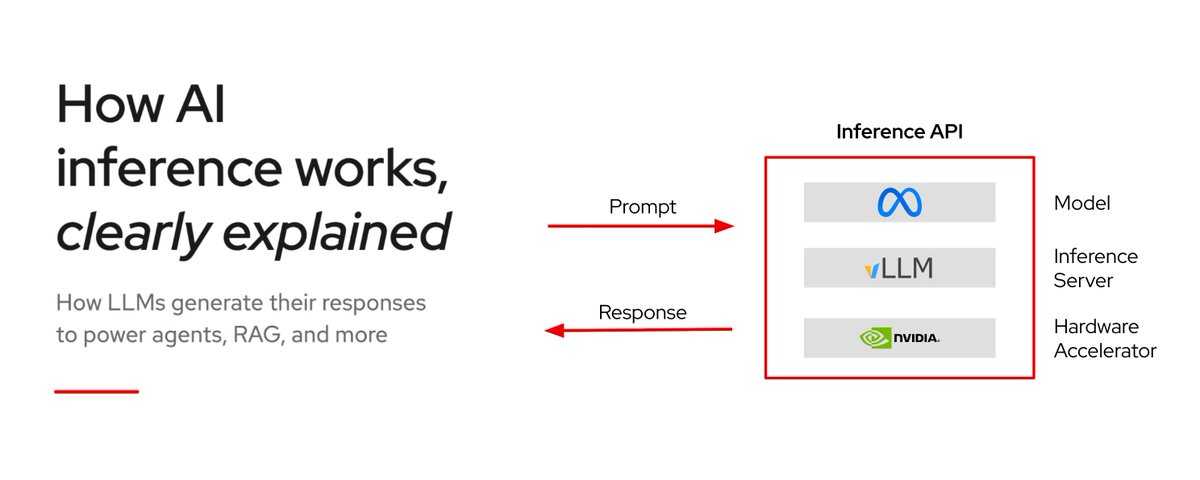
The @vllm_project & llm-d maintainers at @RedHat_AI are some of the hardest-working and leading experts on inference in the world 🚀 Everyone in the ML community can tell you how kind & helpful @robertshaw21 & @mgoin_ are. We’re grateful to occasionally collaborate with them. ❤️



Pete Cheslock retweeted

Most teams over-engineer their inference stack from day one.
They disaggregate before measuring. Add speculative decoding before concurrency stabilizes. Reach for multi-tenant AI grids when they're serving one model to one team.
The rule we keep coming back to: add one mechanism at a time, only when measurement shows the simpler setup has run out.
That's the core of Part 3 of our 𝗗𝗶𝘀𝘁𝗿𝗶𝗯𝘂𝘁𝗲𝗱 𝗔𝗜 𝗜𝗻𝗳𝗲𝗿𝗲𝗻𝗰𝗲 series, written with Fatih Nar, Yuchen Fama, and Greg Pereira: six deployment blueprints, each matched to a real traffic shape:
- Chat & copilots (TPOT-dominated, decode-heavy)
- Long-context RAG (TTFT-dominated, prefix-cache is the whole game)
- Batch pipelines (pure $/token, max batching, spot, scale-to-zero)
- Model-as-a-Service AI grids (multi-tenant, multi-model cascading)
- Sovereign-to-cloud burst (capex baseline + variable cloud opex)
- Edge on a single workstation GPU (Qwen3.6-27B fits on 96 GB)
We also cover the troubleshooting recipes that come up most in production: TPOT spikes from KV fragmentation, MoE hot-expert imbalance, KV transfer bottlenecks in disaggregated fleets, and speculative decoding drift.
📖 Part 3 - Blueprints & Troubleshooting: developers.redhat.com/articl…
Which of these blueprints is closest to your current setup? What would you change?

Pete Cheslock retweeted
Part 2 of our 𝗗𝗶𝘀𝘁𝗿𝗶𝗯𝘂𝘁𝗲𝗱 𝗔𝗜 𝗜𝗻𝗳𝗲𝗿𝗲𝗻𝗰𝗲 series is now live on Red Hat Developer: 𝘖𝘱𝘵𝘪𝘮𝘪𝘻𝘪𝘯𝘨 𝘋𝘪𝘴𝘵𝘳𝘪𝘣𝘶𝘵𝘦𝘥 𝘈𝘐 𝘐𝘯𝘧𝘦𝘳𝘦𝘯𝘤𝘦: 𝘈𝘥𝘷𝘢𝘯𝘤𝘦𝘥 𝘋𝘦𝘱𝘭𝘰𝘺𝘮𝘦𝘯𝘵 𝘗𝘢𝘵𝘵𝘦𝘳𝘯𝘴.
In Part 1, we covered prefill/decode phases and the 5D parallelism framework. Part 2 dives into the three optimization levers that deliver most of the cost and latency improvements once your parallelism layout is set:
- 𝗣/𝗗 𝗗𝗶𝘀𝗮𝗴𝗴𝗿𝗲𝗴𝗮𝘁𝗶𝗼𝗻: Not a feature to toggle on - it's a deployment topology. We share how to measure whether the prefill-to-decode imbalance in your traffic justifies the split, with 25-40% cost reductions on chat and RAG workloads in our benchmarks.
- 𝗞𝗩 𝗖𝗮𝗰𝗵𝗲 𝗔𝗿𝗰𝗵𝗶𝘁𝗲𝗰𝘁𝘂𝗿e: Tiering across HBM, DRAM, and NVMe with LMCache, the difference between prefix sharing and KV reuse (they're not the same thing), and when FP8/FP4 quantization pays off.
- 𝗦𝗽𝗲𝗰𝘂𝗹𝗮𝘁𝗶𝘃𝗲 𝗗𝗲𝗰𝗼𝗱𝗶𝗻𝗴: EAGLE 3.1 now extends gains into long-context regimes with 2x longer acceptance length than EAGLE-3. But watch out - acceptance rates collapse under constrained decoding (JSON mode, tool calls), so measure before enabling on tool-calling traffic.
One insight that keeps coming up: cache-aware routing via @_llm_d_ is what turns disaggregation from a checkbox into a working system. Round-robin leaves cache hits on the table.
Co-authored with Fatih E. Nar, Yuchen Fama, and Greg Pereira. Part 3 covering deployment blueprints and troubleshooting recipes is coming soon - follow along to catch it.
Read Part 2: developers.redhat.com/articl…

Pete Cheslock retweeted
📢 𝗧𝗵𝗲 𝗦𝘁𝗮𝘁𝗲 𝗼𝗳 𝗠𝗼𝗱𝗲𝗹 𝗦𝗲𝗿𝘃𝗶𝗻𝗴 𝗖𝗼𝗺𝗺𝘂𝗻𝗶𝘁𝗶𝗲𝘀: 𝗝𝘂𝗻𝗲 𝗘𝗱𝗶𝘁𝗶𝗼𝗻 𝗶𝘀 𝗼𝘂𝘁!
We recently launched our newsletter publicly after sharing it internally at @RedHat_AI for over a year. The response has been incredible - we’ve gained over 𝟭𝟱𝟬𝟬 𝘀𝘂𝗯𝘀𝗰𝗿𝗶𝗯𝗲𝗿𝘀! 🎉
Our goal with this newsletter is to give a clear, community-driven view of what’s happening across the model serving ecosystem, including updates from projects like @vllm_project, KServe, @_llm_d_, @kubernetesio, and beyond.
👉 Check out the June newsletter here: inferenceops.substack.com/p/…
👉 Subscribe to get future issues in your inbox: inferenceops.substack.com/
🚀 Thanks to everyone who subscribed so far!
Kudos to all contributors to this edition! Eitan Geiger, Francisco Arceo, Pete Cheslock, Jooho Lee, Pierangelo Di Pilato, Ran Pollak, Nir Rozenbaum, Yuan Tang, Wentao Ye
Hey Boston Friends. Join us next week during Boston Tech Week to learn more about llm-d, open source distributed inferencing on kubernetes.
Special thanks to @RedHat and @Google for helping to plan and sponsoring this free event!
luma.com/eqbc1gxq

Boston Friends! Come and join us for what's shaping up to be a great event!
May 28th at 5pm - Google Cambridge office.

Boston AI Devs! 🏙️
Join the llm-d meetup on May 28 during Boston Tech Week. Hear the latest in LLMs from:
🎙️ Tyler Michael Smith (@RedHatAI)
🎙️ Sean Horgan (@Google)
🎙️ Peter Tanski (@CapitalOne)
Huge thanks to @Google for the support!
🎟️ Register: luma.com/eqbc1gxq
We’re introducing an agentic OS prototype! Check out the demo and start building. sprou.tt/12sUilhIwa6

Pete Cheslock retweeted
📢 𝗧𝗵𝗲 𝗦𝘁𝗮𝘁𝗲 𝗼𝗳 𝗠𝗼𝗱𝗲𝗹 𝗦𝗲𝗿𝘃𝗶𝗻𝗴 𝗖𝗼𝗺𝗺𝘂𝗻𝗶𝘁𝗶𝗲𝘀: 𝗔𝗽𝗿𝗶𝗹 𝗘𝗱𝗶𝘁𝗶𝗼𝗻 𝗶𝘀 𝗼𝘂𝘁!
Our goal with this newsletter is to give a clear, community-driven view of what’s happening across the model serving ecosystem, including updates from projects like @vllm_project, KServe, @_llm_d_, @kubernetesio, Llama Stack, and more.
👉 Check out the April newsletter here: inferenceops.substack.com/p/…
👉 Subscribe to get future issues in your inbox: inferenceops.substack.com/
🚀 Thanks to everyone who subscribed so far!
Kudos to all contributors to this edition! Francisco Arceo, Pete Cheslock, Jooho Lee, Pierangelo Di Pilato, Nir Rozenbaum, Yuan Tang, Wentao Ye, Sasa Zelenovic
Pete Cheslock retweeted
vLLM meetup is coming to Boston on March 31!
Workshop + evening sessions covering:
- @vllm_project update
- Model compression and speculative decoding
- Agentic AI with vLLM
- Distributed inference at scale with @_llm_d_ and Kubernetes
Pre-event workshop at 3:30 PM: Deploy Llama 3.1 8B and benchmark llm-d's cache-aware routing live.
Shoutout to our sponsors: @RedHat, @IBM, @NVIDIAAI, The Open Accelerator, and @MITIBMLab!
Register here 👇
luma.com/4rmkrrb7
