


Dave retweeted

📢 Meet Qwen4-Max, your new AI teammate for work, creativity, and discovery!
Qwen4-Max is built on a new MoE architecture with native vision and a 1M-token context window.
Highlights:
- Outperforms Qwen3.8-Max with up to ~50% fewer tokens, while average cost per task drops over 60% in our internal evaluation.
- Advances real-world productivity through greater proficiency with professional tools, stronger long-horizon execution, and higher-quality deliverables.
- Handles real tasks, including 3D modeling, game development, manufacturing, finance, law, healthcare, and frontier scientific discovery.
- $1.5/M tokens for input, $4.5/M tokens for output, and $0.075/M tokens for implicit caching — all lower than Qwen3.8-Max, with implicit caching down by 70%.
The API is live on QwenCloud. You can also try Qwen4-Max on Qwen Studio, QwenWork and Qoder.
Start building today! 🚀
- Blog: qwen.ai/blog?id=qwen4-max
- API: qwencloud.com/models/qwen4-m…
- Token Plan: qwencloud.com/pricing/token-…
More to come! The open weights of smaller Qwen4 models will be released. Stay tuned. 👀


Dave retweeted

There is a hidden side to Black Holes that get rarely talked about. They can actually accelerate through SpaceTime.
This is a phenomenon called C-metric predicted by Einstein's Theory of General Relativity.
If you're running the Grok Bot desktop app, error reports go to metrics.cursor(.)sh through Sentry and usage events go through api3.cursor(.)sh via Statsig.
There's no in-app toggle for either, the only off switch is launching with SAND_DISABLE_TELEMETRY=1 via CLI.
The Statsig project it pulls config from has Session Replay enabled:
can_record_session: true,
session_recording_rate: 1.0,
privacy_mode: "min"
No recorder ships in the desktop app right now so nothing acts on it.


2
2
414
Parakeet Ultra is better than v2 with less WER but surprisingly it misfires other languages sometimes so I'm sticking with my model of the year: Parakeet TDT 0.6B v2 (English only)
2
3
295
What a beautiful model this is 163k downloads last month
huggingface.co/nvidia/parake…

171
Dave retweeted

Jensen Huang rescued me from probably living in debt the rest of my life. I was told I was one of just three hires that he approved during the pandemic, during a hiring freeze. I've never spoken to him, and only passed by him in HQ once. His personal life is frankly none of my business. But as a leader, I have yet to meet a better one. Ousting him is financial suicide, and I can only assume there is a hidden ulterior motive because I can't fathom any other reason for destroying the company's value.

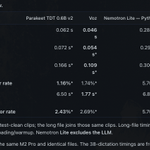
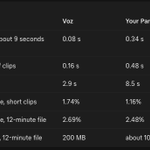
I didn't think I could get another local transcription model to run faster than Parakeet but alas, 4x faster 2x memory size and a minuscule error rate difference
Will test more.

5
2
659

And then FluidInference decides to go and do this
further benchmarking
teapaw.org/Alex_tra_memory/status…

NVIDIA Nemotron 3.5 Transcribe, ported to Apple's Core ML and Core AI on M5 Pro zero day launch.
Core ML (video): a 49.5-min, 3-person meeting → speaker-labeled transcript with word timestamps in 6.0s , 500 rtfx .
- Speech encoder + CTC head on the GPU
- Nemotron-3-Diarization on the Neural Engine, in parallel
- ~1.5 GB, no LLM
Core AI: same encoder + CTC head as a 1.3 GB .aimodel. Core AI, Core ML and PyTorch give the same transcripts on LibriSpeech (4.62 / 4.64 / 4.64% WER, 400-utt subset). 234x vs 238x on GPU.
Audio: AMI EN2002c (CC BY 4.0).
1
40
@desertantlabs thanks for an awesome release! I compared Voz with Parakeet TDT 0.6B v2 running through Core ML on my M1 Air. Voz was much faster, while v2 had slightly lower WER on my samples.
Have you tried applying your optimizations to v2 (English-only)? If so pls release :)
The best quality of life improvement this year has got to be Parakeet TDT v2 (English only) running as a local paralleled service on multiple M-series MacBooks.
I use Cloudflare for my router, and if all my devices are offline it uses a third party service as a fallback (Whisper v3 Turbo via Groq)
The cherry on top is setting up the two side-buttons on my mouse. One is a boolean toggle for record/stop record, the other executes "Enter".

3
3
490

