

Building https://teapaw.org/t.co/pRJXNjcrwa. Co-founder and CTO of Watchmouse (acquired by CA Technologies (acquired by Broadcom)).
- Tweets6.4K
- Following1.8K
- Followers1.2K
- Likes14.5K






ALT PubMed is now on Paperzilla

ALT Project page titled “OpenVision Banana: A Fully Open Recipe for Generative Visual Perception,” labeled “arXiv · 2026.” Author names and affiliations appear above buttons labeled Paper, arXiv, Code, and Models. A smiling cartoon banana holds a magnifying glass on the right.


ALT Project page titled “OpenVision Banana: A Fully Open Recipe for Generative Visual Perception,” labeled “arXiv · 2026.” Author names and affiliations appear above buttons labeled Paper, arXiv, Code, and Models. A smiling cartoon banana holds a magnifying glass on the right.
ALT Project page titled “OpenVision Banana: A Fully Open Recipe for Generative Visual Perception,” labeled “arXiv · 2026.” Author names and affiliations appear above buttons labeled Paper, arXiv, Code, and Models. A smiling cartoon banana holds a magnifying glass on the right.


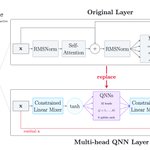
ALT Integration of the multi-head QNN block into Qwen3-30B-A3B, a 48-layer mixture-of-experts (MoE) model with hidden dimension D = 2048. Left: a standard transformer block, consisting of self-attention preceded by RMSNorm [39] and a sparse MoE feed-forward network that routes each token to 8 of 128 experts, each wrapped in a residual connection. Right: the multi-head QNN block that replaces it at the target layer. The activation x is mixed by the constrained linear transform M1 = Λ2HΛ1, bounded by a tanh nonlinearity, distributed across k = 32 independent 8-qubit QNN heads acting on disjoint 64-dimensional subspaces, and recombined by a second constrained transform M2. The block output is scaled by α and returned to the residual stream. All remaining blocks of the base model are left untouched.




ALT Three-panel diagram linking matter density and MRI intensity to local shape. A density surface leads to a tidal tensor with red compression and blue expansion directions. Four environments are classified by compressive axes: knot, 3; filament, 2; sheet, 1; void, 0.


ALT Three-panel diagram linking matter density and MRI intensity to local shape. A density surface leads to a tidal tensor with red compression and blue expansion directions. Four environments are classified by compressive axes: knot, 3; filament, 2; sheet, 1; void, 0.


