

Head of Engineering for Pexels at Canva. Ex Google. Writes about AI, coding, management, tech, business, and geeky stuff.
London, UK
Joined September 2008
- Tweets818
- Following262
- Followers3.7K
- Likes235





I'm appalled by the new trend of putting USB-C sockets on devices without implement USB-C, so only a USB-A to C cable works, a USB-C to USB-C doesn't. And there's no way to tell before you purchase these devices. Really annoying.
49
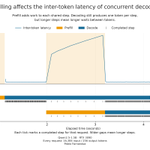
I'm starting to understand why you might want to disaggregate prefilling and decoding for LLMs. Prefilling almost feels like a batch process and decoding like an interactive process. One cares about throughput, one cares about latency. Prefilling can mess up latency.


1
1
107
This makes me really curious about monitoring these systems at scale. This sounds like fun... complex, challenging fun!
11
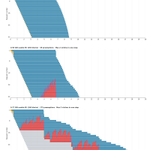
I wanted to chart the impact of preempting requests in vllm when we have a lot of prefix sharing (think production workload with the same prompt repeated). Hitting the limit of the KV cache can cause a cascade of preemptions.


4
66
Requests spent longer waiting because the scheduler couldn’t allocate enough KV space to admit them.
With a little more capacity, more requests could start, but as their histories grew during generation, some needed to be preempted.
1
28
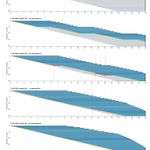
Continuing to build my intuition for inference engineering: what happens when you vary KV cache capacity while keeping everything else fixed? These charts show a synthetic workload.
What surprised me was the lack of preemptions with the smallest caches.


3
1
60
Now working on developing an intuition of prefix caching on (KV) in vLLM with Qwen2.5. This is working at the single request/conversation level, so the proper compromises of VRAM vs GPU is not completely apparent yet (prefix caching on has no consequences).


I wanted to develop an intuition of the impact of KV caching with vLLM. I think it's so fundamental we can't call it an optimization anymore. I had to add a scheduler extension to discard the KV cache after each pass to disable it, that's how fundamental it is.


2
68
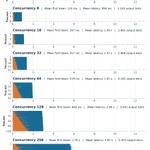
I’ve started digging into vLLM and I wanted to build an intuition about the behavior of the scheduler. I got more excited than I expected with this. I plotted request while increasing concurrency from 1 to 512, serving Qwen2.5-1.5B-Instruct to see how limits affect metrics.

2
2
90
New personal rule: these get labeled when taken out of the box, immediately. I have no idea what most of these are or were for.

34
A few years ago:
Me: ranting about my job, thinking it's bad, unfair, hard. Clients! Tech debt! Plans! Estimates!
My partner, an emergency doctor: today I had to tell a mother to say good bye forever to her daughter.
Sometimes we need a bit of perspective.
2
78
I really like @zeddotdev, but I need better devcontainer support and I'm not sure how to get the PRs to improve that reviewed yet :(
So I'm going to give VS Code another try.
52
All this talk about October being a specially bad cybersecurity month would make you believe this is a spike. I think it's more likely just a step. Next month, and the month after will have more events. I'm not looking forward to the turmoil but we are building a safer world. #ai
72
Wow... the reason my expensive 4K webcam always performed so badly was because they shipped it with a subpar cable. Now that I'm using an LTT TrueSpec cable, it works perfectly. What a way to ruin the experience by cheapening out on the cable!
1
72
AI can add code, features, designs,reports, etc at the speed of 10 humans.
But both AI and humans are bad and slow at removing anything.
The value of focus is going up. Saying no matters now more than ever. #ai
79
Finished my first training run of my micro LLM. I love how in token per seconds you can see when I'm using the computer. I also like seeing the grad clipping vs grad norms for some reason. Validation loss and training loss are essentially the same 🤔️


66
I read Computer Networks and TCP/IP Illustrated as a teenager. I loved that low level network thinking, so I was fascinating by this presentation on Homa:
ai.engineer/talks/eZ8WWZzoaR…
It's exciting!

70