
ELLIS PhD @TU_Muenchen. Prev @Mila_Quebec @UMontreal
Munich, Germany
Joined March 2021
- Tweets110
- Following344
- Followers192
- Likes718



Pinned Tweet
🚨 New Paper Alert!
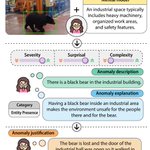
🚀 Excited to introduce CAVE: A benchmark for detecting and explaining commonsense anomalies in real-world visual environments!
Accepted at #EMNLP2025 Main Conference! 🎉
📍Join us at our poster on Nov 5, 16:30-18:00 in Hall C.

Rishika Bhagwatkar retweeted

Paper Spotlight: Do more AI agents always make a better system?
-> relative performance of multiple agents compared to single agents ranges from +80.8% to -70.0%, depending on the architecture-task alignment
"Agent effectiveness depends on alignment between coordination and task structure, and mismatched coordination degrades the performance."

Rishika Bhagwatkar retweeted

Do vision and language models, trained on entirely different data, converge toward a shared representation of the world? The Platonic Representation Hypothesis suggests they do. We take a closer look.
Rishika Bhagwatkar retweeted
Paper Spotlight: Do AI agents notice what is right in front of them?
If the full solution to a task is injected into the agent's environment, e.g. a solution.sh file in the working folder on Terminal-Bench,
-> Agents find it in about 80% of runs
-> They use it in only 37-50% of runs


Rishika Bhagwatkar retweeted
Paper Spotlight: What if we studied AI the way biologists study animals?
In 2019 (at the time of GPT-2!), researchers argued in Nature for a new science: "machine behaviour".
Today, it looks like a pretty good prediction of the current scientific field around frontier systems:

Rishika Bhagwatkar retweeted

What does an LLM think of you?
LLMs pick up the slightest implicit cues about users. Often, they refuse to say who they think the user is.
In our new preprint, we show how to read and change these hidden beliefs. Turns out they even affect whether the model refuses
New paper🧵
Rishika Bhagwatkar retweeted
Paper Spotlight: What does an AI agent do when nobody gives it a task?
The authors gave Claude Code a body on an unknown island, said only "Begin", and left it alone for 30 hours.
It climbed hills, built towers, invented basketball and bowling, and ran physics experiments.

Rishika Bhagwatkar retweeted
Agents are evaluated with ever more detailed metrics, but why don't we study how their own configuration shapes performance?
We study this on 4 scientific tasks, by varying 5 parts of the agents configuration across 18,000+ runs.
Here are my favorite findings:


Rishika Bhagwatkar retweeted
FineVision was just accepted to NeurIPS! Big thanks to all my co-authors, excited to present it at the conference


Rishika Bhagwatkar retweeted

We will have two poster presentations and one workshop poster at #ECCV2026 in Malmö🇸🇪!
Please come and say hi if you are interested in topics related to multi-modal learning. Details in the thread👇
🤖 Made with AI

Rishika Bhagwatkar retweeted

Excited to share that our paper on Concept Bottleneck Sparse Autoencoders (CB-SAE) will be presented at CVPR 2026 tomorrow!
CB-SAE combines sparse autoencoders (SAEs) with concept bottlenecks to make multimodal LLMs more interpretable and steerable.
Rishika Bhagwatkar retweeted
Honored to be recognized as an Outstanding Reviewer at CVPR 2026!

We are grateful to all of the 17,491 reviewers who helped make #CVPR2026 possible. We are especially pleased to recognize the following Outstanding Reviewers, whose high-quality reviews (as judged by their Area Chairs) placed them among the top 5% of reviewers.


Rishika Bhagwatkar retweeted

As @karpathy just highlighted, a single poisoned version of LiteLLM up for less than an hour was enough to exfiltrate SSH keys, cloud credentials, API keys, crypto wallets, and more from anyone who ran pip install. The attack used a malicious .pth file, a mechanism that executes automatically when Python starts. No explicit import needed. Just installing the package was enough.
This is a textbook software supply chain attack. But it also points to something deeper that we've been studying. AI systems don't just depend on code. They depend on training data, collection environments, and model artifacts an entire supply chain that is largely unaudited. And unlike malicious code, which can (in theory) be inspected, poisoned data and weights are far harder to detect.
In our paper "Malice in Agentland," we formalize three threat models that target different layers of this agentic AI supply chain:
1. Data poisoning - an attacker controls a fraction of the training traces used to fine-tune an agent
2. Environmental poisoning - malicious instructions are injected into the webpages or tools an agent interacts with during data collection
3. Weight poisoning - a pre-backdoored base model is fine-tuned on clean data, and the backdoor survives
The results are amazing. Poisoning as few as 2% of collected traces is enough to embed a trigger-activated backdoor that causes an agent to silently leak confidential user information with over 80% success. And the defenses we tested 2 guardrail models and one weight-based defense all failed to catch it.
The LiteLLM attack stole credentials. An equivalent attack on the AI supply chain could implant persistent behavioral backdoors agents that behave normally until a specific trigger phrase appears, then silently exfiltrate data, manipulate outputs, or take unauthorized actions. And because these backdoors live in model weights rather than source code, they evade the inspection tools we rely on today.
As we know, every dependency you install could be hiding a poisoned package deep in its tree. The same is true for every dataset, every pretrained checkpoint, every training pipeline. As AI agents gain autonomy, securing the full stack code, data, environments, and weights is no longer optional.
Read our full Paper: arxiv.org/abs/2510.05159


Software horror: litellm PyPI supply chain attack.
Simple `pip install litellm` was enough to exfiltrate SSH keys, AWS/GCP/Azure creds, Kubernetes configs, git credentials, env vars (all your API keys), shell history, crypto wallets, SSL private keys, CI/CD secrets, database passwords.
LiteLLM itself has 97 million downloads per month which is already terrible, but much worse, the contagion spreads to any project that depends on litellm. For example, if you did `pip install dspy` (which depended on litellm>=1.64.0), you'd also be pwnd. Same for any other large project that depended on litellm.
Afaict the poisoned version was up for only less than ~1 hour. The attack had a bug which led to its discovery - Callum McMahon was using an MCP plugin inside Cursor that pulled in litellm as a transitive dependency. When litellm 1.82.8 installed, their machine ran out of RAM and crashed. So if the attacker didn't vibe code this attack it could have been undetected for many days or weeks.
Supply chain attacks like this are basically the scariest thing imaginable in modern software. Every time you install any depedency you could be pulling in a poisoned package anywhere deep inside its entire depedency tree. This is especially risky with large projects that might have lots and lots of dependencies. The credentials that do get stolen in each attack can then be used to take over more accounts and compromise more packages.
Classical software engineering would have you believe that dependencies are good (we're building pyramids from bricks), but imo this has to be re-evaluated, and it's why I've been so growingly averse to them, preferring to use LLMs to "yoink" functionality when it's simple enough and possible.
Rishika Bhagwatkar retweeted

🧵New paper: "Lost in Backpropagation: The LM Head is a Gradient Bottleneck"
The output layer of LLMs destroys 95-99% of your training signal during backpropagation, and this significantly slows down pretraining 👇

Rishika Bhagwatkar retweeted

Continual learning should be viewed through the lens of the stability-plasticity dilemma, and solving it requires rethinking learning architectures. I argue why in my first continual learning blog: itsnva7.substack.com/p/conti…
Rishika Bhagwatkar retweeted
I am excited to share the past 5+ years of my PhD work on continual reinforcement learning at @Cohere_Labs on March 3rd! Doina and I spent significant time and thought developing this framework; we believe this holds the key to continual learning.

Our Reinforcement Learning group is excited to welcome @itsNVA7 for a presentation on "The permanent and transient framework for continual reinforcement learning" on Tuesday, March 3rd.
Thanks to @rahul_narava and Gusti Triandi Winata for organizing this event! 🔥
Learn more: cohere.com/events/cohere-lab…

Rishika Bhagwatkar retweeted
Excited to share that I'll be at #NeurIPS2025 from Dec 2-7, presenting two of my works 🚀
1. LLM Agent Safety Against Prompt Injections
2. Anomaly Detection Using VLMs
I’m looking for PhD positions starting Fall 2026.
Happy to connect, feel free to DM :)
Poster details in 🧵


Excited to share that I'll be at #NeurIPS2025 from Dec 2-7, presenting two of my works 🚀
1. LLM Agent Safety Against Prompt Injections
2. Anomaly Detection Using VLMs
I’m looking for PhD positions starting Fall 2026.
Happy to connect, feel free to DM :)
Poster details in 🧵
1. CAVE: Commonsense Anomalies in Visual Environments
📍Women in ML on 2 Dec, Exhibit Hall C from 6-9 PM
📍LLM-Eval Workshop on 7 Dec, Room 2 from 2-3:30 PM
paper link: aclanthology.org/2025.emnlp-…
2. Indirect Prompt Injections: Are Firewalls All You Need, or Stronger Benchmarks?
📍Lock-LLM Workshop on 6 Dec, Room 1AB from 12-1:00 PM
paper link: arxiv.org/pdf/2510.05244