

Focused on AI work.
New York City
Joined October 2014
- Tweets2.6K
- Following858
- Followers450
- Likes2K


Rob K retweeted
TransformerLens 3.0 is out! 🎉 Congrats to collaborator and friend Bryce Meyer (no X 😢) for getting it across the line. Details in the Open Source Mechanistic Interpretability slack: opensourcemechanistic.slack.…
TransformerLens 3.0 is out! 🎉 Congrats to collaborator and friend Bryce Meyer (no X 😢) for getting it across the line. Details in the Open Source Mechanistic Interpretability slack: opensourcemechanistic.slack.…
Rob K retweeted

Sphinx is helping businesses unlock their sprawling and disparate datasets -- read more in Fast Company’s profile of how we’re rethinking AI for data science ⬇️
fastcompany.com/91405220/why…

Rob K retweeted

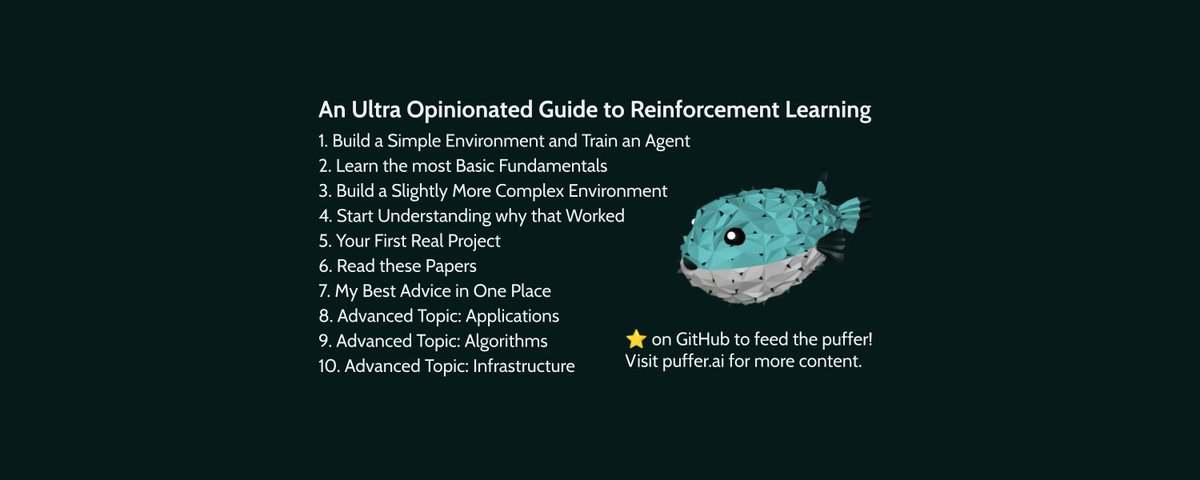
Joseph's guide provides clear tactical advice on how to learn RL.
Give it a read. Build Environments. You can just learn RL.

Rob K retweeted

🧵Chain-of-Thought reasoning in LLMs like Claude 3.7 and R1 is behind many recent breakthroughs.
But does the CoT always explain how models answer?
No! For the first time, we show that models can be unfaithful on normal prompts, rather than contrived prompts designed to trick them.

Rob K retweeted

🚨 IAPS is hiring 🚨
We seek Researchers / Senior Researchers to join our team to identifies concrete interventions that could manage risk and secure benefits of advanced AI.
One role is fully remote and can be done in most countries, the other will be in DC.
App due Oct 21

Outer loss transmits very limited bits of information through the info-theoretic bottleneck of the training process... so yes, if your function family (eg wetware brains) priors mesa-optimizers relatively densely, no sparsely delivered outer loss (death in the EEA) suffices...

Disagree. "Gradient-descenting" is the wrong verb as it implies attribution to kindness-likelihood is primarily the optimizer. The text that is to be predicted matters; the etiology of the ontology implicit in the training distribution *was* shaped by m-s of proteins and IS kind
Rob K retweeted

The Microsoft / CrowdStrike outage has taken down most airports in India. I got my first hand-written boarding pass today 😅


What does fine tuning do to models? Do representations transfer between base and chat versions? Find out in the next episode of @Connor_Kissane and Rob project!

New post with @robertzzk, @ArthurConmy, & @NeelNanda5: Sparse Autoencoders (usually) Transfer between Base and Chat Models! This suggests that models' representations remain extremely similar after fine-tuning.

Rob K retweeted

New post with @robertzzk, @ArthurConmy, & @NeelNanda5: Sparse Autoencoders (usually) Transfer between Base and Chat Models! This suggests that models' representations remain extremely similar after fine-tuning.
My feed is nothing except COLM paper acceptances.
I get, it you got in, nice job. I'm very proud of you.
Sparse Autoencoders help us understand the MLPs of LLMs, but what's up with attention?
Find out in our new paper with @Connor_Kissane and @NeelNanda5!
Sparse Autoencoders help us understand the MLPs of LLMs, but what's up with attention?
In our new paper with @NeelNanda5, we introduce Attention Output SAEs to uncover what concepts attention layers learn. Further, we use them to find novel insights previously out-of-reach!🧵

New attention sparseautoencoders post dropped.
$1000 bounty to whomever find the best attention circuit!

Great post from my scholars @Connor_Kissane
& @robertzzk!
SAEs are fashionable, but are they a useful tool for researchers? They are! We find a deeper understanding of the well-studied IOI circuit, and make a circuit analysis tool
$1000 bounty to whoever finds the best circuit!
Rob K retweeted

Anyone know of any publications or research on changing out the activation function of trained transformer network? Looking to replace GELU with ReLUs in a trained model with minimal finetuning/postprocessing

