

multimodal @thinkymachines. I also like to climb rocks and throw pottery. https://xitter.cf/t.co/5Er4j39K71 (he/him)
San Francisco, CA
Joined November 2008
- Tweets622
- Following1K
- Followers15.3K
- Likes1.3K






Pinned Tweet
We are so back!

People talk, listen, watch, think, and collaborate at the same time, in real time. We've designed an AI that works with people the same way.
We share our approach, early results, and a quick look at our model in action.
thinkingmachines.ai/blog/int…
Rowan Zellers retweeted

I’ve joined @thinkymachines to work on safety & alignment.
The default trajectory is that as AI gets more powerful, control over it will concentrate in the hands of a few. I’d rather build safety systems that let control over AI be shared widely.
Longer thoughts below.
Rowan Zellers retweeted

Releasing weights indiscriminately isn't safe. Neither is keeping capable models inside a few labs.
We think there's a path between them. We haven't mapped all of it. Our new post covers the part we can see: how we assessed Inkling, and why access should widen in stages.
thinkingmachines.ai/blog/a-s…


Rowan Zellers retweeted
Today, we are releasing Inkling-Small.
Inkling-Small achieves comparable performance to Inkling at a quarter of its size. It features 276B total parameters, 12B active. We are making the full weights available.
thinkingmachines.ai/news/ink…
Fine-tune it on Tinker today, or chat with it in text, image, and audio on Tinker Playground.

Rowan Zellers retweeted

Inkling is very good at using tools to solve vision tasks.
In this demo, Inkling relies solely on Python tools to generate segmentation masks, iteratively zooming in, cropping, and refining object boundaries.
Plug Inkling into your multimodal agent workflow!
huggingface.co/thinkingmachi…

Rowan Zellers retweeted
Today, we are introducing Inkling.
Inkling reasons efficiently across text, image, and audio modalities. We are making the full weights available.
thinkingmachines.ai/news/int…
Available today for fine-tuning on Tinker. Play with it in the Inkling Playground. 🧵

Rowan Zellers retweeted

Inkling is a 975B-41B(A) MoE model that natively reasons across modalities (text, images and audio). It is intelligent and versatile🌱.
I’ve had so much fun building it alongside an incredible team over the past few months and proud to openly share this work.
🤖 Made with AI

Today, we are introducing Inkling.
Inkling reasons efficiently across text, image, and audio modalities. We are making the full weights available.
thinkingmachines.ai/news/int…
Available today for fine-tuning on Tinker. Play with it in the Inkling Playground. 🧵
Rowan Zellers retweeted
We're building AI that people and organizations can shape and make their own. AI should extend our will and judgment instead of neglecting it; enabling that is the technical challenge we are working to solve.
thinkingmachines.ai/blog/the…

Rowan Zellers retweeted

A super long overdue (3+ years?) post on scaling laws.
Compute is expensive. Scaling laws are a way to help us reason about the optimal compute allocation between data and model size before committing to a large run.
The post covers what scaling laws predict, how compute-optimal allocation works, why Kaplan et al. and Chinchilla disagree, and how data limits + fitting details make extrapolation tricky.
lilianweng.github.io/posts/2…
Grants for research on interactivity, realtime video/audio full duplex evals, and safety
We are offering grants of $100,000 + Tinker credits to researchers advancing the field of human-AI interactivity. Submit your proposals by June 19th!
thinkingmachines.ai/news/int…
Rowan Zellers retweeted

Big congratulations to Dr. @ziqiao_ma, well deserved! 🎉👏
Excited for your new chapter at @thinkymachines!


Rowan Zellers retweeted

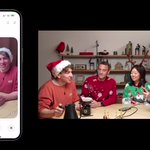
P.S. The demo is basically my life at thinky: I start to cut coffee, @liliyu_lili is visually prompt-injecting my human intelligence with sweet snack every day, and I've gained weight since joining TML.
Rowan Zellers retweeted

Congrats Rowan and Thinky team on the cool release!
I remember you mentioned having a v different vision of multimodal interactions a few weeks ago @rown so this is what that looks like! 🆒
It’s exciting to see this release going beyond just a single model, showcasing truly different native multimodal interactions too.
A couple things from the nicely written blog really resonate with me:
1. people are most effective when they can collaborate with AI the same way they do with other people
2. existing interfaces limit human inputs (esp multimodal ones) to the model, and this input limit needs to be lifted to unlock much better interactivity
The blog also reminds me of the fun and challenging discussions with @shannonzshen and others on what “scaling collaboration” can look like. we made an initial attempt describing our vision: arxiv.org/pdf/2510.25744
It’d be great to see more human centric evaluations of the model/system/interface too — looking forward to it🥂


Rowan Zellers retweeted

We started Thinking Machines to advance human-AI collaboration, and this is our first bet on what that looks like. Most labs treat autonomy as the goal and interactivity as scaffolding around a turn-based core. We think the way we work with AI matters as much as how smart it is. Interactivity has to be in the model, and it has to scale with intelligence rather than trail behind it.
thinkingmachines.ai/blog/int…

Rowan Zellers retweeted
In the past few months, we had a lot of fun (and stress 😅) to produce 12 versions (+ many subversions) and 137 pages in our training run log book.
Turns out human-human collaboration is important to improving human-AI collaboration. 😊


People talk, listen, watch, think, and collaborate at the same time, in real time. We've designed an AI that works with people the same way.
We share our approach, early results, and a quick look at our model in action.
thinkingmachines.ai/blog/int…
Rowan Zellers retweeted

Very excited to share a preview of what we’ve been working on!
People talk, listen, watch, think, and collaborate at the same time, in real time. We've designed an AI that works with people the same way.
We share our approach, early results, and a quick look at our model in action.
thinkingmachines.ai/blog/int…
Rowan Zellers retweeted

Thinky’s new interaction models perform search in the background when listening and responding so you don’t notice!
Also per request: Spoiler Alert 🚨
Rowan Zellers retweeted

My first share since joining @thinkymachines. Fun working with this team on real-time multimodal interaction. Vision in turn-based models felt like flipping through photos — continuous video is a different problem.
Visual proactivity is essential — grateful to have worked on this alongside @liliyu_lili, @rown , and the rest of the team!
People talk, listen, watch, think, and collaborate at the same time, in real time. We've designed an AI that works with people the same way.
We share our approach, early results, and a quick look at our model in action.
thinkingmachines.ai/blog/int…
Rowan Zellers retweeted

I'm excited to share some of our work at @thinkymachines. As models get more intelligent, the bottleneck is increasingly how quickly and seamlessly we can access their intelligence, and today we are sharing a preview of how we think about human-AI collaboration.
People talk, listen, watch, think, and collaborate at the same time, in real time. We've designed an AI that works with people the same way.
We share our approach, early results, and a quick look at our model in action.
thinkingmachines.ai/blog/int…
Our interaction model is the first general video+speech model that's visually proactive. It was super fun working on this with @liliyu_lili / @saurabh_garg67 / @AndreaMadotto and others - after countless versions it was amazing when visual interruptions suddenly worked!

We’re interested in AI systems that can collaborate in real time, without relying only on artificial turn boundaries.
For audio, this feels natural: listen, speak, interrupt, update.
For video, we think an important version of this is visual proactivity — models that respond when something happens visually:
“Tell me when I start slouching.”
“Count my pushups.”
“Say stop when the person stops doing X.”