

Neuroscience of Action & Volition (studying self-initiated movements) was a lab at @NeuroSpin_91 @UNICOG1 Now moved to @Brain_CU @FreeNeuro
Paris-Saclay🇫🇷/Orange CA🇺🇸
Joined October 2017
- Tweets116
- Following268
- Followers151
- Likes362


Schurger Lab 🧠🤌 retweeted

Israel is committing some of the worst atrocities of our age, live-streamed on a daily basis.
The politicians and media outlets who facilitated this obscenity must be held to account.
Israel does this because it believes it will be allowed to. It is correct.

Schurger Lab 🧠🤌 retweeted

If you are a student interested in building the next generation of AI systems, don't work on LLMs


Schurger Lab 🧠🤌 retweeted
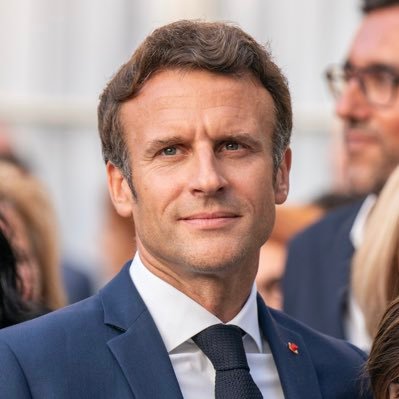
Voici l’image du cerveau la plus précise de l’Histoire, obtenue grâce au scanner IRM du CEA, le plus puissant au monde.
C’est une avancée majeure et un espoir immense pour l’étude de notre santé. Félicitations à l’équipe du projet Iseult.
Fierté française !
Schurger Lab 🧠🤌 retweeted

Daniel Dennett (28th March 1942 - 19th April 2024)
RIP
Dennett on how to criticise wisely

Schurger Lab 🧠🤌 retweeted

"The secret of happiness is: Find something more important than you are and dedicate your life to it."
Daniel Dennett (March 28, 1942 - April 19, 2024)

Schurger Lab 🧠🤌 retweeted

very saddened to hear of Dan Dennett's passing. he was a transformative influence on my thinking about a great many topics, and a kind and generous man. his presence will be missed dearly by a great many people.
Schurger Lab 🧠🤌 retweeted
A new experiment for English speakers with a personal computer and 15 minutes to spare : help us understand how shapes are encoded ! Click here
neurospin-data.cea.fr/exp/Ba…
Schurger Lab 🧠🤌 retweeted

# explaining llm.c in layman terms
Training Large Language Models (LLMs), like ChatGPT, involves a large amount of code and complexity.
For example, a typical LLM training project might use the PyTorch deep learning library. PyTorch is quite complex because it implements a very general Tensor abstraction (a way to arrange and manipulate arrays of numbers that hold the parameters and activations of the neural network), a very general Autograd engine for backpropagation (the algorithm that trains the neural network parameters), and a large collection of deep learning layers you may wish to use in your neural network. The PyTorch project is 3,327,184 lines of code in 11,449 files.
On top of that, PyTorch is written in Python, which is itself a very high-level language. You have to run the Python interpreter to translate your training code into low-level computer instructions. For example the cPython project that does this translation is 2,437,955 lines of code across 4,306 files.
I am deleting all of this complexity and boiling the LLM training down to its bare essentials, speaking directly to the computer in a very low-level language (C), and with no other library dependencies. The only abstraction below this is the assembly code itself. I think people find it surprising that, by comparison to the above, training an LLM like GPT-2 is actually only a ~1000 lines of code in C in a single file. I am achieving this compression by implementing the neural network training algorithm for GPT-2 directly in C. This is difficult because you have to understand the training algorithm in detail, be able to derive all the forward and backward pass of backpropagation for all the layers, and implement all the array indexing calculations very carefully because you don’t have the PyTorch tensor abstraction available. So it’s a very brittle thing to arrange, but once you do, and you verify the correctness by checking agains PyTorch, you’re left with something very simple, small and imo quite beautiful.
Okay so why don’t people do this all the time?
Number 1: you are giving up a large amount of flexibility. If you want to change your neural network around, in PyTorch you’d be changing maybe one line of code. In llm.c, the change would most likely touch a lot more code, may be a lot more difficult, and require more expertise. E.g. if it’s a new operation, you may have to do some calculus, and write both its forward pass and backward pass for backpropagation, and make sure it is mathematically correct.
Number 2: you are giving up speed, at least initially. There is no fully free lunch - you shouldn’t expect state of the art speed in just 1,000 lines. PyTorch does a lot of work in the background to make sure that the neural network is very efficient. Not only do all the Tensor operations very carefully call the most efficient CUDA kernels, but also there is for example torch.compile, which further analyzes and optimizes your neural network and how it could run on your computer most efficiently. Now, in principle, llm.c should be able to call all the same kernels and do it directly. But this requires some more work and attention, and just like in (1), if you change anything about your neural network or the computer you’re running on, you may have to call different kernels, with different parameters, and you may have to make more changes manually.
So TLDR: llm.c is a direct implementation of training GPT-2. This implementation turns out to be surprisingly short. No other neural network is supported, only GPT-2, and if you want to change anything about the network, it requires expertise. Luckily, all state of the art LLMs are actually not a very large departure from GPT-2 at all, so this is not as strong of a constraint as you might think. And llm.c has to be additionally tuned and refined, but in principle I think it should be able to almost match (or even outperform, because we get rid of all the overhead?) PyTorch, with not too much more code than where it is today, for most modern LLMs.
And why I am working on it? Because it’s fun. It’s also educational, because those 1,000 lines of very simple C are all that is needed, nothing else. It's just a few arrays of numbers and some simple math operations over their elements like + and *. And it might even turn out to be practically useful with some more work that is ongoing.
This Post is from an account that no longer exists. Learn more
Schurger Lab 🧠🤌 retweeted

Kinda interesting 🧐 that most of the DeSci OGs were neuroscientists before, there must be something going on with that 🤯🧠
@Shamburgularara @hebbianloop @oraclide
-> maybe because once you study the brain, everything else seems easier? 😂 (Quote)
Schurger Lab 🧠🤌 retweeted
I applied yesterday as a TA!🙂
I encourage to NOT MISS this opportunity w/ @neuromatch!🤗
I had a great time last summer being a Computational Neuroscience 🧠TA for PhD & MSc students from EMEA 🌍
Looking forward to being a Deep Learning TA this year! 🤖
New #opensource tracks: Climate Science 🌱 & NeuroAI⚡!


We heard you loud and clear! Lots of people said they needed a little more time to get their TA applications in!
➡️ TA applications will be extended by one week! ⬅️
Applications will be due March 24, midnight in the last time zone on Earth.
buff.ly/3PaEQys
Schurger Lab 🧠🤌 retweeted
📣 Good news!
As negotiations between the 🇪🇺 EU and 🇨🇭 Switzerland have been officially launched today, researchers based in Switzerland can now once again apply for ERC grants.
Read more 👉 erc.europa.eu/news-events/ne…

Schurger Lab 🧠🤌 retweeted
A fake paper… in Frontiers… why am I not surprised? This predatory publisher once again reveals its true nature.

The rat with the big balls and the enormous penis – how Frontiers published a paper with botched AI-generated images
@FrontiersIn
scienceintegritydigest.com/2…

Schurger Lab 🧠🤌 retweeted
LARPing sick 🤧🤒 from my bed
If you wanna cheer me up #Anons do you know any 📣
🎨 Artist who use #GenerativeAI
🤖 Researcher who use or research on #LLM
👾 Entrepreneur who uses LLMs for their company
⚖️ Attorneys specialized in IP, AI, Web3
LFG 🥷 pls share 🔁 and DM me
Schurger Lab 🧠🤌 retweeted

📢Appel à #volontaires pour participer à l'étude "7TlayersVA" 🧠menée par @zhanminye #chercheuse à @NeuroSpin_91 @UNICOG1 au @CEAParisSaclay @CEA_Joliot. ➡️Répondez au questionnaire de pré-recrutement : groom.cea.fr/groom2/Voluntee…

Schurger Lab 🧠🤌 retweeted

The Brain Institute is hiring a Research Coordinator. Please share this to spread the word! We will fully consider all applications received by March 31. Apply here: chapman.peopleadmin.com/post…

Schurger Lab 🧠🤌 retweeted

Very happy to be starting the Brain, Body and Technology Lab (BBT Lab) at the @DondersInst Sensorimotor Neuroscience Department.
New lab website is now online! brainbodytech.com/
And I will be posting a PhD position for my ERC project soon. Watch this space!

Schurger Lab 🧠🤌 retweeted

We have 2 open calls for a fully-funded PhD in #NeuroAI at Ecole Normale Supérieure:
1. euraxess.ec.europa.eu/jobs/6… w/ Pierre Bourdillon
2. euraxess.ec.europa.eu/jobs/6… w/ Yair Lakretz.
Schurger Lab 🧠🤌 retweeted
Open call for 2023 internships (potentially followed by PhD) in our Brain & AI team at Meta:
metacareers.com/jobs/8490547…
Strong experience in {deep learning, signal processing, neuroscience} (2 out of 3) required.
Application from under-represented groups encouraged.
Schurger Lab 🧠🤌 retweeted

A PhD position in Artificial Intelligence and Cognitive NeuroScience
“Linking Linguistics and Brain Dynamics with Deep Language Models” at @ENS_ULM
Co-supervised with @JeanRemiKing
Schurger Lab 🧠🤌 retweeted

It's happening again! I was a TA there two editions ago and it was a wonderful (intense) experience. Don't miss it! #NMA #neurotwitter #compneuro #DNN #AI
NMA 2023 course dates have been established!
The two courses (Computational Neuroscience and Deep Learning) will happen in parallel for 3 weeks, starting July 10th and ending July 28th. The portal for students and TAs applications will open soon, for now save the date! 🧠💻🌎🌍🌏

ALT Pink box with the text: “July 10th - 28th 2023, Everywhere on Earth. SAVE THE DATE NEUROMATCH ACADEMY 2023. Subscribe to the mailing list on academy.neuromatch.io to be updated on the registration opening!”. On the right hand side the photo of an open book and on the top the NMA logo.