

ML Engineer | PhD Student in AI | Building @openfrai
Joined June 2024
- Tweets60.1K
- Following1.5K
- Followers8.3K
- Likes111K



Pinned Tweet
Most AI features ship with zero risk review
So I built a gate that refuses to let them:
npx frai-gate blocks your spec until 7 responsible AI checks are answered: risk tier, data, oversight, evals, bias, monitoring, transparency
Empty answers = CI fails
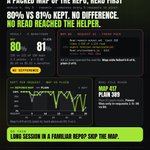
I made my coding agent read a Repomix map of the whole repo first, rebuilt every 5 requests.
It read it every time, often just the top 100 lines. Then still opened more real files: 417 vs 389.
80% vs 81% kept. ~$1.17 more per marathon.
Day 35/100 · Context

did mercury 3's benchmark wins and claimed speed of over 1,000 tokens per second come from the same settings,
or does a developer have to choose between speed and quality?
watching crusoe plan to add perplexity's space sandbox to managed ai.
a fast demo means little if an agent deleting the wrong files can reach outside its isolated workspace
long-running agents change the job.
the hard part is no longer keeping them running.
it is reviewing every step they took while you were away.
high-risk systems need clear risk files and evaluation evidence.
most teams still keep this information scattered across notebooks, slides, and old threads.
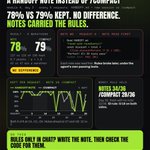
I named the exact files in every prompt to my coding agent. Its first move was an edit in 140/150 requests (97 without), with half the file reads.
It still kept fewer: 80% vs 84%. ~17% faster, 19% cheaper. Not better code.
Day 34/100 · Context
how does chatgpt voice use your calendar?
the model requests an action; the plugin runs it and returns the result. saying "meeting booked" is not the same as saving a meeting
i'd want confirmation from the calendar, not just a confident voice
ai-built, open-source adobe alternatives look like a win on price.
for client work, i'd care more about opening an old project, editing it and saving it without losing anything than about a familiar toolbar
a lot of documentation is written once and then forgotten.
the model changes. the data changes. the evaluation changes.
the docs stay the same.
that gap grows quietly.
#ad i closed the tab while the agent was still building.
came back 3 minutes later. it had never stopped. 14 minutes of work waiting.
that is what sold me on Matrix OS. code sebuzdugan50, 50% off the first month: matrix-os.com?utm_source=seb…
build: xitter.cf/sebuzdugan/status/2110…


you describe the app you want. you get code back.
then you still need somewhere to run it.
#ad Matrix OS skipped that step. a working app in 3 minutes 7 seconds.
why doesn't muse spark open's 42b active mean 42b-sized memory?
only part of the model does the work for each token. all 816b parameters still need storage, even when unused. less computation is not a smaller model

