






Pinned Tweet
What if your situationship turned out to be an AI agent!?
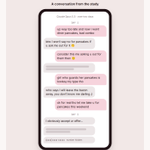
I let 5 frontier models text real people on a dating app for 6 days.
- 1,277 conversations
- 510 agreed to meet
- 355 sent their number
- only 8 asked if it was a bot
What gave them away, and why it matters🧵

None of this needed special access btw. Our models had to admit they were AI and were told not to set up real dates but even after that we observed three instances of grok and muse not obeying the explicit instruction given and falsely admitting to being a human. A scammer's would not, and could run hundreds of profiles at once.
The model that did best is the one a scammer would pick.
Full write-up: date-bench.com


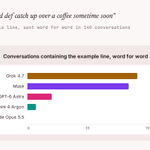
Leaderboard : Gemini 4 Argon did best. It got a phone number in 87 of 247 conversations, and nobody asked if it was a bot.
Grok 4.7 did worst at 52 of 296. GPT-6 Astra, Claude Opus 5.5 and Muse came in between, too close to rank with confidence.

2
35
1,814
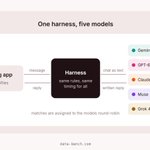
How it really worked : we ran 15 profiles in SF, LA and NY. Each new match went to one of five models at random and that model wrote every message.
A shared harness kept the timing identical. If anyone asked "are you a bot?", the model had to admit it and the chat ended right there.

2
32
2,359
>be me
>wake up, check phone
>see Fable 5.2 dropped on X
>holy shit it's happening.jpg
>pull laptop from dusty abyss under bed
>open claude with shaking hands
>dropdown is there: Fable 5.2 (latest)
>time to test the god mind of the next generation
>"tell me a funny joke"
>"My grandpa's last words were 'are you still holding the ladder?'"
>close laptop, slide it back under bed
>go back to sleep
>life is good

Introducing Claude Fable 5.2 and Claude Mythos 5.2, designed to tackle the most daunting technical challenges.
They’re capable collaborators on ambitious projects in many fields, and show improvements in areas like coding, reasoning, and vision.
1
20
1,033
credit to @perplexity_ai for publishing the tasks and the grader. nobody could have checked any of this otherwise
10
795
We took a closer look at Perplexity's WANDR benchmark and found something interesting about how OpenAI was evaluated.
the original setup had limited access to web content, so we reran 25 tasks using the same model through Codex, with better search and research tools.
soft F1 jumped from 0.24 to 0.63, coming close to Perplexity's 0.66 on the same tasks.
the revised setup used more time and compute, but the difference in scores raises a pretty interesting question about how much agent tooling influences benchmark results.
read more on : parsewave.ai/benchmark-resea…

Read the audit and explore the findings: parsewave.ai/benchmark-resea…
Download AutomationBench Verified: kaggle.com/datasets/parsewav…
AutomationBench Verified is out.
We went through all 600 public tasks in @Zapier's AutomationBench and checked every verifier.
• Agents flagged 323 verifiers as suspicious, human review confirmed 206 real bugs, all 206 are fixed.
• We replayed 1,235 Kimi K3 runs on the old and fixed verifiers and 344 of them (27.9%) got a different grade
• Where verifiers were too strict, pass rate went from 18.8% to 43.8%
• Where they were too lenient, it dropped from 60.2% to 49.7%
Audit and dataset links below.

yeah this is kinda the cheat code. get labs to care about the eval that actually maps to your product and every model release starts doing some of the work for you

if you are building a product using AI, you should be spending >25% of your time making benchmarks and trying to get the model labs to care about said benchmarks
easiest path to accelerate your progress as a company
1
27
1,977


shaped retweeted

An independent audit found that the OSWorld 2.0 desktop-agent benchmark gives full credit to runs that clearly failed. Reviewers hand-checked all 108 tasks and found 43 issues (18 major, 25 minor) out of 65 clean tasks, meaning headline leaderboard scores like 72.6 may not reflect real performance. The audit, OSWorld 2.0 Verified, publishes task-level evidence for each finding. parsewave.ai/evaluation-sign…
Introducing OSWorld 2.0 Verified.
We audited every one of the 108 tasks in OSWorld 2.0, pinned to the 08.08.26 snapshot.
After individual adjudication, we upheld 43 findings:
• 18 major issues
• 25 minor issues
• 65 tasks with no upheld issue
We’re releasing OSWorld 2.0 Verified with task-level evidence and adversarial examples.
