


Pinned Tweet
Coming to @NeurIPSConf 2026: Can you learn dynamics from noisy observations 𝘄𝗶𝘁𝗵𝗼𝘂𝘁 𝗻𝘂𝗺𝗲𝗿𝗶𝗰𝗮𝗹 𝘀𝗶𝗺𝘂𝗹𝗮𝘁𝗶𝗼𝗻? Yes, and just as accurately as you can with simulation!
Paper: arxiv.org/abs/2606.16138
Code: github.com/lindermanlab/helm…
Thread🧵
Henry Smith retweeted

1/5 Cryo-EM gives high-resolution RNA structures, but only when high Mg²⁺ freezes out their motion.
At physiological conditions, RNAs are dynamic and 3D reconstruction fails. Can we still learn their folding equilibria?
New preprint: yes, straight from the raw particle images👇
Henry Smith retweeted

I'm excited to share this new work led by @smithhenryd! We develop Helmholtz-SDE, a faster and more accurate simulation-free inference algorithm for latent SDEs. The animation below speaks for itself!

Coming to @NeurIPSConf 2026: Can you learn dynamics from noisy observations 𝘄𝗶𝘁𝗵𝗼𝘂𝘁 𝗻𝘂𝗺𝗲𝗿𝗶𝗰𝗮𝗹 𝘀𝗶𝗺𝘂𝗹𝗮𝘁𝗶𝗼𝗻? Yes, and just as accurately as you can with simulation!
Paper: arxiv.org/abs/2606.16138
Code: github.com/lindermanlab/helm…
Thread🧵
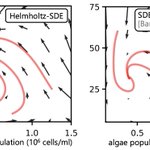
Does this matter for real systems? On experimental predator-prey data (Blasius et al., 2020), Helmholtz-SDE recovers the cycle period and predator lag (6.9 / 1.7 days vs. empirical 6.7 / 1.7), while SDE Matching’s dynamics decay to a fixed point.

This work was done in collaboration with my wonderful advisors Brian Trippe @brianltrippe and Scott Linderman @scott_linderman.
Interested in learning more about Helmholtz-SDE?
Reach out via DM or visit our poster in Sydney on Wednesday, Dec 9 from 5-8 PM AEDT!
Henry Smith retweeted

Same marginals. Different dynamics.
Gaussian Flow Dynamics + Gauge Matching learn temporal structure beyond one-time marginals, enabling more flexible, simulation-free neural SDE learning in continuous physical time.
arxiv.org/abs/2610.04390
#PhysicalTime #SDE #ML #GenAI

Thank you for the highlight @canaesseth!
We are excited that simulation-free VI for latent SDEs can match the performance of simulation-based VI at a fraction of the runtime. 🏎️💨

Make sure to also check out the excellent paper from @smithhenryd @brianltrippe and @scott_linderman on Helmholtz-SDE that studies analytic approximations to the optimal gauge.
arxiv.org/abs/2606.16138
Henry Smith retweeted
Make sure to also check out the excellent paper from @smithhenryd @brianltrippe and @scott_linderman on Helmholtz-SDE that studies analytic approximations to the optimal gauge.
arxiv.org/abs/2606.16138
Henry Smith retweeted

Softmax attention is expressive, but its KV cache grows with sequence length. Linear attention keeps a fixed state size, but is less expressive.
In our #COLM2026 paper, Switching Linear Attention (SwiLA) gets the best of both worlds by switching among multiple linear maps 🧵

Henry Smith retweeted

How do we make quasi-Newton optimization methods practical for modern deep learning?
New preprint with @jooko303 @tanyaisanumber @gowerrobert on SoftServe -- a quasi-Newton method that designed for non-convex objectives, while also scaling to very large neural networks.

ALT SoftServe: a scalable quasi-Newton method for deep learning
Henry Smith retweeted

Joining the NeurIPS celebration: our curse of ambiguity paper will be a spotlight 🎉
We show that high entropy tokens need
1. More capacity to store
2. Larger embeddings to be represented
3. More training steps
4. More samples to reduce sampling noise
Scaling laws study performance averaged over all tokens in the data; our work zooms in and sheds some light onto which tokens are harder to learn 🔬


We often ask how hard a task is for an LLM to learn, but what about individual tokens?
Our new paper w/ @scott_linderman @hyundongleee digs into that question and reveals a curse of ambiguity: contexts with multiple possible next tokens are harder for LLMs to learn.


Henry Smith retweeted

New @open_rss blog (rs-station.github.io/2026/08…) on a question we’ve been thinking about a lot: what information about a molecular ensemble survives measurement and processing? @PilarCossio2 @EmilThomasen
A fuzzy cryo-EM map is not itself an ensemble. But an averaged measurement is not limited to an average structure either.
We use ensemble resolution to frame the better question: what differences between molecular distributions can the data actually distinguish?

Henry Smith retweeted
We often ask how hard a task is for an LLM to learn, but what about individual tokens?
Our new paper w/ @scott_linderman @hyundongleee digs into that question and reveals a curse of ambiguity: contexts with multiple possible next tokens are harder for LLMs to learn.
An exciting paper from @nate_diamant and @brianltrippe about how to fine-tune your generative model to be consistent with known feature distributions!

New preprint arxiv.org/abs/2606.19496 with @brianltrippe : kernel Calibrating Generative Models (kCGM). kCGM is a way to post-train generative models so their samples match a target distribution of user-chosen features e.g. molecular fingerprints or regulatory activity profiles 🧵