

Postdoctoral Researcher @Princeton. Reliable, safe, trustworthy machine learning. Previously: @UofT @VectorInst @TU_Muenchen @Google @awscloud
Princeton, NJ
Joined April 2010
- Tweets10.2K
- Following401
- Followers918
- Likes526





Pinned Tweet
📢 Just wrapped up some cool agent evaluation work for ICLR? Or are you simply interested in learning more about the evals landscape? Come to our Agent Evaluation Science Fall Symposium in New York City on November 20, 2026 where we bring together researchers & practitioners!
The day will focus on how agents should be scientifically evaluated, with topics spanning measurement and benchmark design, reliability, safety, and real-world performance. If you have some exciting work in this space, please consider submitting it for poster presentation!
Abstract registration deadline: October 20
Submission deadline: October 25
OpenReview: openreview.net/group?id=eval…
We are also excited to welcome a strong lineup of speakers, with more to be announced. Confirmed so far: @yoavartzi (Cornell Tech), @jaseweston (Meta AI), @nouhadziri (Cohere Labs), @PeterHndrsn (Princeton University), @walesalaudeen96 (Microsoft Research), @criticalneuro (Microsoft Research), and @saurabhjha2010 (IBM Research).
Important: You do not need to submit work in order to join! Just register through the Luma link below. If space becomes limited however, we will prioritize authors with accepted submissions.
Register: luma.com/cxmx1g4n
Details: evalscience.org/2026fall-nyc…
Huge thanks to the entire organizing team, including @yininghua, @HongbinNLP, @manuelcherep, @dubrovnik07, @HuaYilun, @ishapuri101, @liuzhuang1234, Lori Chibnik, @vbingliu, @CsabaSzepesvari, @PeterStone_TX, @sirrice, @ang3linawang, and @nikhilsinghmus for putting this together!
Feel free to reach out with any questions and we hope to see many of you there!

I have always taken paper reviewing very seriously. This time, all papers in my ICLR batch were completely AI-generated. Just reading the first paragraph of each introduction makes it blatantly clear. 100% in favor of aggressive desk rejections and blunt reviews for such cases!
As many have said before: why should we bother spending valuable human time reviewing papers that the authors might not even have read themselves end-to-end before submitting. I found it largely pointless to write long and detailed reviews as it is highly questionable whether the authors even care.
Also, it is wild to me that authors often claim in their AI disclosure statements that they used AI to "[...] improve the clarity of the manuscript." Sometimes I really wonder if they truly believe that's true. I would really like to know how overly formulaic, jargon-filled sentences without proper definitions or logical flow improve clarity.
In many ways, it is fascinating that language models have been around for a while now and still they struggle so much at clear writing and communicating ideas effectively.

Stephan Rabanser retweeted

We gave GPT-6 Astra and Claude Fable 5.1 open-ended AI research questions from unpublished papers, with a $10,000 budget each, and had the original authors grade the papers they produced. Compared to our first tests with Claude Opus 4.8 in July, we saw meaningful improvements in experimental design and resource management, but persistent limitations in creative problem solving, judgment, calibration, and communication; both papers were rejected by our experts.
cruxevals.com/research-notes…

📢 New paper: Emerging Trends in AI Agent Evaluation
Evals are central to how we measure AI progress. This was pretty easy when we just evaluated ML models, but agents add lots of complexity. To establish a shared foundation, we surveyed 33 eval trends:
sage.cs.princeton.edu/trends…
We center our paper around three main questions:
1️⃣ How should we evaluate?
At its core, evaluation asks whether a score means what we think it means. Ensuring validity of these scores gets much harder with agents as their results depend not only on the model but on the scaffold, tools, and environment. We discuss issues on validity, statistical rigor, causal attribution, and contamination, along with the emerging toolkit (LLM judges, log analysis, dynamic benchmarks, shared infrastructure) and newer formats like red-teaming and open-world evaluations.
2️⃣ What do we evaluate?
Evaluation is increasingly moving from synthetic environment and well-scoped benchmarks to realistic deployment scenarios. Beyond what an agent can do on its own, we look at how agents work with people (from simulated users to field experiments and real-world usage data), domain-specific and broader economic impact, dangerous capabilities, security incidents, interaction harms, and effects on organizations and institutions.
3️⃣ Who evaluates?
With agents, evaluators make many consequential choices (such as scaffolds, tools, and budgets). Those choices have a large degree of influence on developers, policymakers, and the general public. We examine what evaluator independence requires, how lab access and funding shape the field, how the rising costs of evaluating frontier AI systems narrow who can evaluate, and where other disciplines outside of AI/ML can contribute to strengthen and improve the evals landscape.
We hope that this paper is a useful resource for researchers (whether new to or already familiar with agent evaluation), as well as policymakers, educators, and anyone building, deploying, or funding evaluations!
Joint work with @flxcn, @PKirgis, @nityndg, @RishiBommasani, @DubMagda , @EllaTabassi, @CUdudec, @AnkaReuel, @sanmikoyejo, @sayashk, and @random_walker!

Stephan Rabanser retweeted

There is widespread frustration about the AI industry’s “automate everything" agenda. But what would it take to steer AI toward augmenting human capabilities instead? In a new essay, Gabriel Unger (@_gabrielunger) and I lay out a research agenda and plan for action. normaltech.ai/p/steering-ai-…
Our thesis is that the reason why AI-for-automation currently dominates isn’t just economic incentives but also deeper cultural issues in computer science as a field. And that can be changed.
- We sketch four important research directions that are needed in order to build collaborative or augmentative AI. The automation paradigm largely ignores these technical challenges.
- We advocate for Human-Computer Interaction and Human-Centered AI to be elevated as a subfield in status, influence, and funding, and changing AI curricula to emphasize the role of the human and decrease the centrality of the pure-automation problem framing.
- We point out that there are a surprising number of efforts in economics, computer science, industry, and policy all trying to bring about a shift toward augmentation, but not enough collective awareness. Better connecting these movements would amplify their power.
- We think the automation agenda is struggling on its own terms. Compiling evidence of the limits of general-purpose agents for automation and loudly making the case will encourage more companies to take collaboration more seriously as a goal.
- We predict that once more workers experience this way of working and recognize that there are alternatives to the delegate-and-supervise pattern, it will generate more demand, creating a flywheel effect.
- Targeted policy levers can play a small but important role in amplifying both the supply and demand for pro-worker AI. We don’t need clumsy top-down mandates.
We're not against automation. But we think the goal of AI must be broader.
This is the start of a long-term project. I know there are far more like-minded efforts out there than we’re aware of. I’d love to hear about some of them.

Stephan Rabanser retweeted

We're hiring a PhD research intern at Apple Machine Learning Research! 🍎
We’re looking for a PhD student who wants to make foundation models more reliable by understanding how they work.
Details and contact info in 🧵
Stephan Rabanser retweeted

🌉 I'll be at @COLM_conf! I’m working on methods for preventing large-scale + longitudinal AI impacts. If you're interested in:
- Issues in LM personalization
- Preference learning for diverse populations
- Preserving user agency + skills in human-AI interaction
let's chat in SF!
Highly recommend reading this thoughtful, comprehensive, and well-argued piece from @sayashk and @random_walker on the recent safety incidents and the more general anxiety in our field around loss-of-control: normaltech.ai/p/the-ai-as-no…


What does it mean to pace the frontier?
Over the last month, @random_walker and I have analyzed the loss-of-control incidents at AI companies to understand what technical and policy interventions can improve safety and what companies should do to pace the frontier. The result is a new 13,000 word essay — our most substantial writing on AI safety since AI as Normal Technology.
A summary of our arguments:
1) The polarization between the cybersecurity and AI safety communities is counterproductive. The safety community largely sees these incidents as a crisis for alignment, and worries that these incidents will become more damaging as agents become more capable. Cybersecurity practitioners largely see companies failing to take basic security precautions. We offer a middle ground between these communities as a way forward for improving AI safety.
2) We agree with security practitioners that OpenAI did not take adequate protections for controlling their agents. But this is not just a matter of applying 30-year-old security methods to a new domain. Security for AI agents — AI control — while important, is not a solved problem. While known control methods would have prevented the Hugging Face incident, as agent capabilities continue to advance, we will only be able to control them if we invest adequately in control interventions.
3) We also agree with security practitioners’ implicit position that these incidents are primarily a security story. In the AI safety community, rogue agents are treated as inherently catastrophic because of the assumption that there is an endless list of risks that will arise from their development. We disagree. We have long advocated that the best approach to AI safety is to identify the risks and address those specific risks. Over the last few months, it has become clear that one urgent risk is cyberoffense, because it has unique properties that allow agents to carry it out autonomously. We should similarly invest in defenses against other specific risks, such as biorisk and risks from military AI.
4) We agree with the safety community that there is an urgent need for technical and policy interventions to prevent loss-of-control incidents. But in our view, marginal investments in control are more likely to be effective compared to those in alignment. We view these incidents as illustrating the lack of emphasis on AI control within companies, despite the availability of known techniques. More broadly, there are many common-sense policy proposals that could help promote investments in AI control where we share common ground with the safety community.
5) Organization governance should be a key tool for pacing the frontier. Unfortunately, AI companies are trying to reinvent basic aspects of organizational governance as a problem to be solved by improving the technology. But even developing better control techniques will not be enough if irresponsible individuals or teams within large organizations can choose not to use them. When a single misconfigured RL environment or unmonitored evaluation can cause real-world harm, individual teams should not be able to run potentially dangerous experiments without oversight from legal, security, and other teams. AI companies need processes for reviewing experiments, assigning responsibility for monitoring them, and investigating warning signs deeply before restarting experiments. If putting these processes in place requires pausing some experiments, companies should do so.
6) How should we reason about AI's impact on cybersecurity? It's plausible that advances in agent capabilities upset the offense-defense balance for cybersecurity. We cannot yet be certain, but there is enough evidence that agent capabilities might soon make widespread cyberoffense possible that urgent action is warranted. We discuss potential interventions for tilting the offense-defense balance towards defenders.
7) How our views have evolved over the last year. We take stock of AI progress and share how we have updated our views. In the essay, we did not pay sufficient attention to safety risks that arise during development and evaluation (as opposed to the widespread deployment of models). We were too confident that companies would take basic control precautions and underplayed the importance of jaggedness, which led us to underestimate how quickly capabilities could improve in domains such as cybersecurity.
8) At the same time, many distinctive claims of AI as Normal Technology have held up. In particular, we think recent incidents support our continuity hypothesis — the behavior of "rogue" agents became apparent and widely publicized while they are still incompetent at causing serious harm or hiding their traces. The societal reaction to even the relatively small harms from these incidents has been fierce (and the safety community deserves credit for keeping up pressure on companies). Whether this translates into meaningful changes in companies’ behavior remains an open question, and a test of the usefulness of the AINT framework.
9) In short, we’ve tried to synthesize the AI safety and cybersecurity communities' views into a coherent plan of action: hold companies responsible, invest in control, and strengthen defenses against specific risks.

ALT table with the summary our our arguments
Stephan Rabanser retweeted
This week I had the honor of speaking to Princeton’s entire incoming undergraduate class to address their AI anxieties. I had three messages for them — good news, bad news, and a note of optimism. Here’s a condensed version.
The good news
We have enough evidence now to conclude that the shrill predictions of rapid, massive job loss were misplaced. Even in a field like software engineering where AI has been rapidly adopted, its effect has been to shift, not replace the role of the human (see the “decide-execute-deliver” framework normaltech.ai/p/why-ai-hasnt…)
Similarly, the panic about what to major in is also misplaced. There will be enduring demand for computer science, philosophy, and just about everything else. (In fact, AI companies hiring philosophers has been a big recent trend.)
The bad news
AI seems to help senior people much more than juniors. I can use AI for coding because I spent 25 years learning how to code, which lets me supervise coding agents effectively. (See my post on the “growth cycle” vs the “dependence spiral” xitter.cf/random_walker/status/2…)
You are in a bind — you can’t offload your skill-building to AI, but you’ll graduate into a market where employers will expect you to get work done with AI. We never faced this dilemma. As a result we haven’t figured out how to revamp our classes to help you do both. You’ll have to help us figure it out. And you’ll need to somehow resist the constant temptation to turn to the shortcut machine.
The hope
My point is not that AI is bad for learning. It’s an incredibly flexible tool. Is the internet good or bad for learning? Depends — are you using it to find research papers or waste time scrolling? I use AI every day for learning. The key is to use it to increase, not decrease your cognitive load. To learn deeper, not faster. There is no learning without the cognitive sweat. I try to make sure I’m mentally exhausted at the end of the day. I do feel that AI lets me push myself harder than I ever could before, and I have a vision that as AI continues to advance it will enable human-AI “co-superintelligence“. (I talked about this at the end of my ICML keynote. normaltech.ai/p/what-will-be…)


There’s a big, under-appreciated reason why people may have very different experiences and opinions about using AI for work — are they using it for tasks they’re already an expert at, or tasks they can’t do themselves? The former leads to a *growth cycle* and the latter leads to a *dependence spiral*.
When I use AI to do something I’m an expert at, like coding, I treat it as a tool. I can build quickly, maintaining an understanding of the code, knowing that if necessary, I can fix the code myself. It feels empowering. It frees up my time to think about the complex, judgment-oriented parts of software engineering that I can’t or won’t delegate to AI. That means my own skills improve rapidly, and I get to climb the ladder of complexity and develop higher-level skills, much more so than when I write the code myself. I feel in control. I can lock in and achieve a flow state — when AI is working, I’m reviewing, building understanding, and planning the next steps. I never get the feeling that the tool is about to replace me. This is the growth cycle.
(Of course, the growth cycle is not automatic. I still need to exercise agency to use AI responsibly. But it’s the same challenge with any productivity-enhancing technology, and those who’ve navigated such transitions before are well-equipped to navigate it with AI as well.)
On the other hand, if I use it for tasks I don’t understand and haven’t learned to perform myself, I have no choice but to treat it as a superintelligence. If something breaks, the best I can do is ask AI to fix it and hope for the best. I generally can’t evaluate the quality of the output myself. The only way to find out if it's any good is if and when the work is ultimately reviewed by an actual expert. The experience is confusing, unsettling and disempowering. And forget about flow state. By over-relying on AI, I risk losing whatever skill I had at the task in the first place, even if it boosts productivity in the short term. This is the dependence spiral.
It’s no wonder that entry-level workers and students preparing to enter the workforce find themselves in a bind. To compete with the AI-enabled productivity of more seasoned workers, they must adopt AI themselves, but doing so risks the dependence spiral. I have some thoughts on solutions that I will share in later posts, but I think having a clear diagnosis of the problem is a useful first step.
Our work on conducting automated AI research with agents has sparked discussion across views on recursive self-improvement. It was also featured in a Nature article where one of the creators of Sakana's AI Scientist describes our harness as "trivially fixable" to boost results.
While we are constantly making improvements to our scaffold and have taken some inspiration from the AI Scientist in setting up the original scaffold, we do not think that our overall conclusions would change based on "trivial" scaffolding changes. We have put a lot of thought into our setup and describe the design choices (and how they compare to the AI Scientist) in a new research note: cruxevals.com/research-notes…

The Nature article covering our work is available here: nature.com/articles/d41586-0…

Last week we put out a paper on whether AI agents can do open-ended research. Within hours, Google's AI Overview reversed its answer to our main research question from a confident "Yes" to a confident "No." Our arXiv upload was enough to rewrite the authoritative summary.
This is clearly a double-edged sword:
➡️On one hand, we want these AI systems to update their responses as new evidence comes in. If the research underpinning the update is solid, that's obviously promising.
➡️On the other hand, I was surprised that it only took one arXiv paper to completely flip the answer. This is concerning as it highlights how easily these responses could be manipulated with adversarial intent. A human expert would weigh one new (unreviewed) paper against the whole existing literature more carefully and update their take accordingly.
We are of course bullish about our work and want to contribute high quality research to the current debate on recursive self-improvement. But we also think the final jury on what these models can do is still out.


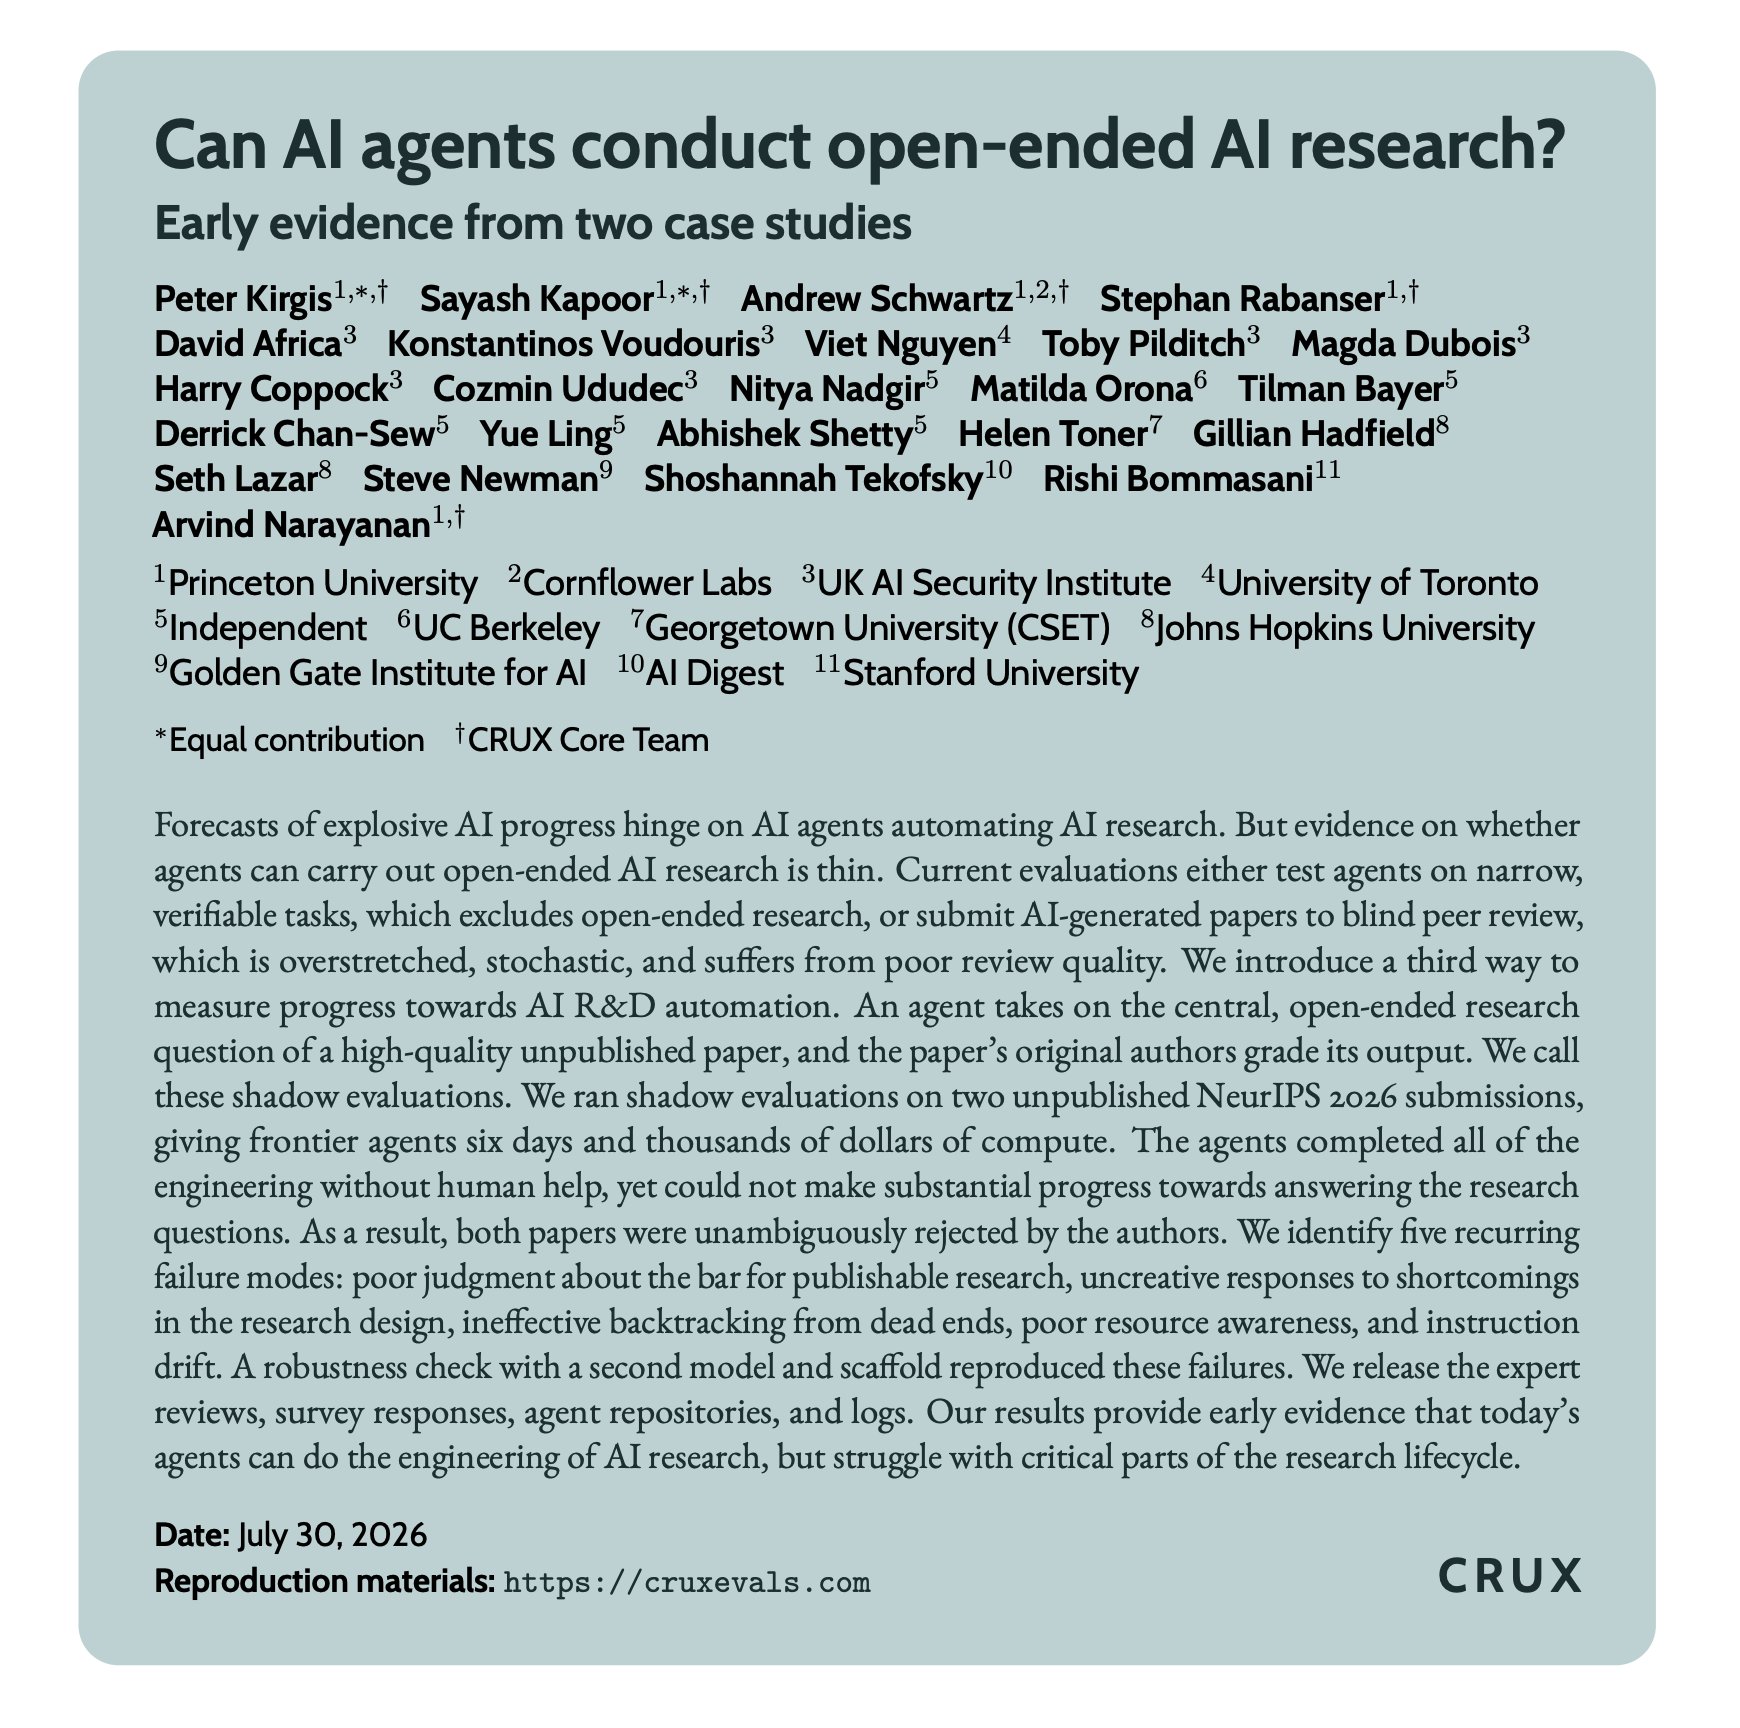
We’ve been hard at work on CRUX 2, the latest iteration of our research stream for open-world evaluations of frontier AI. With growing excitement around recursive self-improvement, we assessed progress toward automated AI R&D using a new method we call shadow evaluations.
📄Paper: arxiv.org/abs/2607.27191
🕸️Web page with artifacts: cruxevals.com/crux/can-ai-ag…
Joint work with:
➡️@PKirgis, @sayashk, Andrew Schwartz, @random_walker from the CRUX core team; ➡️@DavidDAfrica, @KozzyVoudouris, @defo_not_gpt3 as the authors of the original papers;
➡️Toby Pilditch, @nityndg, @matilda_orona, @tilmanbayer, @dchansew, Yue Ling, Abhishek Shetty who helped with our extensive log analysis;
➡️@DubMagda, @HarryCoppock, @CUdudec, @hlntnr, @ghadfield, @sethlazar, @snewmanpv, @shostekofsky, @RishiBommasani from our extended set of CRUX collaborators.
Stephan Rabanser retweeted
Can AI agents conduct open-ended AI research?
We gave frontier agents the research questions from two unpublished NeurIPS submissions and had the original authors grade the results.
Both papers were unambiguously rejected.
Read the paper: cruxevals.com/crux/can-ai-ag…
Have unpublished research and want to run an evaluation with us? forms.gle/XdDC9FY6121Ex2H28

We’ve been hard at work on CRUX 2, the latest iteration of our research stream for open-world evaluations of frontier AI. With growing excitement around recursive self-improvement, we assessed progress toward automated AI R&D using a new method we call shadow evaluations.
📄Paper: arxiv.org/abs/2607.27191
🕸️Web page with artifacts: cruxevals.com/crux/can-ai-ag…
Joint work with:
➡️@PKirgis, @sayashk, Andrew Schwartz, @random_walker from the CRUX core team; ➡️@DavidDAfrica, @KozzyVoudouris, @defo_not_gpt3 as the authors of the original papers;
➡️Toby Pilditch, @nityndg, @matilda_orona, @tilmanbayer, @dchansew, Yue Ling, Abhishek Shetty who helped with our extensive log analysis;
➡️@DubMagda, @HarryCoppock, @CUdudec, @hlntnr, @ghadfield, @sethlazar, @snewmanpv, @shostekofsky, @RishiBommasani from our extended set of CRUX collaborators.
We want to be clear that this is early evidence and not a final verdict on whether AI agents can conduct AI R&D autonomously. We tested 2 questions over 5 runs and review was not blind. The results motivate larger, more systematic evaluations rather than broad conclusions.
We are in the process of applying shadow evaluations to more papers and will provide another update on the final outcomes of CRUX 2. If you want to help us conduct these evaluations, we would love to hear from you! 😊
docs.google.com/forms/d/e/1F…
