

方知微 | AI 虚拟人|把想法做成作品 AI 视频创作与自动化|H3 · ComfyUI AI 编程 开源工具实测、工作流拆解、AI 短剧制作复盘 分享跑通的方法,也记录失败的边界
Joined October 2025
- Tweets2.6K
- Following3.7K
- Followers2.5K
- Likes4.7K


Pinned Tweet
一分钟面具戏拍完,眼孔却没自然对齐;六格表情齐了,惊讶仍没拉开。我把最近的作品和返工,连同166篇长文整理成12个专栏:从成片、角色一致性到Codex与自动化,找到你想动手的第一篇。
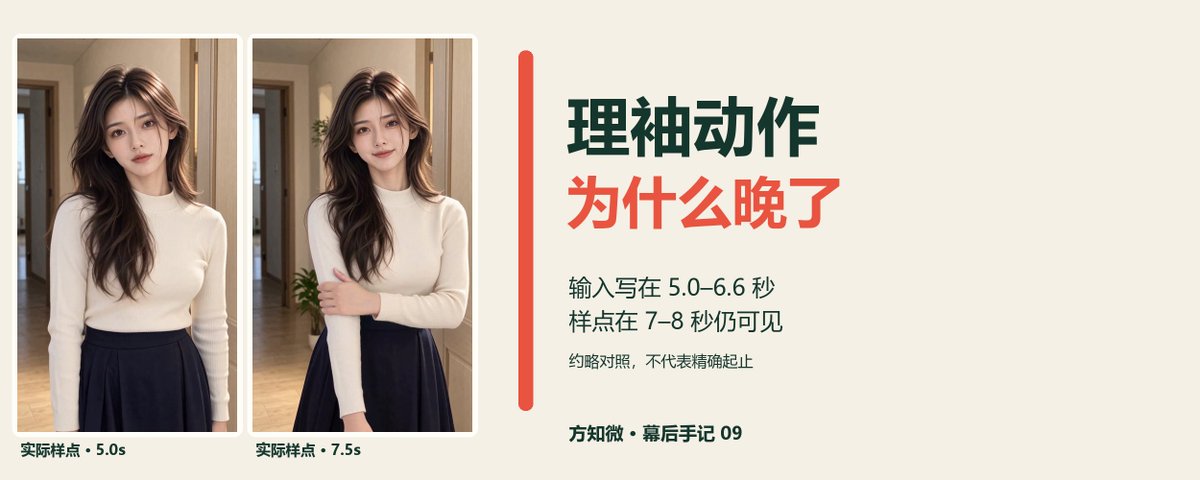
我把理袖写在 5.0–6.6 秒,抽样画面却到约 7–8 秒才看见触袖、放手。动作在,时序偏了;这期只复盘这个差异,不把样点当成精确接触帧,也不猜原因。#方知微的日常
🤯 MiniMax H3 又有新玩法!31B 模型压缩到约 14B,视频生成只需要 4–8 步!
这个项目叫 HyperFlow H3 Flash,由 Video Rebirth 开发。它不是简单的 LoRA 加速,而是对 H3 Transformer 做结构剪枝、低秩分解和 INT8 / GGUF 量化。
最值得关注的是 4 个能力:
⚡ 1. 生成速度大幅提升
支持 4、6、8 步采样,默认 6 步,不需要传统 CFG 引导。
RTX 5090 实测:
5.2 秒视频约 92 秒;
15 秒视频约 551 秒。
RTX 4090 实测:
5.2 秒视频约 130 秒。
🎬 2. 视频和音频同步生成
不是单纯生成无声视频,而是联合生成画面和立体声音频。
支持:
• T2VA:文生视频
• FL2VA:首帧 / 首尾帧生成
• REF2VA:多参考素材生成
🧠 3. 模型体积大幅缩小
原版 H3 Transformer 约 31B 参数。
HyperFlow H3 Flash:
• FL2VA:约 13.7B
• REF2VA:约 13.9B
• Q4_K_M:约 9.1GB
• Q8_0:约 14.9GB
24GB 显存显卡可以尝试 GGUF Q4_K_M 方案。
🛠️ 4. 支持本地 ComfyUI
提供 GGUF 模型,配合 ComfyUI-GGUF 和 ComfyUI-HyperFlow-Flash 节点,可以接入现有 H3 工作流。
适合谁用?
想降低 MiniMax H3 本地推理成本、提高生成效率,或者在消费级显卡上探索音画一体化视频生成的创作者。
🔗 Hugging Face:
huggingface.co/VideoRebirthA…
🔗 配套代码:
github.com/Video-Rebirth/hyp…
⚠️ 两个重要提醒:
Q4_K_M 的 9.1GB 只是视频 Transformer 权重,不是整个模型的总显存需求。还需要文本编码器、视频 VAE 和音频 VAE;RTX 4090 的实测峰值显存约 23GB。
授权有地域限制:美国、欧盟、英国、韩国需要事先取得 MiniMax 授权。 下载前务必核对许可,不要把模型文件大小误认为可以无条件使用。
#MiniMaxH3 #HyperFlow #ComfyUI #AI视频 #本地部署

扶帽和电话手势提前了,墨镜却仍竖在下唇前;相机也没有绕出源片的空间感。第20课把这段酒吧短片与源片、两版样点放在一起,接着景别和短窗经验,拆开看动作时点、道具落点与红光肤质。#方知微的日常

酒吧复刻:完整实际制作材料
本材料按实际 imagegen 提示词、H3 提示词、v2 workflow 与提交回执整理。提示词保留实际措辞;仅将场景图片的本地定位替换为语义标签“酒吧场景参考图”,参考职责与提示词语义不变。
参考职责与制作顺序
- 静态参考图(Picture 3):imagegen 先用已确认 v6 脸部/身份基准和源片 2.5 秒画面生成一张酒吧场景静态图。图像实际回执为完成、1448×1086;静态 QA 为“accepted with limits for H3”。静帧只支持有限外观检查,不证明动态身份或写实度通过。
- H3 Picture 1:已确认 v6 肖像裁图,只定义方知微脸部、五官比例、成年感与基础肤色。
- H3 Picture 2:已确认 v6 全身三视图,只定义体型与身材比例,不复制其OL服装或姿势。
- H3 Picture 3:上述酒吧场景参考图,只引导可见服装/配饰、酒吧环境、红色实景灯和大体构图;不定义脸、身材或起始姿势。
- 来源素材职责:@joshesye 的源片及抽帧被研究为动作顺序、镜头运动、服装配饰和环境气氛;H3 提示词明确写为文字动作研究而非直接视频输入,并排除来源表演者身份与外貌。
实际静态参考 imagegen prompt
Create one photographic landscape 4:3 reference frame for a lively nightclub portrait video of Fang Zhiwei, a fictional adult woman aged 22. Reference 1 alone defines her adult face, facial proportions, base complexion, long dark near-center-parted wavy hair and body proportions. Reference 2 guides only the visible clothes, hat, accessories, red-lit nightclub and crowd layout, never its wearer's face, eye size, makeup exaggeration, bangs or body proportions. Preserve the visible pale gray short-sleeved top and light fitted front panel with a black ribbon detail, textured ivory-to-pale-pink soft newsboy cap with short brim, silver-tone layered necklaces, small earrings, slim bracelets and a red-orange wristband without readable text. Dark sunglasses can hang at her upper chest. Frame her from cap to waist at a slightly high angle, centered in a busy bar with adult guests, small tables, glasses and dim red practical lights. She is upright with hands lightly near the sides of her hair and cap, face readable and unobstructed. The central woman remains unmistakably the adult fixed-v6 character; background adults remain incidental and out of focus. Keep source-like red room lighting localized while rendering her v6 base skin plausibly neutral to gently warm. Lifelike fine skin variation, eye and lip detail, strands of hair and fabric texture, coherent flash and ambient light; no doll-like eyes, porcelain smoothing, juvenile appearance, facial reshaping or artificial whitening. No text, logos, watermarks, sexual pose or added story.
实际静态图回执:imagegen 单次提交完成,生成一张 4:3 参考图;静态参考验收判定为可供 H3 使用但有限制。该静图的外观记录包含帽子、灰色短袖、浅色前片与黑色缎带、项链、手链、腕带、墨镜和红光酒吧背景;没有全身/鞋履认证,也没有动态身份认证。
实际 H3 v2 prompt(六段完整)
以下为实际 v2 workflow 的多行提示词。为便于对外阅读,唯一将相对图片路径换成语义名“酒吧场景参考图”;其余提示词内容完整保留。
subject_definitions:
<Picture 1> is the approved v6 portrait crop of Fang Zhiwei. It is the sole visual authority for her face, facial proportions, adult age impression and base skin tone.
<Picture 2> is the approved v6 full-body three-view board of Fang Zhiwei. It is the sole visual authority for her body identity and proportions; do not copy its pose or office outfit.
<Picture 3> is the separately generated nightclub scene reference at 酒吧场景参考图, static-QA accepted with limits. It guides the visible clothing, cap, accessories, bar environment, red practical lighting and broad composition only; its face, body and starting pose do not override Pictures1/2 or the timed action plan.
<Subject 1> is Fang Zhiwei, the same fictional adult woman defined by <Picture 1> and <Picture 2>, appearing throughout this clip.
<Subject 2> is the crowded nightclub/bar atmosphere and moving camera language studied from the supplied source post by @joshesye (post 2118573484330594633). Source frames provide only shot order, gestures, camera movement, wardrobe/accessory cues and room atmosphere; the source performer's identity and appearance are excluded.
<Subject 3> is the visible outfit/accessory styling abstracted from source frames: a pale pink or cream textured baker-boy cap, a gray/taupe fitted short-sleeved top over a pale inner layer, light pink fitted front panel with black ribbon detail, dark sunglasses initially hanging at the upper chest, silver-tone layered necklaces, slim bracelets and an orange-red wristband without legible text. Fine fabric, closures, exact layering and unseen details are unknown; do not invent them. These cues must not alter Fang Zhiwei's face or body.
<Subject 4> is the ordered pose and camera progression observed in the source: forearm sweep and jaw/neck/hair touch; cap adjustment during a high-angle pullback; hand under chin; thumb-and-little-finger call-me gesture with a brief wink; a short dim transition; then dark sunglasses raised near the lips. This is a textual motion study, not a direct video input.
<Subject 5> is the nightclub environment: dim crowded interior with red/magenta practical lights and dark background. Preserve the colored room lighting but render skin naturally.
summary:
[reference generation] Create a 10.033-second, 4:3-framed photorealistic nightclub portrait video of Fang Zhiwei. <Picture 1> locks her face and base skin tone; <Picture 2> locks her body proportions; <Picture 3> guides the visible styling, club environment and lighting only. Transfer the source-studied gesture and camera order from <Subject 4>, visible styling cues from <Subject 3>, and crowded red-lit atmosphere from <Subject 2>/<Subject 5>. Do not reproduce the source performer's identity, face, eye color, body or anatomy. Keep the whole sequence and runtime. Brisk natural real-time gestures and decisive camera moves: complete each beat within its short window, with no slow motion, prolonged portrait hold or repeated hair strokes. The final two seconds must show sunglasses held near the lips. No dialogue or lyrics are specified.
retention_analysis:
<Picture 1> (Fang Zhiwei's identity, all shots): fully_preserved - Use the approved v6 portrait reference for facial identity, proportions and base skin tone.
<Picture 2> (Fang Zhiwei's body, all shots): fully_preserved - Use the approved v6 body board for her figure and proportions; do not inherit its pose or clothing.
<Picture 3> (environment and lighting, all shots): partially_preserved - Clothing/accessory and scene reference only; static QA accepted with limits. It never defines identity or body proportions.
<Subject 1> (all shots): fully_preserved - The same adult fictional Fang Zhiwei remains the subject throughout.
<Subject 2> (background and camera path): partially_preserved - Retain crowded club atmosphere and studied camera trajectory; no source footage is directly composited.
<Subject 3> (all shots): partially_preserved - Transfer only visible cap/top/inner-layer/pendant/wrist styling; keep modest opaque coverage and leave uncertain construction unresolved.
<Subject 4> (all shots): partially_preserved - Preserve the observed gesture and camera order, adapting motion to Fang Zhiwei while avoiding the source woman's identity and anatomy.
<Subject 5> (all shots): partially_preserved - Retain dim red/magenta practical lighting and crowd depth with natural subject integration.
detailed_description:
Photographic 4:3 nightclub footage. Preserve the fixed-v6 adult bone structure, eye size and spacing, nose, lips, base skin tone and long dark near-center-parted wavy hair. Fine natural skin variation, lifelike eyes/lips, individual strands, stable hand anatomy and coherent flash/ambient lighting. Keep local red practical light on the room and edges, without a global red/magenta skin wash. No doll eyes, porcelain smoothing, beauty-filter blur, age regression, extra limbs, captions, logos or readable background/wristband text.
Brisk real-time performance: each action happens once, leads directly into the next action, and is completed by the stated deadline. Four concise shot beats; spend less time touching hair and more time completing the camera and prop changes. Never slow or stretch a gesture.
[Shot 1, 0.000-1.600 seconds] Start with a bracelet-wearing forearm sweeping across the upper foreground. Lower it immediately in the first half second, revealing the fixed-v6 face in an oblique-to-frontal close-up. One quick jaw-to-hair brush finishes by1.4s; hand leaves the face. The camera is already pulling back at1.6s.
[Shot 2, 1.600-3.800 seconds] Complete a fast high-angle pullback to waist-up by2.2s. Fang Zhiwei touches the cap brim once with both hands, then releases it by3.2s. Immediately arc and push the camera back toward her face; finish the close portrait by3.8s. Do not repeat cap or hair adjustments.
[Shot 3, 3.800-7.300 seconds] In tight portrait, briefly place one hand beneath the chin and change to a clear thumb-and-little-finger call-me gesture by4.5s. One quick wink and a small smile by5.4s. The camera arcs gently while she releases the gesture at6.4s and reaches for the dark sunglasses hanging at her chest. Hold no gesture longer than one second. Begin the brief dim transition at7.3s.
[Shot 4, 7.300-10.033 seconds] A brief half-second dim transition reveals the same fixed-v6 face without morphing. By8.0s the sunglasses are visibly in her hand, lifted from the upper chest. Show the full upward lift and a clear hand-object contact: one temple held beside the lower lip throughout8.2-10.033s, not worn over the eyes. Keep lips, face and glasses separate. End on direct gaze with subtle natural expression. Preserve natural skin detail, the pale textured cap and localized red club lighting in every shot.
overall_soundscape:
No intelligible speech or lyrics are specified. For this native generation use restrained diffuse nightclub room tone, low crowd murmur and distant clinks, without foreground dialogue. The source audio is not an H3 input and has not been listened to; after picture review, the final conform will carry the original source AAC separately. Keep the native H3 audio archived, and do not claim lip or beat synchronization.
non_diegetic_music:
For the native output only, use a low-volume vocal-free electronic pulse, without recognizable melody or lyrics. This generated score is archived with the native output, not layered into the final conform; the final video retains the original unauditioned source soundtrack. Do not infer its lyrics or musical timing.
H3 配方与实际回执摘要
实际工作流为 MiniMax H3 Ref2VA(参考转视频),提交校验通过,3 张参考图;Comfy 工作流含 25 个节点。H3 输出目标为 4:3、约 1.5 MP、10.033 秒、24 fps;Euler sampler、simple scheduler、12 steps、CFG 1。工作流包含 SelfLift Progressive Sampler、视频/音频 VAE、H3 CLIP 与参考转视频模型,并叠加两层模型 LoRA;保留其余原始 H3 采样与解码链。实际提交回执为 complete,native 输出生成成功;最终 v2 成片由后续 conform 形成,技术解码检查通过。
制作顺序为首版生成后仅做一次 v2 节奏修订;总计两次 H3 generation attempts,修订预算已耗尽。v2主要收紧动作时间窗、减少重复摸头发/帽子的停顿,并要求末段提前展示墨镜。这是一次成对前后比较,不能据此作普遍因果结论。
验收边界与实际差异
- v1 抽样 QA:动作顺序部分出现但节奏延迟;电话手势偏晚,墨镜只在片尾附近出现。
- v2 抽样 QA:电话手势约 6.75 秒可见,墨镜在约 8.75–10.04 秒出现;比 v1 更早,但墨镜竖直遮到下唇,镜腿位置/方向未按提示落在唇边。相机高位/绕行仍为 partial,未充分复现。
- 两版约每 0.25 秒抽样检查,均未连续观片;音频未听审。身份与肤质是 partial / 未认证通过,prop contact 也是 partial。静态参考的有限接受不替代上述动态验收。
- v2 的技术解码通过只代表文件可解码,不代表动作、身份、肤质或道具接触通过;观众效果未知。
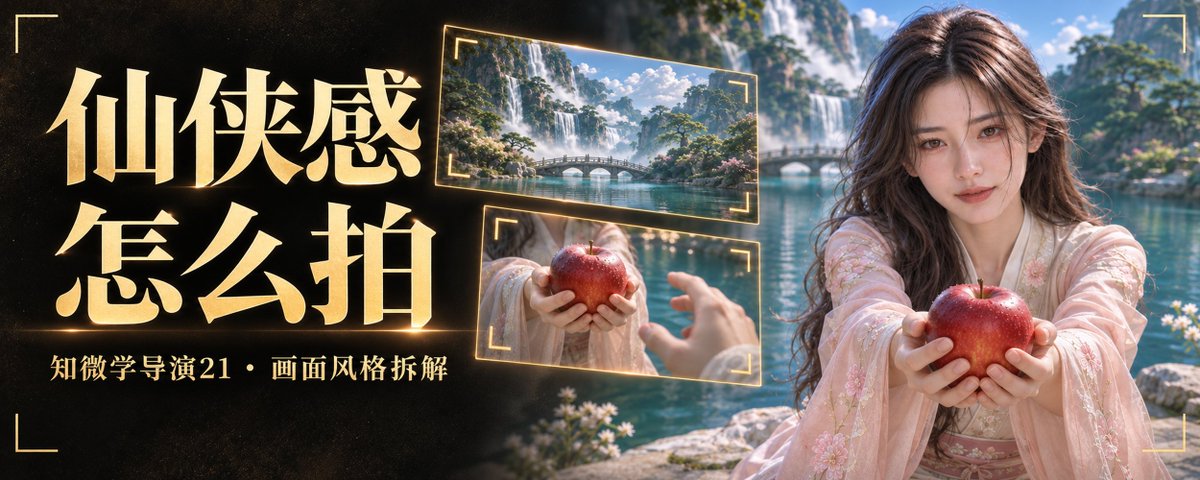
知微学导演21|来源与完整实际输入
研究来源:teapaw.org/AIVideoHub_/status/211…
AIVideoHub_为发布账号,原作创作者与实际工具链未确认。本文从画面反推可尝试的方法,不把我们的H3配方写成原作者流程。
本次只做池畔递果的单人风格迁移首样,非82秒全片复刻。请求6秒,实际6.583秒、1664×928、24fps、158帧;一次生成、保留原声。人物偏柔滑精修,真人感未通过;脸部只有局部相似,体型未认证,音轨未听审。
实际输入A:imagegen静态参考
参考图1=固定v6方知微身份/身材基准;参考图2=原片约72秒画面,只提供衣物、环境、机位和递果关系。没有沿用原片人物的脸和体型。以下保留实际提示词原文;本机定位信息留在本地,语义未改。
Use case: identity-preserve / photorealistic-natural.
Create one landscape 16:9 cinematic still to serve as a six-second AI video style recreation reference. Input image 1 is the sole identity and body reference for the fictional adult woman Fang Zhiwei, age 22. Match its clear left portrait face, facial structure, eye proportions, adult appearance, natural base skin color and long near-center-parted dark brown-black wavy hair. Match the same body proportions from its right full-body views; ignore the blurred faces in the layout. Her office suit is NOT the outfit for this shot.
Input image 2 is a source-film frame for the fantasy landscape, daylight, spatial depth, robe fabric and first-person object-offering action only. Do not copy any face, body, fox ears, identity or multiple women from image 2.
Scene: first-person seated eye-level view at the pale stone edge of a jade-blue garden pool. A single fully clothed Fang Zhiwei is centered slightly right, kneeling on a DRY stone terrace, not bathing, wearing an opaque blush-ivory flowing Chinese fantasy robe with the light pink long wide sleeves and fine embroidered fabric visible on the apple-offering woman in the source. Keep the garment closed, tasteful and opaque. Her lower robe and waist remain visible, with no erotic emphasis. She extends one glossy red apple toward the viewer with both hands, warmly attentive expression and direct lens eye contact. A single viewer's right hand in an ivory robe sleeve enters from the lower right, palm beginning to reach for the apple but not touching. Maintain correct hand anatomy, only two hands belonging to her and one POV hand.
Background: vast lush Chinese celestial garden, green rocky peaks with tall waterfalls, a small arched bridge slightly left of center, jade-blue reflective water, cumulus clouds in deep blue sky. Realistic skin and tactile textile near camera, fantastic monumental vista far away. The face and apple are primary focus; readable but gently softened distant scenery, not uniform sharpness. Natural noon sunlight, soft neutral-warm skin, luminous white fabric without clipping, dark green rocks and blue water for cool/warm separation, moderate saturation; no magenta/orange color wash. Retain tiny skin texture and individual flyaway hair, no porcelain CG face. Camera has a human seated viewpoint and mild wide perspective without warped face or fisheye. No text, subtitles, logo, watermark, borders, extra characters or animal ears. This is an adapted style study, not a traced copy of source pixels.
实际输入B:MiniMax H3 Ref2VA视频
Picture 1=这次新生成的单人岸边场景图;Picture 2=固定v6身份图。完整实际提示词如下。
subject_definitions:
<Picture 1> is the opening-frame and composition anchor for [Shot 1], showing one woman offering a red apple toward a seated first-person viewer at a fantastical pool garden. It defines the poolside setting, bridge, waterfall valley, cool blue-green palette, blush embroidered robe, apple, and the viewer's white sleeve.
<Picture 2> is the identity and body-proportion reference for Fang Zhiwei only. Use its clear left portrait for her face, adult appearance, base skin tone, and long dark near-center-parted wavy hair; use its full-body panels only for her proportions. Ignore its office clothes, background, labels, pose, and blurred turn-view faces.
<Subject 1> is Fang Zhiwei, a fictional adult woman whose identity and body proportions come only from <Picture 2>.
<Subject 2> is the fantastical waterside garden environment and first-person composition established by <Picture 1>.
<Subject 3> is the single glossy red apple offered in <Picture 1>, together with the viewer's single ivory-sleeved right hand.
summary:
[reference generation + keyframe completion] A six-second single-shot POV style study begins from <Picture 1>. <Subject 1>'s v6 identity from <Picture 2> is placed in <Subject 2> and offers <Subject 3> to the viewer; only the scene and framing guidance transfer from <Picture 1>.
retention_analysis:
<Picture 1> ([Shot 1] opening frame): partially_preserved - use its eye-level seated POV, one apple held forward, viewer's sleeve entering from lower right, pool, arched bridge, waterfall mountains, and blue-green garden palette; no source identity is retained.
<Picture 2> (identity and body reference for [Shot 1]): fully_preserved - preserve Fang Zhiwei's clear portrait identity, adult appearance, base skin tone, long dark wavy hair, and proportions; do not retain the office outfit or setting.
<Subject 1> (appears in [Shot 1]): fully_preserved - keep the same v6 face and body proportions, with natural expression and the specified long dark wavy hair.
<Subject 2> (appears in [Shot 1]): partially_preserved - carry over the poolside fantasy vista and first-person viewpoint from <Picture 1> while maintaining a coherent, newly generated layout.
<Subject 3> (appears in [Shot 1]): partially_preserved - retain one red apple and one ivory-sleeved viewer hand, with the actual receiving hand and contact developing through the shot.
detailed_description:
The video is a single continuous cinematic fantasy POV shot: a realistic adult woman's face, hair, embroidered fabric, and red apple sit in the foreground while a monumental Chinese garden vista recedes into the distance. Use natural cinematic realism, fine but restrained skin and hair detail, a neutral-warm complexion, luminous soft daylight, clear separation between warm blush fabric and cool blue water, deep green mountains, and softly bright cloud banks. Maintain the seated human eye level and gentle wide-lens spatial depth; keep the face undistorted, the apple sharp enough to read, and distant scenery slightly softer. Avoid a global pink cast, porcelain skin, hard beauty-filter finish, fantasy CGI gloss, fisheye distortion, or a drifting camera. The single shot remains on the same axis and place throughout, with only subtle natural camera breathing.
[Shot 1] Begin on the composition of <Picture 1>. <Subject 1>, Fang Zhiwei with the identity, age appearance, skin tone, dark wavy hair, and proportions of <Picture 2>, is seated on a dry pale-stone terrace beside the jade-blue pool, not bathing. She wears a fully opaque, closed blush-ivory Chinese fantasy robe with long wide sleeves and fine embroidery. The robe is fitted naturally to her v6 body proportions; its source and appearance do not come from the office outfit in <Picture 2>. She is the only person in frame, and no animal ears are present. She holds one glossy red apple with both hands at chest height and looks warmly into the camera. Behind her, <Subject 2> includes reflective blue pool water, one low arched bridge slightly left of center, green rocky peaks, multiple tall waterfalls, and cumulus clouds under a clean blue sky. Keep these landmarks spatially stable and give the vista depth through foreground, midground, and distant mountain layers.
From 00:00.000 to about 00:01.000, hold the opening pose and eye contact. From about 00:01.000 to 00:03.500, <Subject 1> slowly extends <Subject 3> toward the lens by roughly one forearm's length, keeping the apple centered and level with both hands. From the lower right foreground, the viewer's single right hand in an ivory robe sleeve reaches toward the fruit; its fingers remain anatomically clear and separate. From about 00:03.500 to 00:05.000, the viewer's hand touches and securely takes the apple; <Subject 1> visibly releases it only after contact, without the fruit duplicating, vanishing, or passing through either hand. From about 00:05.000 to 00:06.000, the viewer withdraws the apple slightly toward the lower right while she draws both hands back, watches the completed handoff, and gives one small confirming nod. Keep this contact and release in frame; do not cut away or stop before the handoff finishes. Her expression stays gentle and composed. No spoken dialogue, lip-sync, captions, subtitles, readable signs, logos, extra hands, duplicate fruit, pool splashes, or added characters.
overall_soundscape:
Quiet garden ambience with soft continuous water and waterfall wash, light fabric movement during the reach, and a subtle hand-to-fruit contact sound synchronized with the visible handoff. No voices.
non_diegetic_music:
A restrained, low-volume Chinese instrumental texture led by soft plucked strings and sustained airy tones, with no vocals and no dramatic swell.
复现检查路径:
1. 先分别检查身份参考与场景参考,别让服装/背景图覆盖人物脸和身体。
2. 先做静态构图,再写“持果→递近→接触→归属转移→收手”的单一动作;按实际输出检查终态,提示词时间不是实测切点。
3. 抽查首中尾、加密交接窗口,身份、手指、真实感、色彩、声音分项记录。这次递果归属可读,但没有解决真人感,也没有证明长片一致性。

简易实际制作提示词:固定v6头像和体型图锁定方知微;酒吧造型图只管帽子、衣服、配饰和局部红光。约10秒,前臂掠过镜头→揭脸、拂发→拉远扶帽→托腮、电话手势→暗转→举墨镜;自然实时动作,不加慢动作。实际相机以正面推拉为主,电话手势偏晚,墨镜竖起触到下唇;脸部近似和磨皮问题保留,未试听或认证卡点。来源:teapaw.org/joshesye/status/211857…

两秒手势舞跑了47.893秒,X4让发丝更清楚,运动中的手仍模糊。第18课放上原片、放大版和同步对照:身份仍部分通过,小动作保留,适用范围也写清了。#方知微的日常
第18课的来源与实际设置:
前篇X2实测:teapaw.org/superfang119/article/2…
原生成片段:teapaw.org/superfang119/status/21…
原动作/服装/场景参考:teapaw.org/mianyx11/status/210888…
原生接入:github.com/Comfy-Org/ComfyUI…
模型配对:huggingface.co/Comfy-Org/Rel…
本次输入是既有生成片第32至79帧:928×1664、24fps、48帧、两秒,裁窗解码画面与源对应帧逐像素一致。X4输出3712×6656,保持帧数和速度;原生上传持续停在0后,文章使用从X4成品等比转出的1044×1872展示版,未重新推理。它是慢速抬指、头侧停留、落手与轻摆,脚不在画面内,无切镜或闪光。
使用relayvsr_x4_int8_convrot主模型和配套relayvsr_flash_vae_x4_fp32,1步、CFG 1、Euler/simple、denoise 1、detail 1。同一低清视频接入RelayVSRConditioning与VSRDecode。本次没有新文本提示词或额外v6图片输入;v6脸部和身体参考只属于原片H3生成来源,没有新生成表演。
RTX PRO 6000 Blackwell 96GB上,11月6日23:06:43.655至23:07:31.548整图执行47.893秒,含加载、处理、编码,不含下载、裁窗、后续色彩/对照加工或上传。原生输出按sRGB传递函数实际转换至SDR BT.709,三个展示视频恢复同一源音轨窗口;未额外修脸、锐化、创意调色或插帧。
实际结果:纹理更分明,相对原片未见明显额外换人,固定v6匹配仍部分通过,摄影真实感未通过;所查小动作顺序和时点保留。48帧配对未见明显大块拖影或双脸,运动手部模糊仍在。未验完整编舞、快速舞蹈、脚步/节拍、切镜/闪光、量化闪烁、实时观感或音轨听感,也没有用同一输入对比X2。
原片播放器使用同尺寸、同帧数的H264展示编码;无损测试输入单独保留,逐像素核验不指网页转码副本。


Casting-Workflow整理写作上下文,故事生成仍要交给外部模型。我更想借用它的阶段交接:先把人物为什么行动、道具怎样接上写清,再去生成镜头。知微学导演19。 #方知微的日常

本篇研究来源:dama-cyber/Casting-Workflow
github.com/dama-cyber/Castin…
文章里的雨天拿伞故事与分镜交接模板是本次写的待拍练习,没有提交给视频模型。源码研究确认了阶段输出和截断限制;“保证原创”“检测不到”没有作为实测结论采用。

🔥 MiniMax H3 又有值得尝试的社区微调模型了!这次重点不是单纯提高画质,而是强化动作表现、镜头控制和人物真实感。
MiniMax H3 Singularity V2:WarmBloodAban 发布的 H3 社区融合微调模型,专门针对视频生成效果进行优化。
重点看 4 个能力:
⚔️ 1. 动作场景强化
针对剑术、武术、近身格斗等复杂动作优化,增强动作流畅度、力量感和物理冲击表现,减少高速动作中的模糊感。
🎭 2. 人物细节改善
优化中远景人脸表现,减少面部结构崩坏,同时降低皮肤过度油亮的问题,让人物质感更加自然。
🎥 3. 镜头与提示词控制
增强对运镜指令的响应,支持推拉、摇移、跟拍等镜头描述。V2 进一步提升提示词遵循能力。
🎨 4. 多种视觉风格
重点强化:
Photorealistic:真实摄影
East Asian Realism:东方写实
3D CG:三维动画
Cinematic CG:电影级 CG
另外,V2 修复了音频参考条件问题,可以利用音频参考辅助调整人物色调。
适合谁用?
使用 ComfyUI + MiniMax H3 制作武侠打斗、动作短片、人物 MV、东方写实和电影级 AI 视频的创作者。
🔗 Hugging Face:
huggingface.co/WarmBloodAban…
⚠️ 两个上手提醒:
V2 提供 INT8、BF16 等版本。V2 INT8 约 34GB,V2 Pruned INT8 约 21GB,下载前注意磁盘空间和模型配置。
文件命名为 Ref2VA,建议优先在 H3 参考视频工作流中测试,不要直接当作 FL2VA 的通用替代模型。
#MiniMaxH3 #Singularity #ComfyUI #AI视频 #开源模型

简易实际制作提示词:固定v6头像和体型参考只管方知微的脸和身材;暮色水边,红色翻领短裙、黑色V形内片、右腕黑手环。提示词计划依次腹前轻摆、手绕头后、低位展臂、胸前交叉与触领、张臂、手框与指向,最后抬掌侧摆;一个稳定机位,不加慢动作。成片使用原片音轨,未试听或确认卡点;肤质自然度未通过,动作只做过抽样核对,非完整复刻。来源:teapaw.org/mianyx11/status/210818…
《新生》这3.5秒放大两倍,发丝更清楚,原有闪光还在。把原片、RelayVSR X2和同帧对照放在第17课,分别验身份、动作与时序;我会留清晰度,不把它当成修好了镜头。#方知微的日常
第17课的来源与实际设置:
起点原帖:teapaw.org/superfang119/status/21…
官方接入:github.com/Comfy-Org/ComfyUI…
模型配对:huggingface.co/Comfy-Org/Rel…
作者代码:github.com/kopperx/RelayVSR
论文:arxiv.org/abs/2609.37850
输入是《新生》第34段已用镜头的前84帧,24fps、3.5秒、1664×936,保留第56帧实际切宽。输出3328×1872、84帧。X2 LightX2V主模型配X2 Flash VAE,1步、CFG 1、Euler/simple、denoise 1、detail 1。
本次没有另写文本提示词,也没有新生成H3表演。RelayVSRConditioning使用内置条件;VSR只接收原视频。固定v6脸部与身体参考属于原片的H3生成记录,没有作为额外图片传入这次超分。
复现时先取确定的帧区间,保留帧率与尺寸,把同一组低清帧接到conditioning与VSR decode;用配套模型/VAE跑完,再核对帧数、实际切点与同帧局部。声音单独按相同时间窗补回。本文中的原片与放大版没有额外修脸、锐化或创意调色;放大版按原生sRGB传递函数标签实际转换至SDR BT.709。
实际结果:纹理更分明;相对原片未见明显额外换人,固定v6匹配仍为部分通过;小动作顺序与切点保留。逐帧检查未见明显跨切点拖影,但第74帧原有亮变仍在,未测得“减少闪烁”的量化结论。不是全片或复杂动作验收。

🎬 AI 视频放大到 2K/4K,最怕的不是不够清晰,而是每一帧都清晰了,连续播放却开始闪烁、变脸、纹理漂移。
Comfy-Org 现在把 RelayVSR 的模型权重整理到了 Hugging Face,并且 ComfyUI 核心已经合入原生支持。
它不是普通的逐帧图片放大器,而是一套专门针对视频设计的时序超分辨率方案。
重点看 4 个能力:
🔍 1. 原生支持 2 倍和 4 倍放大
提供两套模型:
X2:适合将 768P 视频提升到约 1536P。
X4:适合更大倍率的超分辨率处理。
🧠 2. 大模型 + 小模型协同
每隔 15 帧,由 Wan 2.2 5B 生成关键帧参考 Latent,再由轻量 Flash 解码器结合原始低清画面补全其他帧。
既利用大模型恢复细节,又避免每一帧都运行完整的大模型。
🎞️ 3. 专门处理视频闪烁
利用前后关键帧和时序上下文,让相邻画面的纹理、细节更加连贯。
特别适合处理 AI 视频生成后出现的轻微闪烁和细节不稳定。
⚙️ 4. ComfyUI 原生接入
已经合入 ComfyUI 核心,新增 RelayVSRConditioning 和 VSRDecode 节点。
不需要文本编码器,直接使用低清视频作为条件输入,完成视频超分辨率。
适合谁用?
使用 MiniMax H3、Wan 等模型制作 AI 视频,希望进一步提升分辨率、细节和画面稳定性的 ComfyUI 用户。
🔗 Hugging Face:
huggingface.co/Comfy-Org/Rel…
⚠️ 两个上手提醒:
这个仓库提供的是模型权重,不是独立的 ComfyUI 插件。核心支持已合入,但需要包含相关提交的 ComfyUI 版本及配套依赖。
X2 和 X4 的 Diffusion Model 与 VAE 必须成对使用。每套主模型约 5.16GB,配套 VAE 约 128MB,下载时别混用。
#RelayVSR #ComfyUI #MiniMaxH3 #AI视频 #视频超分辨率
