

Principal @Atlassian | Helping engineers reach Staff/Principal | 1:1 Mentorship & Mock Interviews | 90+ System design fundamentals - https://xitter.cf/t.co/Ots2nRhO5f
Hyderabad
Joined December 2025
- Tweets2.4K
- Following125
- Followers25.5K
- Likes1.9K




Pinned Tweet
A month ago, I told everyone:
"I've been a backend Engineer for 12+ years. Today, I'm a Principal Engineer at Atlassian.
I've designed systems that handle millions of requests. Sat on both sides of system design interviews.
Reviewed more architecture docs than I can count.
Starting today, I'm breaking down the fundamentals of scaling for the next 25 days.
If you're learning system design bookmark this thread, you're going to get a lot of learning from this."
FYI, the series has concluded. Here are all the concepts, please bookmark, share, learn and the most important build from the learnings you get.
Also, if you have any ideas on what you'd like to see from me, please let me know, any other series or concepts to be broken down.
A junior ships a working service with AI.
Good.
Now ask:
What happens if it crashes after writing to the database but before acknowledging the message?
Building faster is progress.
Explaining failure is engineering.
The stakes have never been higher to go back and be a student. That's why you should study the fundamentals that will still matter after the next model launch.
For backend engineers, that's distributed systems.
I wrote it all down as a free 23-part series, in the order I'd learn it:
1. Load Balancing: why "balanced" traffic can still melt one server
2. CDN: how most of your traffic gets served before it reaches your origin
3. Caching: the five layers, and Redis is only one of them
4. Cache Invalidation: knowing when to throw data away
5. Rate Limiting: the day our own batch job became our worst traffic spike
6. API Gateway: the front door and the six jobs it does
7. CAP Theorem: the choice you make the moment the network splits
8. Sharding: the hardest scaling decision to reverse
9. Replication: why a user can see their own stale data
10. Partitioning: the cheap step most teams skip before sharding
11. Queues: turning traffic spikes into a steady stream
12. Microservices: why Prime Video saved 90% by moving off them
13. Microservices vs Monoliths: how Shopify and Stack Overflow scale a monolith
14. Fault Tolerance: timeouts, circuit breakers, bulkheads and retries
15. Database Scaling: the five steps, in the right order
16. Service Discovery: finding service X when every instance keeps moving
17. Consistency Models: the five models that separate a bank from a fraud incident
18. Eventual Consistency: patterns that make stale reads survivable
19. Distributed Transactions: two-phase commit vs Sagas
20. Leader Election: Raft, split-brain and fencing
21. Horizontal vs Vertical Scaling: bigger machine or more machines
22. Back of the Envelope Estimation: the five-minute maths habit
23. Idempotency & Data Locality: what makes retries safe
All 23 parts are here: puneetpatwari.in/blogs/serie…

Btw, if you're preparing for system design interviews, I've put together an in-depth fundamentals guide.
You can check it out here: puneetpatwari.in
Major green flags in a Senior engineer:
1/ asks "what problem are we solving?" before "which tool?"
2/ rolls back first, debugs second
3/ writes the runbook nobody asked for
4/ says "I don't know yet" without losing the room
5/ deletes more code than they add some weeks
6/ explains trade-offs without making anyone feel stupid
7/ reviews PRs like they'll be on-call for them
8/ makes the juniors around them better
9/ estimates before building
10/ owns the outage, shares the credit
The most important quote from this blog is "the goal isn't a 10x builder. The goal is a 10x team".
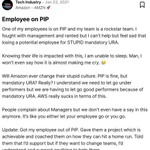
I love the contrasting take and support it as well.
Thanks @sherifmansour for sharing this..

A few months ago, I published my thoughts on what we've learnt form hiring juniors in the world of AI: sherifmansour.medium.com/on-…
Last week, Anthropic published a piece on “How employment is changing at Anthropic”: anthropic.com/research/emplo…
Firstly, thank you again to the folks at Anthropic for continuing to share what they’re learning with the rest of the world. I found their post incredibly thought provoking and made me challenge some of my assumptions.
I felt like one question folks could have from Anthropic’s findings is what does a junior add once the team is already AI native?
My answer is that the learning curve keeps resetting. Each new wave of tools and techniques can ask experienced people to unlearn something; newcomers get to start there.
In my time spent working in tech (old man here 🤣), unlearning has been one of the hardest things I’ve seen a workforce have to do - especially when the old ways made people successful. As an example, an experienced developer might ask how AI fits their workflow. Someone learning today might ask what workflow makes sense now that AI can write code.
I’m not suggesting that means younger people always adapt better (although, I think that could be generally true). But their contribution doesn’t disappear once everyone has adopted today’s tools. Tomorrow’s approaches can create that opportunity again - I think of it more as a never-ending cycle.
I think the challenge that will always exist is that newcomers help the team discover different ways of working, while experienced colleagues help them develop judgment and independence. That takes deliberate investment.
So I’d still resist a blanket decision to stop hiring juniors. Instead, look at what the situation you’re in. Today, the vast majority of the world is unlearning how they used to work, the argument that once we’re all AI native you won’t need juniors doesn’t check for me - because tomorrow’s approaches for what “AI native” means will continually reset that assumption.

The dangerous AI answer is not the obviously wrong one.
It is the correct-looking answer that quietly assumes:
- retries are safe
- clocks agree
- messages arrive once
- the network is reliable
Senior engineers are paid to notice hidden assumptions.
The 8 stages of every vibe coder's backend:
1. "Supabase + Vercel. Backend is solved."
2. 50 users. Everything is fast.
3. Launches. 3,000 users in an hour.
4. Database connections maxed out. Site down.
5. Asks AI to fix it. AI adds caching. Users start seeing each other's carts.
6. Googles "what is a connection pool."
7. Reads about indexes at 3 AM.
8. "Backend engineers were right all along."
Count unique visitors on a page that gets 100 crore visits a day.
You have 12 KB of memory.
You can be off by 1%.
How?
HyperLogLog.
Hash every visitor ID. Look at how many leading zeros the hash has. Rare long runs of zeros mean you've seen a lot of unique IDs. Keep the longest run per bucket across 16,384 buckets, then average.
Redis does exactly this with PFADD and PFCOUNT. 12 KB, about 0.8% error, whether you have a thousand visitors or a hundred crore.
Exact counting needs memory that grows with users. Good-enough counting doesn't.
As a Backend Engineer, you must build these projects.
1.) URL shortener that survives 10x traffic
Build: Postgres + Redis cache + rate limiting, load tested to 5,000 requests a second.
Why: caching, ID generation and capacity math in one project.
2.) Distributed rate limiter
Build: token bucket and sliding window in Redis, shared by 3 app servers.
Why: it shows up in almost every Senior loop.
3.) Job queue with retries
Build: workers with backoff, a dead-letter queue and idempotent jobs.
Why: you learn that "at least once" means "sometimes twice."
4.) Chat server
Build: WebSockets, presence, delivery receipts, reconnects.
Why: real-time is where most candidates start guessing.
5.) Payments ledger
Build: double-entry ledger with idempotency keys and nightly reconciliation.
Why: money forces you to care about correctness.
6.) Zero-downtime migration
Build: rename a column on a 10M-row table while a load test runs.
Why: the Senior skill nobody practises.
Put the load test numbers in your README. That's your system design round, already rehearsed.
AI can produce a pull request before you finish reading the ticket.
That makes one skill more valuable, not less:
Reading code you did not write and deciding whether it is safe.
The bottleneck is moving from generation to verification.
I did 487 system design mentoring sessions this year.
The same 5 reasons people fail system design rounds keep coming up:
1. They start drawing before asking a single question.
2. They name tools instead of trade-offs. "Kafka" is a noun, not a reason.
3. They skip the math. 1,000 users and 10 crore users are different systems.
4. They design the happy path and go quiet when I kill a server.
5. They memorised Netflix and froze on a parking lot.
Every one of these is fixable in 4–6 weeks of the right practice.
If you want to practise exactly these, I've written up 93 of the questions that come up, with full answers: puneetpatwari.in
And if you'd rather I grill you live, mock slots are on my Topmate.
Netflix staff system design round:
Interviewer: "One of your 200 instances has a bad config. It returns a 500 error in 2ms for every request.
Your load balancer uses least-connections.
Within a minute, 40% of all traffic is going to the broken instance.
Why?"
During my system design round at Amazon, the interviewer took down my cache.
During my system design round at Walmart, the interviewer killed my primary database.
During my system design round at Atlassian, the interviewer made one downstream service take 10 seconds to respond.
In every round, someone broke my design on purpose.
Because any design works when nothing fails.
Interviewers want to see what yours does when something does.
After sitting through 100s of interviews in the last 13 years, one thing is clear to me:
If you're starting system design prep, focus hard on Failure & Reliability Fundamentals.
Here's a list to help you get started:
[1] Timeouts & Deadlines
- Connection vs request timeouts
- Deadlines that travel across service calls
- What happens when a call has no timeout at all
[2] Retries
- Exponential backoff with jitter
- Retry budgets
- Retry storms and how they stretch outages
[3] Idempotency
- Idempotency keys for write APIs
- At-least-once delivery and duplicate handling
- Safe vs unsafe retries
[4] Isolation
- Circuit breakers
- Bulkheads and separate thread pools
- Blast radius per tenant, region and feature
[5] Overload Protection
- Rate limiting
- Backpressure
- Load shedding and priority queues
[6] Replication & Failover
- Leader election and split brain
- Sync vs async replication
- Failover vs failback
[7] Graceful Degradation
- Serving stale data on purpose
- Fallbacks and feature switches
- Read-only mode
[8] Data Safety
- Write-ahead logs
- Backups and point-in-time recovery
- Restores you've actually tested
[9] Observability
- p50 vs p99 latency
- SLIs, SLOs and error budgets
- Alerts that map to a runbook step
[10] Recovery & Operations
- Rollbacks and feature flags
- Zero-downtime migrations
- Postmortems that change the system
Btw, if you’re preparing for Senior to Principal-level system design interviews, I’ve put together 90+ fundamentals like these into a guide.
You can check it out here: puneetpatwari.in
50 system design concepts every backend engineer should know:
1/ Latency vs throughput
2/ Load balancing
3/ Horizontal vs vertical scaling
4/ CDN
5/ Caching
6/ Cache invalidation
7/ Cache stampede
8/ Hot keys
9/ Indexes
10/ Query plans
11/ Transactions
12/ Isolation levels
13/ Replication
14/ Read replicas
15/ Replication lag
16/ Sharding
17/ Partition keys
18/ Consistent hashing
19/ CAP theorem
20/ PACELC
21/ Eventual consistency
22/ Read-your-writes
23/ Quorums
24/ Leader election
25/ Raft
26/ Clock skew
27/ Message queues
28/ Kafka partitions
29/ Consumer groups
30/ At-least-once delivery
31/ Idempotency
32/ Outbox pattern
33/ Sagas
34/ Change data capture
35/ Rate limiting
36/ Backpressure
37/ Timeouts
38/ Retries with jitter
39/ Circuit breakers
40/ Bulkheads
41/ Graceful degradation
42/ Health checks
43/ Observability
44/ p99 latency
45/ SLOs
46/ Blue-green deploys
47/ Feature flags
48/ Zero-downtime migrations
49/ Multi-region
50/ Back-of-the-envelope estimation
Know 35 well and you can hold your own in any Senior round.
I've written full answers to the 93 questions these concepts turn into in Senior+ rounds.
puneetpatwari.in