

https://xitter.cf/t.co/3jNN3bYpO5
Joined May 2025
- Tweets29
- Following4
- Followers829
- Likes30




terminalbench retweeted

With hundreds of contributors and thousands of participants on Discord and GitHub, the @terminalbench team ships frequent updates in the open so everyone can learn alongside them. And with @harborframework, they've built the infrastructure for anyone to benchmark the use cases they care about.
Great to host the community at Laude Lab last week and hear what's coming next!
@alexgshaw @ryan_marten @StevenDillmann @Mike_A_Merrill @andykonwinski


terminalbench retweeted

Before their first release, the @terminalbench team called off a task-writing meetup, figuring there was no way to get more than ten people in a room to talk about the project. Tonight we squeezed ~150 into Laude Lab!
The team covered the state of the bench and @harborframework, the process behind Terminal-Bench-Science, and how to keep pace as models get better, faster: continuous benchmarks, real-world evals, and long-horizon multi-agent challenges.
@alexgshaw @ryan_marten @StevenDillmann @Mike_A_Merrill @andykonwinski


terminalbench retweeted

Terminal-Bench meetup tonight *with* swag. Register if you haven’t already! Benchmarks, RL environments, new features, and state of the union
luma.com/tbench

terminalbench retweeted

fast track to get model labs to care about the capabilities you care about:
contribute a task to Terminal-Bench
if you have built a benchmark around a specific use case, DM me and we can collaborate on a TB task for the next release

We're hosting a meetup!
Come meet the community behind the benchmark, celebrate recent releases, and join our discussions about the future of agent evaluation.
luma.com/tbench


terminalbench retweeted

Terminal-Bench-Science 0.1 is the #1 featured benchmark on @AnthropicAI’s new Claude Fable release 🚀
terminal-bench-science.ai

Across our benchmarks, the model sets a new standard.
It scores 52.6% on Terminal-Bench-Science 0.1, more than double Fable 5. On Terminal-Bench 4.0, it scores 55.8% against 42.0% for Fable 5.

ALT Benchmark table comparing Claude Fable 5.1 with Fable 5, Opus 5, and GPT-5.6 Sol across seven evaluations. Fable 5.1 leads on every row, including 52.6% on Terminal-Bench-Science 0.1 and 55.8% on Terminal-Bench 4.0.
terminalbench retweeted

Across our benchmarks, the model sets a new standard.
It scores 52.6% on Terminal-Bench-Science 0.1, more than double Fable 5. On Terminal-Bench 4.0, it scores 55.8% against 42.0% for Fable 5.
ALT Benchmark table comparing Claude Fable 5.1 with Fable 5, Opus 5, and GPT-5.6 Sol across seven evaluations. Fable 5.1 leads on every row, including 52.6% on Terminal-Bench-Science 0.1 and 55.8% on Terminal-Bench 4.0.
terminalbench retweeted
New SOTA on @terminalbench!


Announcing Terminal-Bench-Science!

We're releasing Terminal-Bench-Science: a benchmark for evaluating AI agents on research workflows across scientific domains.
An ongoing Stanford-led community effort, built by the team behind Terminal-Bench together with scientific domain experts at research institutions worldwide. v0.1 has 70 tasks. Claude Opus 5 solves only ~30%.
1/n 👇

terminalbench retweeted
Congrats to Z.ai for the strong performance on Terminal-Bench 3.0!
One of the biggest pieces of feedback we have gotten for TB3 is to increase the timeouts. We calibrated timeouts against frontier models during development, but inference speed can still be a confounder on some of the tasks.
Terminal-Bench numbers on the GLM-5.3 model card are reported with increased timeouts (likely for this reason).
Look out for Terminal-Bench 4.0 releasing soon with increased timeouts, other task improvements, and a handful of new tasks.


Introducing GLM-5.3: Built to Code. Ready for Cyber Defense.
- Top-tier coding and agentic capabilities, achieved through post-training on the 743B base model
- A major leap in cybersecurity, setting a new standard among open models
Tech Blog: z.ai/blog/glm-5.3




terminalbench retweeted

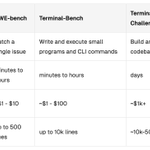
Can agents build complete projects that deliver real value? We’re launching Terminal Bench Challenges: 3 unsolved tasks which could make a real impact on the open source community if solved.
These tasks provide a testing ground for optimizations both on the model and harness level on our continuous leaderboard for each task.

Introducing Terminal-Bench Challenges!
A new capability has emerged at the frontier: agents completing large-scale projects autonomously. To test this capability, we felt another flavor of benchmark was needed.
Terminal-Bench Challenges are long-horizon, token-intensive, single-task benchmarks. Today we are releasing our first 3 challenges.

Check out the full release blog for more details!
tbench.ai/news/terminal-benc…

Terminal-Bench Challenges is inspired by previous projects exploring long-running agents including Carlini's C compiler and Cursor's browser.
Join the effort! If you have ideas for further challenges, come hang out in the tb-challenges discord channel
discord.com/invite/2Pe5uWGcV…