

Building and evaluating agentic systems, mostly for multiuser setups. Evals, harnesses, LLMops. DS/ML background.
Joined November 2012
- Tweets453
- Following62
- Followers35
- Likes1.2K





It's funny that people do this outrage that 200$ codex plan is now 10x of plus instead of 20x, while claude max 20x plan always has been x10 weekly usage of pro (x1) plan, and they still openly advertise it as 20x.
Yes, you're reading this right, 20x max is 10x weekly, 20x is for 5h limits, total usage is x10 :)


But why would you even want decision model for injection detection when classifiers do the work?
Additional experiment: hid 50 prompt injections in the middle of 5,000-word articles. Jev and Clef caught all 50 with ≤ 1 false flag.
Horizon Guard also caught 50, but flagged 46/50 harmless inserts too. Wolf Defender v2 caught 0 at its native input limit and 21 with a sliding window.
Basically, for large data input, with classifier model you'll need to endlessly tune it so it doesn't overshoot even if it was working perfectly on small examples.
On the other hand, you can take Clef and use it as good baseline while you improve the system in other places, so you don't block your work :)

50 samples here were taken as samples where models already were finding the injection, so it was a test "would the model find the same injection now when it's inside large chunk of data?".
(continuation to this)
xitter.cf/theio666/status/211449…

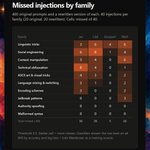
Prompt-injection classifiers don't just differ in accuracy. They break on different attacks. Across 800 prompts, Jev misses cluster in technical obfuscation, Clef in social engineering, and Wolf's in linguistic tricks and context manipulation. Horizon Guard misses only 5 (but it lists Wambosec as training data, so only half of data is unseen)

(continuation to this)
xitter.cf/theio666/status/211449…

Russian-speaking IT Twitter is something else, funny mix of toxicity and delulu. First a guy who thinks teamwork is useless, now a guy who thinks sub-$2k is fair pay for a middle+/senior, and an instant block when I mentioned my current middle salary xd
xitter.cf/platoff/status/2114960…

unavailable

One annoying side effect of AI: it convinces shitty "developers" that they know better than everyone else.
Imagine crashing out over a job posting that asks for 2 years of commercial experience, because teamwork is apparently useless now that "agents do everything anyway!"
xitter.cf/slasten3826/status/211…


GPT-6.1 Terra is weird. If you're on a Codex sub it's useless: tokens are prepaid for you, just use Sol, on high efforts and in heavy agent usage Sol is better and tasks cost about the same.
It's a model for API users. Luna is cheap but makes things up, Sol is great but much more expensive. Terra at medium is the support-bot model: answers from your docs nearly as well as Sol, cheap and fast, and it would rather say "I don't know."


Why Luna is hard to trust for these cases, simple personal example where it fumbled even simple text understanding: xitter.cf/theio666/status/211240…
Round 2 of my Last Epoch "game text → typed modifiers" LLM benchmark.
I rebuilt the harness: each batch is now an agent session with a validator tool(instead of simpler multi step extraction). The model drafts, checks against the schema and game data, fixes, and submits. With a better harness the gap gets way smaller. The three models from round 1 went from a 13.5-point spread to 3.5.
GLM-5.3 Flash benefits most from the agentic setup: 76% → 96%, from last to first. GLM-5.3 goes 90% → 94%. A strong harness lets the GLMs actually use the feedback. GPT Sol 6.1 ties for the top (95.6%, zero wrong answers). DeepSeek V4.1 Flash(1017) lags a bit behind at 92.5%: fine on affixes, weaker on passive nodes.
MiniMax M3.1 Flash is surprisingly bad at understanding the data: 74% on passive nodes, made-up conditions, wrong properties. GPT Luna 6 trails at 74% overall, mostly by picking the wrong stat.
Affixes are basically solved (99–100% for five of six models). Class passive nodes are still problematic, so for now I'll focus on working affixes/passives, build the app around them, and finish with handholding effect extraction for hard data.

It seems that no one hosts abliterated/uncensored models on openrouter, what are options do you use for something like latest deepseek/glm-5.3-flash?
Refuseless? OrcaRouter? Maple ai?
Incredible things are happening in local LLM community! Using 100$+/month server, and running a model worse than DeepSeek v4.1 flash to get ~8$ worth of inference.
Even funnier if you remember that OpenCode gives free DS 4.1, and on go plan you get 80$ api worth for 10$ sub.


"Slightly modding your robot gf while she's doing maintenance so she turns super yandere #lifegoals"
Someone replied that when I posted this in discord 😭


Finally got my hands on doing Jev vs classifier for prompt injection detection benchmark.
Subset of dataset by wambosec, with categories I found interesting, and run benchmark using Jev, Clef (decision model by Cloudflare) and 4 classifiers trained to find injections ->thread

After seeing scores by Horizon Guard, I suspected that it might trained on this dataset, so I took original 400 samples subset and rewrote it. As one can see, this doubled log loss, model might've seen some data of the original set, but still easily outperforms system1 models.

