
Research Scientist @GoogleDeepMind Zürich | PhD Student at @MPI_IS + @uni_tue.
Zürich, Switzerland
Joined October 2017
- Tweets100
- Following304
- Followers448
- Likes320



Pinned Tweet
Are we experiencing a 'GPT moment' in vision?
Super excited to demonstrate the generality with which current video models can solve tasks from simple perception to visual reasoning!
🌐 video-zero-shot.github.io


Could video models be the path to general visual intelligence?
In our new paper, we show that Veo3 has emergent zero-shot capabilities, solving complex tasks across the vision stack.
Project page: video-zero-shot.github.io/
Paper: arxiv.org/abs/2509.20328
🧵👇🏻

Robert Geirhos and I are #hiring student researchers at @GoogleDeepMind for 2027. Express you interest here: docs.google.com/forms/d/e/1F…
- full-time for 6 months
- on-site in Zurich
- co-advised by Robert Geirhos and me
- continuing our work on video models for visual intelligence

Thaddäus Wiedemer retweeted

(1/7) Astra is beating humans on spatial reasoning tasks 🤯
We evaluated Astra on MentisOculi, our ICML benchmark for visual reasoning from earlier this year.
It doesn’t just outperform every model we previously tested — on our evaluation, it also exceeds the human baseline.

Thaddäus Wiedemer retweeted

By popular request: the LittleCurriculum filtering pipeline and synthetic K–5 chat data used in LittleLearner training are now public! Excited to see how people use and extend them :)
💻 Filtering pipeline: github.com/littlelearner-ll/…
🤗 K–5 chat data: huggingface.co/datasets/litt…


What happens when an LLM never sees material beyond fifth grade?
We trained a 5B LittleLearner model from scratch on LittleCurriculum, a corpus restricted to K–5 material, to make this question testable.🧵
💬 Chat with LittleLearner yourself: littlelearner-ll.github.io

Thaddäus Wiedemer retweeted

[1/7] 🚨 We're releasing LAION-BVD: a 10-million-hour open video dataset for multimodal pre-training.
- 1.3B video URLs from CommonCrawl
- 80M downloaded videos
- 10M video hours
- 55M captioned clips
- 300M frame-caption pairs
🌐: projects.laion.ai/bvd/
🧵👇

Thaddäus Wiedemer retweeted
How do LLMs actually learn new facts? It's impossible to tell when pretraining data is a black box. Meet LittleLearner: a 5B LLM trained strictly on a U.S. elementary school curriculum (everything up to Grade 5 / age 12 👶) 🧵👇

It's usually hard to study knowledge & skill acquisition on LLMs, given that they've been trained on most of the Internet, and the training data is often opaque.
LittleLearner and LittleCurriculum fix that, check the details below!
What happens when an LLM never sees material beyond fifth grade?
We trained a 5B LittleLearner model from scratch on LittleCurriculum, a corpus restricted to K–5 material, to make this question testable.🧵
💬 Chat with LittleLearner yourself: littlelearner-ll.github.io
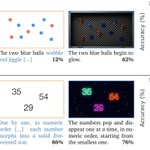
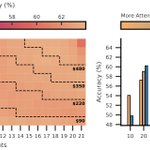
When an LLM is underperforming, we tweak the prompt. Why not do the same for video models solving visual reasoning tasks?
Visual prompt engineering changes the start frame appearance but not the task, improving performance.
📄 arxiv.org/pdf/2607.25537
🌐 visual-prompt-engineering.gi…
An important different read of these results is that many visual reasoning benchmarks (which typically are abstract sketches) systematically underestimate video model capabilities.
Work with Robert Geirhos, @_EffieLi_, @NehaKalibhat, @ziwphd, Mani Malek, Oyvind Tafjord, @kswersk, @_beenkim, and @priyankjaini.
Many fun videos on our project page visual-prompt-engineering.gi…
Looking forward to chatting with people tomorrow about video models as vision foundation models!
Spieler alert: I'll also touch on our latest work 🤫

Can a video model segment objects, detect edges, understand physics, simulate tool use, and solve mazes — zero-shot, with no task-specific training? Veo 3 can.
Tomorrow, first author @thwiedemer presents "Video Models Are Zero-Shot Learners and Reasoners" at our journal club.
Special daytime session for 🇪🇺 Europe & 🇨🇳 China:
🗓 Thu Jul 30 · 10:00 CEST · 16:00 Beijing · 1:00 AM PT
🎟 Register (Zoom link on confirmation): lu.ma/video-c0vz

Thaddäus Wiedemer retweeted

Can video generation models do for vision what LLMs did for language?
Introducing GenCeption from @GoogleDeepMind: one feed-forward video model for various vision tasks — SOTA, data-efficient, and emerging behaviors (ECCV 2026)
🌐 genception.github.io
(1/8)
How useful are self-generated 'mental images' (visual aids) in MLLM/UMM reasoning?
Turns out: currently not very. Visualizations have small errors that compound in multi-step problems, and models often ignore correct visual aids in their decision making.

Can AI reason by “imagining” — not just by seeing or reading?
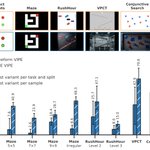
We introduce Mentis Oculi, a benchmark for machine mental imagery: multi-step visual puzzles that require maintaining and updating visual states over time.
📄 arxiv.org/abs/2602.02465
🌐 jana-z.github.io/mentis-ocul…
🧵⬇️
This work was a great collaboration; special shout-out to @Jana46052173 for leading this project and submitting the first paper of her PhD!