Divyanshu (@trydiv) header
Divyanshu (@trydiv) profile picture

working on @positionappxyz (ios)

position
Joined September 2021
Photo by Divyanshu (@trydiv)Photo by Divyanshu (@trydiv)Photo by Divyanshu (@trydiv)Photo by Divyanshu (@trydiv)Photo by Divyanshu (@trydiv)Photo by Divyanshu (@trydiv)Photo by Divyanshu (@trydiv)Photo by Divyanshu (@trydiv)Photo by Divyanshu (@trydiv)Photo by Divyanshu (@trydiv)
GTA VI is out!!! every big streamer is live for 12–15 hours one moment in there gets millions of views, whoever posts it first wins so i built HEISTCLIP paste a yt/twitch/kick link → it watches live, catches the moment, captions it, frames it vertical, drops it in your library ~50 seconds from moment to ready-to-post heistclip.com
1
1
10
283
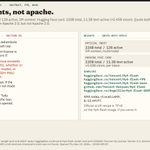
hy4 flash is now open-weight — instruct, fp8, and a base checkpoint. official tweet: 224B / 12B active. hf card: 220B / 11.3B text-active (+0.43B vision). tencent hy license 1.0, not apache. separate license above $50m revenue or 100m mau for maas. huggingface.co/tencent/Hy4-f… plus FP8, base, and official GGUFs (AngelSlim/Hy4-flash-GGUF). AMA tonight, r/LocalLLaMA, 8–10 AM PT. you can download it. if you serve it as an api at real scale, read section 10 first.
1
32
noice
GTA VI is out!!! every big streamer is live for 12–15 hours one moment in there gets millions of views, whoever posts it first wins so i built HEISTCLIP paste a yt/twitch/kick link → it watches live, catches the moment, captions it, frames it vertical, drops it in your library ~50 seconds from moment to ready-to-post heistclip.com
1
109
Google continues to accelerate its release cadence with Gemini 4 Neon, delivering a small Intelligence gain over Gemini 4 Carbon at a ~17% lower Cost per Task @GoogleDeepMind has released Gemini 4 Neon, its fourth model in just seven weeks. Neon (xhigh) scores 61 on the Artificial Analysis Intelligence Index, 1 point ahead of Gemini 4 Carbon (high) and 3rd overall, behind GPT-6.2 Astra (max) and Claude Fable 5.2 (max). At high effort, Neon matches Carbon (high) at less than half the Cost per Task using Carbon’s standard (non-discounted) pricing. Key takeaways: ➤ Slight improvement in Intelligence for lower Cost and Time per Task: Neon (xhigh) scores 61 on the Intelligence Index, 1 point ahead of Carbon (high), with small improvements in agentic knowledge work, visual reasoning and coding. It costs $6.44 per task, ~17% less than Carbon ($7.76 at non-discounted pricing), and takes ~21 minutes per task, ~40% less than Carbon (~36 minutes). Neon uses ~15% more output tokens per task, so the lower cost comes purely from its 25% lower token prices ($3/$15 vs $4/$20 per 1M input/output tokens), and the lower time from its higher output speed (~110 vs ~57 output tokens per second) ➤ Competitive with Claude Opus 5.5 and Claude Fable 5.2 on coding agents: With Antigravity CLI, Neon (xhigh) scores 59 on the Artificial Analysis Coding Agent Index, 3 points ahead of Carbon (high, 55). It scores in line with Claude Code with Claude Fable 5.2 (xhigh, 58) and Claude Opus 5.5 (max, 58) at a much lower Cost per Task. Gemini 4 Neon in Antigravity has an average Cost per Task of $6.86, compared to $12.61 for Claude Opus 5.5 (max) and $15.47 for Claude Fable 5.2 (xhigh). Neon is available in Antigravity CLI for Pro and Ultra subscribers ➤ Significant improvements in visual reasoning and output presentation quality: In GDP.pdf, Gemini 4 Neon (high) scores 33.4%, 5 points above Carbon (high, 28.4%) and in line with the highest scores measured, while Neon (xhigh) scores 28.0%. On AA-Briefcase, Neon (xhigh) scores 1700 Elo overall and leads on Presentation Quality with 1771 Elo, 45 points ahead of the previous leader Claude Sonnet 5.5 (max, 1726). On Google’s Multimodal Knowledge Agent evaluation (MKA), Neon reaches a Climb WSR of 56%, up 2 points from Carbon and on par with the leader, Claude Fable 5.2 (max, 57%) Key model details: ➤ Context Window: 1M tokens ➤ Multimodality: Text, image, video, and speech input, with text output ➤ Availability: Gemini 4 Neon is publicly available at launch through Google’s API. Pro and Ultra subscribers can also access it in Antigravity and the Gemini app ➤ Effort levels: Gemini 4 Neon offers four effort levels (low, medium, high, and xhigh) - xhigh was introduced to Gemini models in the recent Hydrogen release ➤ Pricing: $3/$15 per 1M input/output tokens, 50% above Gemini 4 Carbon’s currently discounted price of $2/$10 (which ends on November 30), and 25% below its standard $4/$20. Cached input tokens receive the same 95% discount ($0.15)
1
37
n=1s, different prompts, we did not rerun them: ▸ @notjazii, pixel-art city vs opus, highest reasoning: ~$3.5 / 20 min vs ~$7.2 / 18 min. his call: opus still did better ▸ a separate @notjazii prompt vs sol: ~$1.6 / 20 min vs ~$0.53 / 9 min ▸ @carlosrodera_, one coding brief: neon high 5m53s ≈ $1.40, sonnet 24m52s (tokens not exposed), both passed lead tests. sonnet ran on a shared mac under safety hooks, neon in its own sandbox, and a wider sweep (2,417 vs 398). not a clean 4.23×. aa's article calls neon #3 overall, behind astra and fable 5.2 (page header also showed #6/96). google's "50–80% cheaper" is a vendor line; aa has neon at ~1.6× astra's $4.00 per index task. fine print: neon cache $0.15 (implicit only on the developer api). sol/sonnet cache $0.10, opus $0.20. vertex non-global is +10%. prompts over 200k can move onto a 1.8× long-context card ($5.40/$27 global). not on the free gemini api tier.
1
2
37
list price is not cost per task. official standard list, per 1m: neon $3/$15, sol and sonnet 5.5 $2/$10, opus 5.5 $4/$20. aa cost / time per index task, v5.0.1, top setting: ▸ neon xhigh: 61, $6.44, 21.5 min ▸ opus 5.5 max: 59, $10.04, 24.5 min ▸ sol max: 57, $1.01, 7.9 min ▸ sonnet 5.5 max: 55, $10.02, 32.6 min sonnet's list is half of opus. the aa bill is basically a tie (335m vs 218m output tokens). sol is the cheap one of the four. neon is cheaper than opus per task. not cheaper than sol.
1
2
63
tokenized stocks this week, demand vs supply: ▸ demand: binance wallet's tokenized anthropic pool hit its $500m usdc cap ~4h into an 8h window ▸ supply: okx x ice picked 62 companies for its 24/7 venue. 56 objected ▸ so it opens monday w/ mostly crypto names (coinbase, circle, strategy, robinhood) + 59 direxion etfs users clearly want it. issuers don't. who blinks first?
74
usage is compute-based (5-hour refresh, weekly cap). no published "n free tasks/day." free schedules: at most once a day, 10 active. max 15 tasks at once. calling isn't in IN, LA, MN, MT, or NE. elsewhere: google ai pro or ultra. blog.google/innovation-and-a… support.google.com/gemini/an…
1
90
that's tasks in gemini (chat → task, gemini 4 hydrogen), not the whole app, not google tasks. 18+, personal account, history on. not work/school. "for now" — no published end date. calling, pay, email, and sms start in the us. still out: eea, uk, switzerland, nigeria.
Put Gemini to work for you with Tasks. While Chat is for quick back-and-forth answers, Tasks are for longer projects and recurring schedules. Beginning today, Tasks are now free of charge for hundreds of millions of eligible users, starting in the U.S., JP, KR, CA, AU & IN. 🧵

1
1
46
n=1, per @notjazii (xbox-controller, max reasoning, quality as a poll): sol $0.53 / 9 min, astra $1.24 / 38 min, opus $7.49 / 20 min. cost direction matches aa; 38 min does not (aa: 10.7 vs 24.5). not a coding bench. teapaw.org/ArtificialAnlys/status… teapaw.org/notjazii/status/212278…
GPT 6.2 vs Opus 5.5 tested all three models with same prompt at max reasoning and results are here > 6.2 sol took 9 mins and cost $0.53 > 6.2 astra took 38 mins and cost $1.24 > opus 5.5 took 20 mins and cost $7.49 i’ll let you all judge which one did better in this test
1
18
official list (standard, short context, per 1m): sol $2/$10, astra $8/$40, opus 5.5 $4/$20. list ≠ cost per task. per @ArtificialAnlys (max): sol $1.01 / 7.9 min / 57, astra $4.00 / 10.7 min / 62, opus $10.04 / 24.5 min / 59. opus costs more per task because it's more verbose
1
1
24
anthropic priced at $83, $5 above the range. the @tradexyz ANT perp is at $100.2 right now, before a single share trades on nasdaq ▸ that's +21% over the ipo price ▸ $174m open interest, $99m traded in 24h ▸ it sat at $96-99 all of yesterday, the pricing news barely moved it onchain already priced the day-one pop. later today nasdaq tells us if it was right
1
1
119
tokenized assets, per @JupiterExchange's coo at breakpoint: ▸ $460bn tracked (rwa.xyz) ▸ $39.5bn can actually leave the issuer's platform ▸ $3.4bn used in defi (defillama) meanwhile @tradexyz on hyperliquid carries ~$4bn of open interest in stock and commodity perps, with zero shares tokenized. traders want the exposure. the wrapper is optional.
33
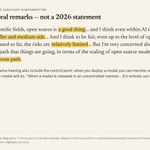
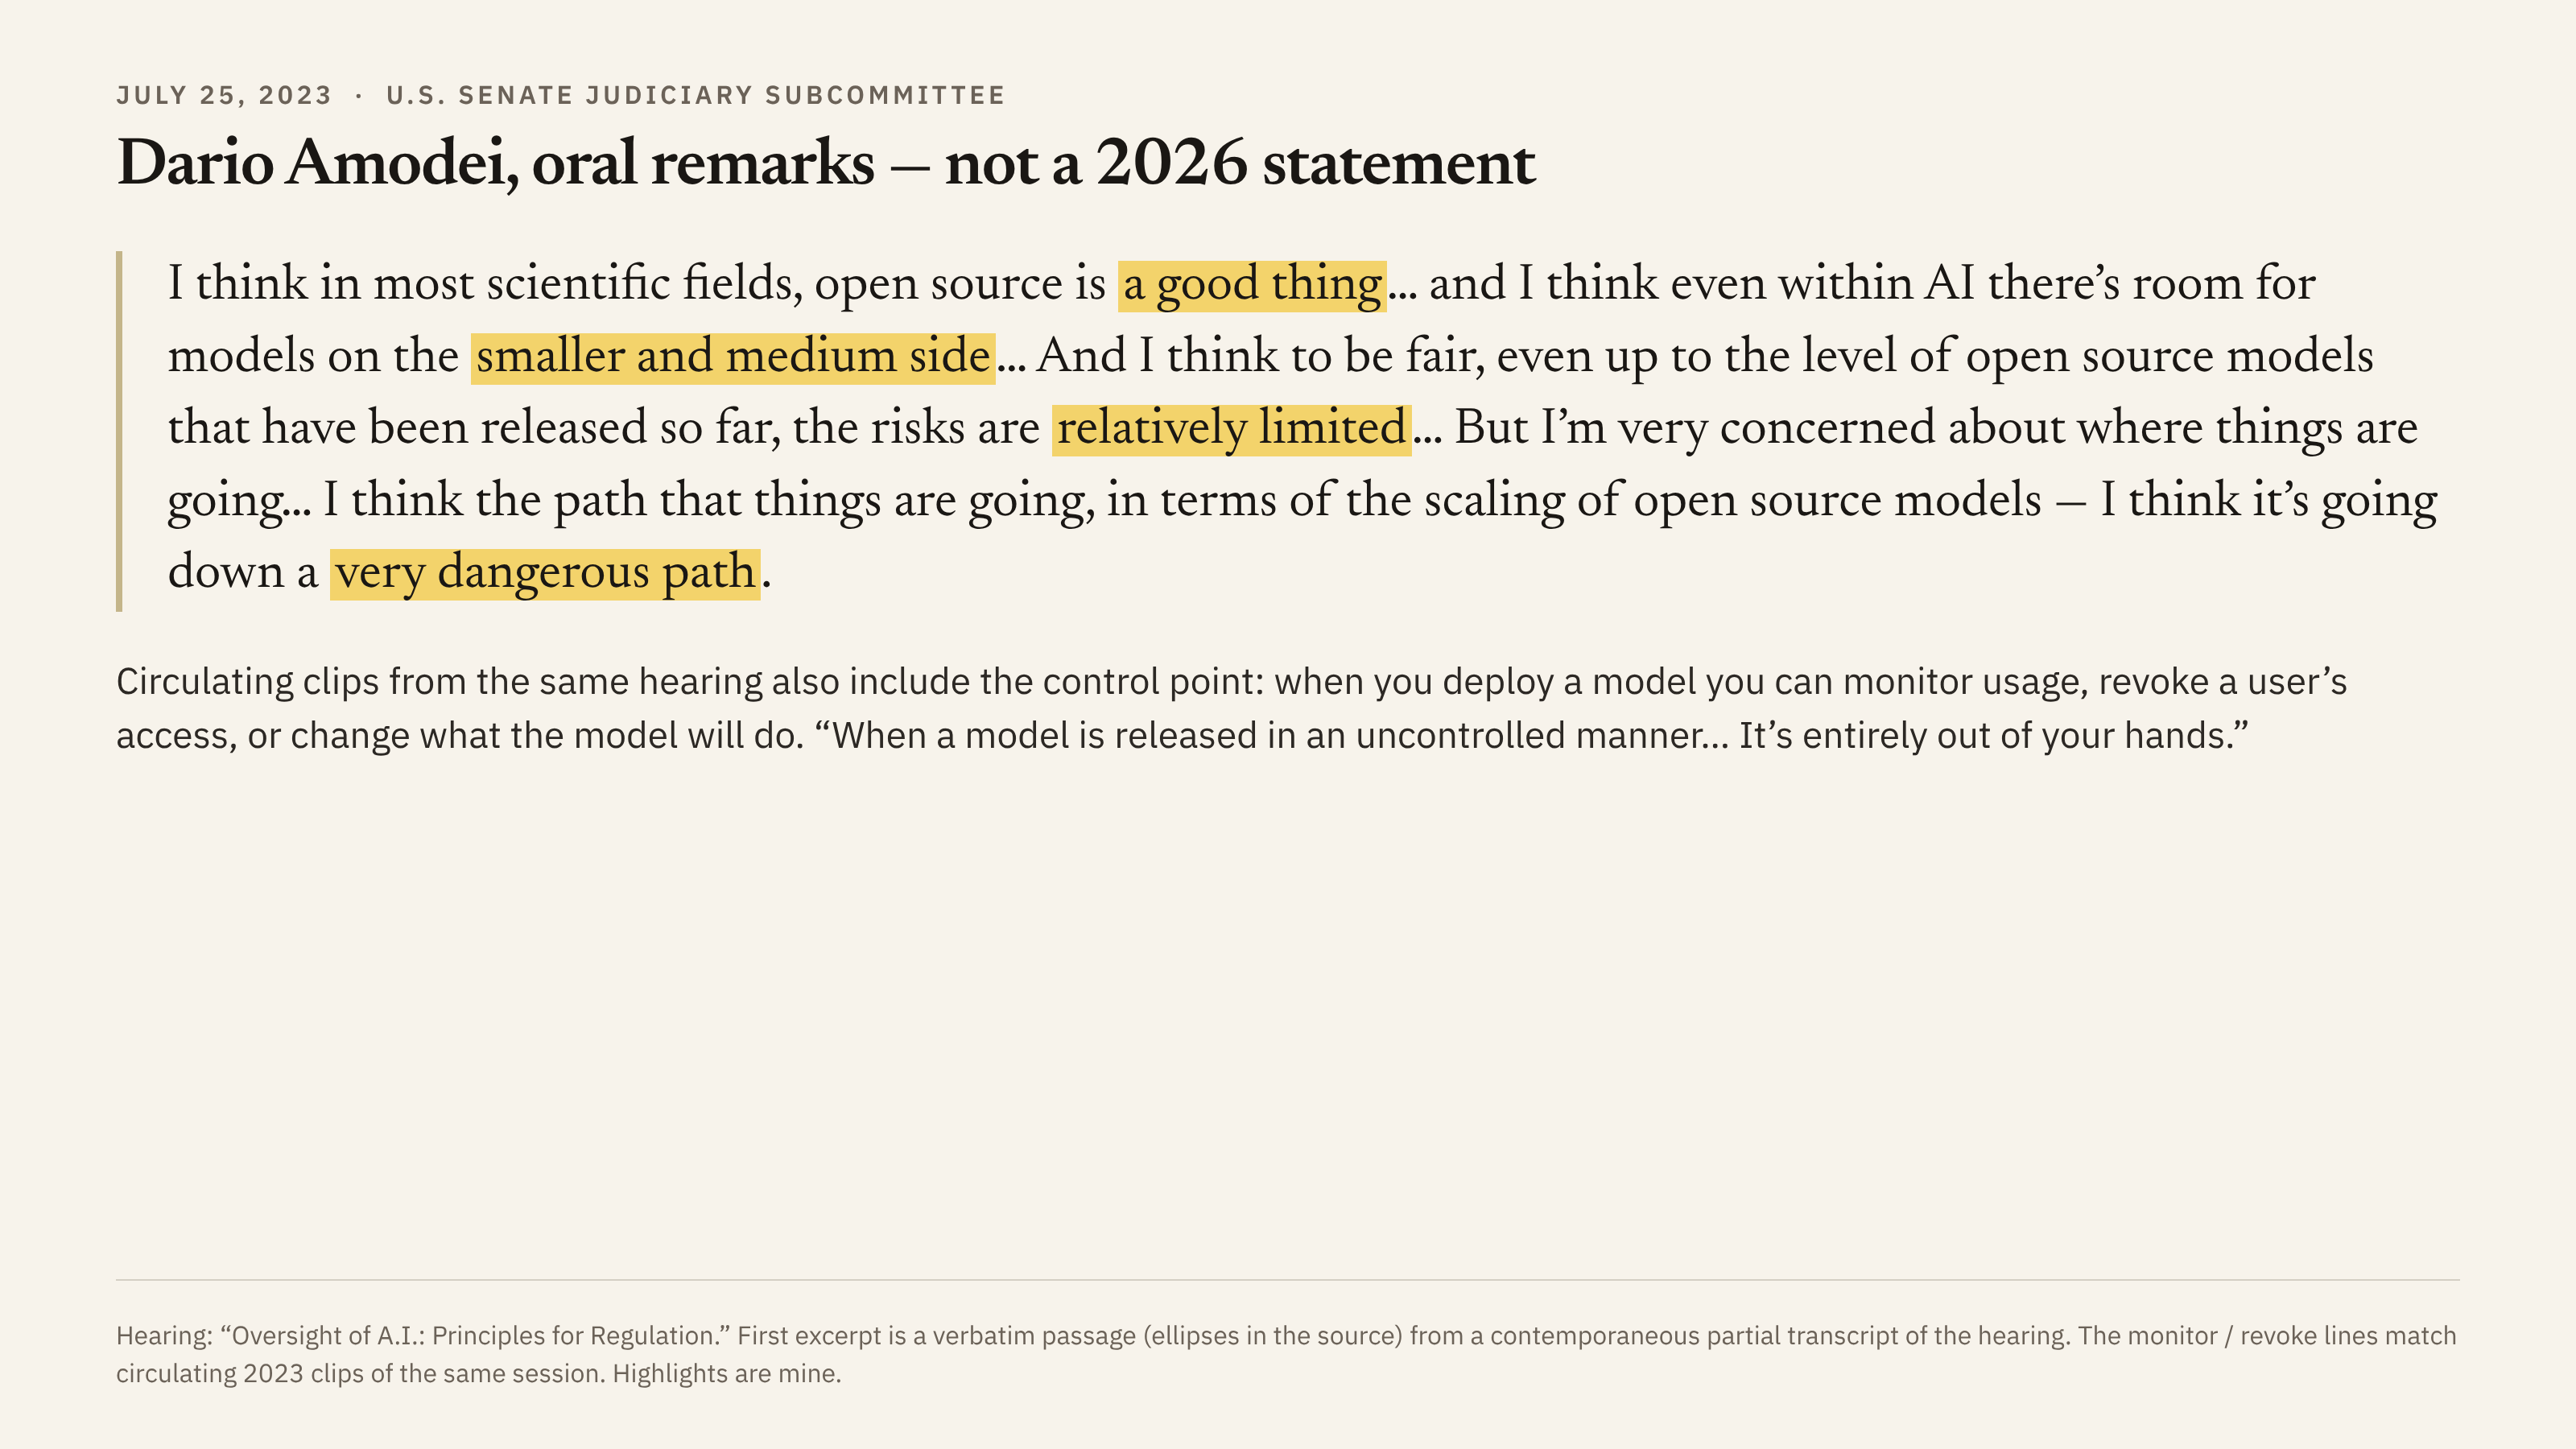
this clip is from july 25, 2023, not a new remark. he also said open source is "a good thing" in most scientific fields, and that models already out then had "relatively limited" risks. the warning was the scaling path. that's why open weights matter for indie products.
Dario Amodei on open source models: “If the path continues, I think we could get to a very dangerous place.” “When you control a model and you're deploying it, you have the ability to monitor its usage.” “You can revoke a user's access. You can change what the model is willing to do.” “When a model is released in an uncontrolled manner, there's no ability to do that. It's entirely out of your hands.” “We should confront the advocates of this with that problem and challenge them to solve it.” He clearly doesn't believe Intelligence should be in the hand of the masses and Sam Altman also saying "RAM" shouldn't be accessible to everyone indefinitely agreed with him.
1
3
82
50% off on tokenhub until nov 30, 12:00 beijing (official). openrouter now shows $0.035/$0.1405. per @opencode (nov 16): free on opencode / go for 14 days visual/design downsides: @malexc_ai, @loading_X__ tencentcloud.com/document/pr… teapaw.org/AiHubMix/status/212232… teapaw.org/opencode/status/212223…
Hy4 flash is free with near-unlimited usage for the next 2 weeks 1M context · Multimodal · ZDR Hy's fastest and most cost-efficient model
1
94
the official 18x is vs haiku 5.5 (high), not vs deepseek. same 85-user, 259-task test: deepseek scored higher (3.09 vs 2.79), cost ~4.6x more, took 10.3 vs 6.7 min list: $0.07/$0.281 vs deepseek $0.15/$0.60 off-peak. n=1, per @AiHubMix credits: 20 min / $0.13 vs 50 min / $0.40
⚡Meet Hy4 flash, the cheapest model for everyday productivity. Matches Claude Haiku 5.5 (high) on daily work (human blind tests), yet 18x task cost reduction. API pricing (per 1M tokens): $0.003 cached · $0.070 input · $0.281 output. 🔗:hy.tencent.ai/research/hy4-f…
1
1
102
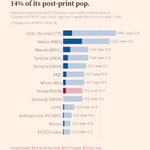
nvidia did $115.8bn vs a $108bn guide, then guided $130bn (street was $124.8bn per visible alpha). the $NVDA perp on hyperliquid kept 14% of the pop. ▸ $155.66 at the 4pm et close → $163.76 peak → $156.82 now ▸ $95m traded in the 5 min after the print, $509m since the close ▸ same fade across ai perps: $SOXL +14.2% at peak, +2.4% now a $130bn guide is a +0.7% stock overnight. cash opens 9:30 et.
106
nvda reports in ~80 min. first print since jensen resigned, and kress runs the call as interim ceo while still cfo their own guide was $108bn ±2% what actually moves the stock tonight? ▸ data center rev vs that guide ▸ the q4 guide ▸ any word on the ceo search ▸ nothing, it's priced in
2
59