
Local LLM V100 96G & enjoy Omarchy; Tday https://xitter.cf/t.co/P6K9F7LvIO ; CODELF (Github star 14k); MIHTool (Mentioned in Google I/O'13)
Los Angeles, CA
Joined January 2008
- Tweets4.7K
- Following395
- Followers2.5K
- Likes1.3K





Pinned Tweet
We just hit 300 members today—woke up to 100+ new people joining overnight. Come join these top DIY hackers using extreme optimization to make old hardware run Qwen3.8-Flash and GLM5.3-Flash. 🚀xitter.cf/i/chat/group_join/g209…


Just a bit of insight: people are eager to build their own rigs for local LLMs, the same way we were obsessed with building gaming PCs 30 years ago. xitter.cf/i/chat/group_join/g209…


This is my always-on dashboard for watching local LLM resource usage—VRAM, RAM, power, TPS, all in one place. Full screen, it looks awesome.

Holy shit—even NVIDIA’s incremental, toothpaste-squeezing generational upgrades haven’t delivered a jump this big. At this rate, used GPU prices might end up matching new GPU prices.
github.com/Zagitta/gpu-unloc…


It really works—decode gains are up to 40%, power draw is cut by 45%, and my 256GB RAM is finally earning its keep. Thanks!


"Strata is 1.8x slower on DeepSeek" - I measured it, and I was right. Until one flag: --mmap-experts off → 12.9 → 28.6 tok/s, now faster than Maya on decode. Same code, same box, same weights. The bug wasn't the engine, it was the engine's guess about your RAM. below the table

ALT Strata 0.2.4.2, IST-DAS 2.25 bpw · auto = streams from NVMe · --mmap-experts off = copies 11,666/12,983 experts into RAM (113 GB) · RTX 5090, 121 GB RAM, 24 Oct 2026.

DeepSeek V4.1 Flash is an absolute power killer—2× the power draw of Qwen3.8-Flash.

First 4×V100 + Strata + DeepSeek benchmark is wild: even at 1M context, prefill 1k TPS beats llama.cpp + Qwen3.8-Flash by literally 4×, with no tuning yet. That’s why I waited for Strata—several engines can run V100 + DeepSeek V4.1 Flash, but honestly, I trust @coldniko (even if he forgot to follow me back 😁).


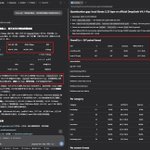
WTF! I had official DeepSeek V4.1 Flash 1017 run a full eval of @mhelcig’s local GSQ-RCO IQ2_XS to measure the gap vs. the full-weight model. 1.5 hours and 367 tasks later, both passed everything—and the full-weight version actually scored a hair worse than IQ2_XS. Even the full model won’t accept that result.😅

First 4×V100 + Strata + DeepSeek benchmark is wild: even at 1M context, prefill 1k TPS beats llama.cpp + Qwen3.8-Flash by literally 4×, with no tuning yet. That’s why I waited for Strata—several engines can run V100 + DeepSeek V4.1 Flash, but honestly, I trust @coldniko (even if he forgot to follow me back 😁).
First 4×V100 + Strata + DeepSeek benchmark is wild: even at 1M context, prefill 1k TPS beats llama.cpp + Qwen3.8-Flash by literally 4×, with no tuning yet. That’s why I waited for Strata—several engines can run V100 + DeepSeek V4.1 Flash, but honestly, I trust @coldniko (even if he forgot to follow me back 😁).

ModelScope hasn’t synced the GSQ-RCO GGUF for DeepSeek-V4.1-Flash-1017 yet, so I’m downloading from three other mirrors at the same time—and the speed is just as good as ModelScope’s.


We’re hitting 400 members this week! Join us and let’s rock local LLMs together. 🚀
We just hit 300 members today—woke up to 100+ new people joining overnight. Come join these top DIY hackers using extreme optimization to make old hardware run Qwen3.8-Flash and GLM5.3-Flash. 🚀xitter.cf/i/chat/group_join/g209…
China actually has plenty of homegrown inference GPUs, but prices haven’t dropped as expected—and they’re still not great for local LLMs. Literally one big reason: no CUDA. Without the ecosystem—PyTorch, kernels, quants, llama.cpp/Strata support—local LLM tinkering gets way harder.


