
Robotic Embedded Systems Laboratory @USC
Los Angeles, CA
Joined June 2009
- Tweets109
- Following47
- Followers325
- Likes23




USC RESL retweeted

🤖 Ever wondered if you can train end-to-end humanoid policies entirely within a differentiable simulator?
🥁 Introducing 𝗕𝘂𝗻𝗱𝗹𝗲𝗱 𝗖𝗼𝗻𝘁𝗮𝗰𝘁 𝗚𝗿𝗮𝗱𝗶𝗲𝗻𝘁𝘀 (𝗕𝗖𝗚)
🌐: bundledcontactgradients.gith…
📄: arxiv.org/abs/2609.30951
🧵👇
Project website: dcodaaug.github.io/D-CODA/
Paper: arxiv.org/pdf/2505.04860
Authors: @arthur801031, @jasoon_chen, @gauravsukhatme, @daniel_t_seita
End thread🧵
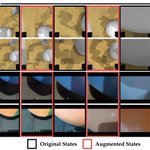
The original states are augmented every k time steps, resulting in out-of-distribution states. The non-augmented states remain in-distribution and guide the behavior cloning policies to complete the tasks.


Excited to announce our #RSS2025 workshop:
Resource Constrained Robotics
Discover how robotics thrives under constraints — from limited compute to smarter algorithms enabling real-time, low-power autonomy.
📅 June 21 | 📍 Los Angeles, CA
🔗 sites.google.com/view/rc4rob…

Blog post: rasc.usc.edu/blog/voxact-b/
Project website: voxact-b.github.io/
Paper: arxiv.org/abs/2407.04152
Code: github.com/VoxAct-B/voxactb
Authors: @arthur801031, @SichengHe12345, @daniel_t_seita, @gauravsukhatme
End thread🧵