

Building the neovim of agent harnesses. bone-agent. 26, swe in finance.
New York, USA
Joined April 2026
- Tweets3.6K
- Following344
- Followers323
- Likes3K






Pinned Tweet
Qwen3.8 flash at 150–177 tok/s gen and ~1,900 tok/s prefill on 2x 3090s + 96gb ddr5
bone engine, my own inference engine. 256k context, single stream or 4x concurrent (50ts a stream, up to 256k)
vs strata engine on the same rig: 120-140gen, 1k pp → 150-170gen, 2k pp
iq3_xxs quant, so not full precision, will optimize q4 once qwen 4 drops. Model is leftover from when i had less ram.

🎉🎉 Woohooo 300 followers, we are growing quick. Follow for more of my local ai and harness building journey

9
18
288
Im having fable rewrite every system gui (app picker, task bar, settings, panels, etc on my arch machine to match just bc I cant burn through the limits. Here is my system monitor hover graph

1
39
Trading strat will be buy when gpt is winning, sell into opus 6 pop. Rinse repeat

Our initial public offering: ipo.anthropic.com
Legal disclaimer: Anthropic has filed a registration statement (including a prospectus) with the SEC for the offering to which this communication relates. Before you invest, you should read the prospectus in that registration statement (available at: sec.gov/Archives/edgar/data/…) and other documents Anthropic has filed with the SEC for more complete information about Anthropic and this offering. You may get these documents for free by visiting EDGAR on the SEC Web site at sec.gov. Alternatively, copies of the preliminary prospectus may be obtained from: Goldman Sachs & Co. LLC, Attention: Prospectus Department, 200 West Street, New York, NY 10282, by telephone at (866) 471-2526, or by email at [email protected]; or Morgan Stanley & Co. LLC, Attention: Prospectus Department, 180 Varick Street, 2nd Floor, New York, NY 10014.
The securities may not be sold, nor may offers to buy be accepted, prior to the time the registration statement becomes effective. This post is not an offer to sell, or a solicitation of an offer to buy, the securities in any jurisdiction where the offer or sale is not permitted.

1
63
Rambone retweeted

Tried training a language model from scratch with pure RL today
Everything became kawasaki

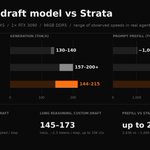
Trained a custom dflash draft model for Qwen3.8 Flash. Prefill is now up to 2,436 tok/s, 2.4x Strata.
Same 2x 3090 rig, real agentic sessions:
- Strata: 130–140 gen, ~1,000 prefill
- Bone + Strata MTP: 157–200+ gen, ~1,900 prefill
- Bone + custom draft: 185–215 on tool calls, 145–173 on long reasoning, 2,000–2,436 prefill!
Generation is only slightly ahead of MTP. Draft acceptance drops to ~2.3 tokens/step on long thinking, so the realizable gain is prefill and tool calls.
Next step is training the draft on more reasoning traces, hopefully it makes some different. Keeping my room toasty.

1
77
Gemini 4 Carbon is the most concise model i have ever used
It gives me MAX 3 sentences of explanation when I ask it for a review. Its almost annoyingly concise but great for when im working and cant be asked to read.
*custom harness that does say to be concise on the system prompt
2
8
213
In 10 years there won't be anyone in an ai lab under the age of 35. Gen z will crucify you if they find out you used gpt
2
69
Fable 5.2 spent all night training a drafter for qwen flash 3.8 on my 3090s. Surprised it didnt get blocked or downgraded.
54
One line in a config cut my agent's answers 72%. Another made explanations 3.3x longer.
I simply added a new behavior plugin for bone (harness), tested each knob alone on qwen3.8 flash, 3 reps:
- conciseness: 172 to 48 chars
- detail: 628 to 2,100 chars
- comments off: 2 to 0, every rep
- read before edit: 3/3 blind edits blocked, model read the file and fixed it
When I started making harnesses over a year ago the system prompt was CRUCIAL for behavior. Then labs started training the models within the harness and they learned to behave properly without a system prompt.
Adding back behavioral notes, I thought would make no different (we all have told claude to stfu and it doesnt) but to my surprise qwen flash took really well to these instructions at lower contexts.

1
55

Claude releases a ton of claude powered apps but I never hear of any actually being used outside code and desktop. Do they just kill them off? Didn't we have claude design already? Where is that. Why not one claude app

200+ tok/s on tool calls, ~160+ on prose. A real agentic session, not a synthetic bench
qwen3.8 flash on my own engine. 2x 3090 + 96gb ddr5, 256k ctx
prefill 1.6–2k tok/s, prompt cache hitting 93–100% between turns
Thanks fable 5.2 for squeezing a few extra %, im at the edge of what's capable on this hardware now without a custom trained drafter

2
3
132
Fable 5.2 made a bunch of tiny tweaks to my gui app that made it feel so much more polished that opus 5.5 missed. Its a different beast.
1
48