

🎨 Artist by day 🌙 Creative Coder by night Computational Artist circa 2016 | PromptEngineering | LLMs | OpenSource | Linux | Computational Muralism
NorCal
Joined January 2016
- Tweets3.1K
- Following370
- Followers720
- Likes10.7K



Full methodology and caveats: github.com/Visual-Synthesize…

MiniMax-M2.7 NVFP4: 127.7 tok/s C=1, 2800 peak C=128
2x RTX PRO 6000 Blackwell, SGLang b12x 0.8.3, TP=2.
Prefill 17,286 tok/s @ 8K → 9,908 @ 128K.
No spec decode (no drafter yet — when one ships, low-C numbers should jump).
Thanks @lukedobl for the quant + kernels.

**All data is public:**
- Results & methodology: [github.com/Visual-Synthesize…](github.com/Visual-Synthesize…)
- Raw benchmark JSONs: [github.com/Visual-Synthesize…](github.com/Visual-Synthesize…)
- 3-run verification data: [run1](github.com/Visual-Synthesize…), [run2](github.com/Visual-Synthesize…),
[run3](github.com/Visual-Synthesize…)
198 tok/s on Qwen3.5-122B with 2 GPUs
148 tok/s on M2.5 (229B)
79 tok/s on Qwen3.5 397B (full GGUF)
~15% faster than a WRX90 Threadripper build on the same stack.
Stack:
122B NVFP4 — 198 tok/s (SGLang b12x + NEXTN)
27B FP8 — 170 tok/s (DFlash drafter)
229B NVFP4 — 148 tok/s (vLLM b12x)
397B GGUF — 79 tok/s (llama.cpp)
Hardware:
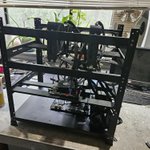
ASRock Rack B650D4U (AM5)
EPYC 4564P (AM5)
PLX switch
2x RTX PRO 6000
3-run verified: 197 / 200 / 198
Reproducible. Link in comments.

Local AI in 2026 vs 2020.
Same energy. ~198x the intelligence.
Cables got worse (waiting on shorter cables). Benchmarks got better.
198 tok/s | Qwen3.5-122B | 2 GPUs | no NVLink
148 tok/s | MiniMax M2.5 229B | vLLM b12x
79 tok/s | Qwen3.5 397B | GGUF llama.cpp
Build:
$2K AM5 ASRock Rack B650
$3K PCIe switch
2x RTX PRO 6000 Blackwell
Result:
Beats $33K Threadripper builds by ~18% on the same stack
Open-weight + local is not just speed.
It is:
• privacy
• data sovereignty
• control
Some work should never leave the machine.
yeah its rough, i decided just to stay on my old gen4 threadripper. it already had 256gb ram. its a tiny bit slower for AI inference on blackwell 6000s- but paying for rd-dimm right now is crazy. thats like the cost of another blackwell 6000.
also playing around with AM5 servers soon. only 1 gen5pcie slot, but it might not matter for my workflows.
i was using MJ before it was even named, helped build datasets they used for aesthetic fine tuning- but I haven't touched it in years. Its not a professional art tool. Switch to open models and black box API's.
We’ll see about the timeline. At a certain point it may not matter. For example, with image generation I can already produce commercial-quality work using NanoBanana Pro or open-source models such as Flux2 or Qwen. Raw image quality is comparable. The main difference is workflow control and platform restrictions (censorship). Open-source models perform far better when a project requires a high degree of control or multiple revision cycles. For simple probabilistic generation with minimal creative direction, black-box systems are sufficient. But for professional work, I need deterministic, iterative control loops.
yeah! So true. im really interested in deterministic art systems with generative assistance. constantly inspired by the creativity of the community.
sadly its a cultural issue and a legal issue. Open source will catch up in a few months though so seedance wont really matter for long
anyone saying its nerfed doesnt understand the tech stack. its filtering done pre or post generation for safety and regulation.
its great until its not. ever actually used it on commercial work? the censorship makes it hard to take black box models seriously.


