
phd @Tsinghua_Uni, intern @Apple, prev @SenseTime_AI, @MSFTResearch, @zhipu_ai
Joined November 2022
- Tweets10
- Following127
- Followers25
- Likes2



Pinned Tweet
🚀 Can we build a VQ-VAE without training one?
Our ICML 2026 paper introduces Gaussian Quant (GQ):
✅ Train only a Gaussian VAE
✅ Convert it into a VQ-VAE without any additional training
✅ Random Gaussian noise codebook
Paper: arxiv.org/abs/2512.06609

Tongda Xu retweeted

Does GenAI create new knowledge? arxiv.org/abs/2602.06021 gives
* 1st explicit characterization of diffusion model's generalization
* more precise than offered by classical stat. learning theory
* systematic integration of various inductive biases (training+architecture+inference)


Introducing interpolated FID: an variant of reconstruction FID that is highly correlated to diffusion generation FID.
It is well known that VAE rFID is not correlated with diffusion gFID. We propose a simple variant that achieves correlation 0.9!
huggingface.co/papers/2603.0…

code: github.com/tongdaxu/Making-r…
paper: arxiv.org/abs/2603.05630

55
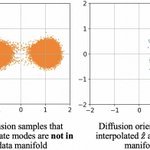
We provide an explaination for why reconstruction correlates negatively to gFID, by showing that the latent space optimized for reconstruction prefers separable modes, which leads to halluciation.

53
We provide an explanation for why iFID correlates well with gFID, and why reconstruction metrics are negatively correlated with gFID, by showing that latent space with low iFID avoids hallucation brought by mode interpolation.

53
For each element in the dataset, we retrieve its nearest neighbor (NN) in the latent space and interpolate their latent representations. We then decode the interpolated latent and compute the FID between the decoded samples and the original dataset.
44
And to be appear in #ICLR2024

A year later we finally scale this idea up to 256^2 images. Though the technical approach is kind of different from DiffC. We use inversion to replace correlation communication to make a real codec.
Preprint: arxiv.org/abs/2401.08920
Code: github.com/tongdaxu/Idempote…
1
132
A year later we finally scale this idea up to 256^2 images. Though the technical approach is kind of different from DiffC. We use inversion to replace correlation communication to make a real codec.
Preprint: arxiv.org/abs/2401.08920
Code: github.com/tongdaxu/Idempote…

