

a little bit of everything: #iOS #jailbreak #AI #ML #crypto #web3 #MEV #graphicdesign #NFT
Joined September 2013
- Tweets369
- Following630
- Followers38
- Likes506



DDd retweeted

We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: rikiyat.github.io/blog/weigh…

Readers added context they thought people might want to know
LLM was given weights explicitly as text in prompt and used code/forward passes (per authors' logs) to ablate Qwen looping direction, a known thinking-mode issue per model card. Primarily fixed repetition in that mode, not general 'natively' improving weights/math.
rikiyat.github.io/blog/weight-sp…
github.com/RikiyaT/lm_und…
huggingface.co/Qwen/Qwen3.5-0…
huggingface.co/RikiyaT/Qwen3.…
DDd retweeted

1/4
Meet Qwenputer: Qwen3.5-4B with a full RISC-V CPU inside its weights, using the model's own Gated DeltaNet layers as RAM.
It runs C and MicroPython in its forward passes, no external runtime.
On DeepMind math: base 55–90%, base + Python tool 95–100%, Qwenputer 97.5–100%.
DDd retweeted

Introducing Reality-Aware Rendering in @Simulon, a completely new way to create with the real world.
Place neural assets with your phone and act out the scene. When you stop recording, Simulon renders the take, reading everything in it (what you do, what you say and the place around you), and your assets respond to all of it.
The final is regenerated from your recording: a new performance of the scene, not a copy of the footage.
Available now on iPhone. Coming to Android soon.
DDd retweeted

ethereum:0xaea46a60368a7bd060eec7df8cba43b7ef41ad85 - Update
Very important level to pay attention to here


DDd retweeted

Meet Qwen-Image-2.1, the most balanced and cost-effective image generation model in the Qwen-Image series! Now open weights! 🎨
A unified model for both generation and editing, delivering top-tier quality in a lightweight package.
Highlights: 👀
- Compact & exceptionally fast: A lightweight 7B architecture that outperforms most closed-source models, with drastically accelerated inference for multi-image inputs.
- Native transparency: Natively generates and edits RGBA layers, enabling seamless compositing and text editing within transparent images.
- Versatile, high-fidelity editing: Supports up to 10 reference images and precise local control while preserving strict fidelity for portraits and products.
- Broad coverage & stunning aesthetics: Excels at panoramas, infographics, and virtual try-ons, delivering realistic textures and elegant typography.
Start to create your next masterpiece with Qwen-Image-2.1! 🖼️
- Blog: qwen.ai/blog?id=qwen-image-2…
- GitHub: github.com/QwenLM/Qwen-Image…
- Model Scope: modelscope.cn/models/Qwen/Qw…
- Hugging Face: huggingface.co/Qwen/Qwen-Ima…

DDd retweeted

Today, we’re announcing Ternary Bonsai 2 27B.
Based on Qwen3.8 27B, Bonsai 2 27B is 9x smaller than its full-precision counterpart while retaining 98.2% of its aggregate benchmark performance.
Two months after the first Bonsai 27B release, the biggest change is quality. The footprint remains 5.9 GB, but the gap to full precision has narrowed materially, with particularly strong gains in agentic coding, multimodal reasoning, and long-horizon tool use.
Ternary Bonsai 2 27B is available today under Apache 2.0.

DDd retweeted

Pre-built Jailbroken iOS 26 iPhone fully runs on browser.
Full virtual iPhone ready-to-run jailbroken iPhone (rootless + Sileo + Filza + TrollStore vibes).
Just download, Test tweaks, exploit PoCs, and debug without touching your daily driver. 😗
Live screen Touch, Home,Power, Volume. IPA + TIPA install, Root shell, File browser, Multi-user RBAC.
Not a simulator A research VM you can actually poke.
- github.com/34306/vphone-web

DDd retweeted

Lucida from ByteDance
Cool project! It transforms indoor video into editable 3D scenes; reconstructs objects as simulation-ready assets
- VLM-based object detection and referring descriptions.
- good at pose alignment
- high-fidelity real-to-sim digital twins.
- multi-view masks, boxes, partial point clouds
- Seed3D 2.0 for image-to-3D asset gen
lucida-r2s.github.io/


DDd retweeted

Introducing Atlas:
The world's first multimodal world model that generates image and video frames with pixel-perfect camera control and reconstructs them in 3D.
Model the world, move the camera, and simulate space & time.
DDd retweeted

Your gaming PC can now serve frontier models at interactive speed using official checkpoints without extreme quantization!
Qwen3.6 35B → 8GB RTX 4060 laptop @ 39 tok/s
DeepSeek-V4-Flash 284B → RTX 5090 desktop @ 22-25 tok/s
GLM-5.2 753B → RTX PRO 6000 workstation @ 15 tok/s
Run your claude code or codex now with frontier model for $0
Meet FreeToken 🧵
DDd retweeted

I spent 67 hours of model time to find out how much dumber 4 bit really makes Qwen3.8-27B.
FP8 vs NVFP4 vs AWQ INT4 vs GGUF Q4_K_M vs NInfer on my 4x RTX 3090. 4,800 tasks, 10,120 requests, 14.5M reasoning tokens, no token caps anywhere.
The results surprised me. Big thread, lets go 🧵

DDd retweeted

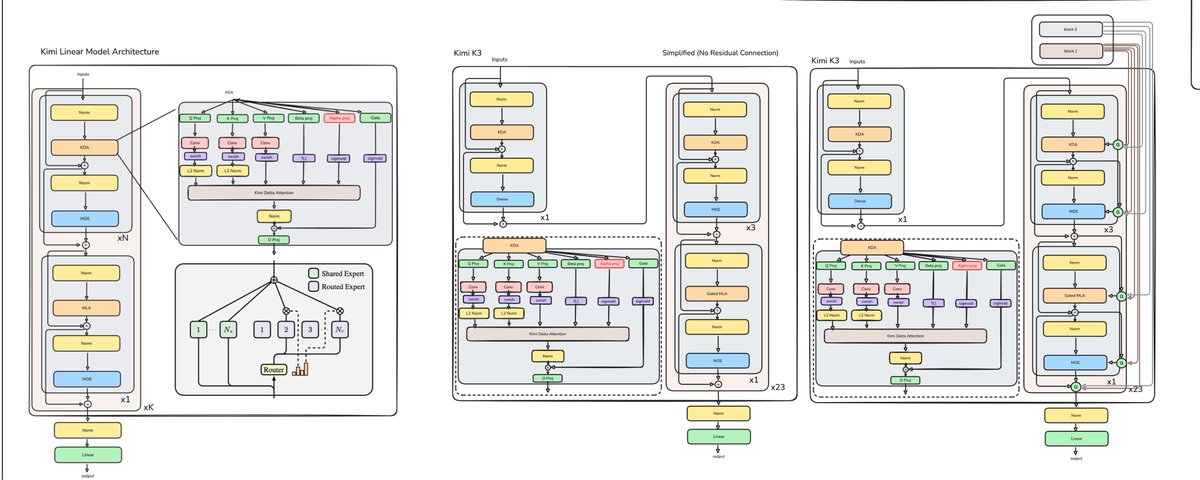
I spent 48 hours with the Kimi K3 modeling code.
It took:
- 650 mg of caffeine (mandatory)
- 40 cans of LaCroix (optional... world record (?))
- 8 papers
- 6 months off my lifespan
Finally grokked the entire lineage of Kimi K3 and how we got here... every single step, since 2019 GPT-2

DDd retweeted

we got the full Kimi K3, 2.8T params, running on 80x RTX 5090s.
20 tok/s single stream, day one, untuned. Last week we took GLM-5.2 from 30 to 110 tok/s on this same fleet. This number will climb.
A first for open weights: frontier intelligence served with zero HBM, the scarcest silicon in AI. Just GDDR7 gaming cards, plain ethernet, and the official MXFP4 weights, nothing requantized.
The most powerful open model on Earth, on the most abundant GPUs on Earth. Any lab, startup, or university can now own it, probe it, fine-tune it, run agents on it.
@Kimi_Moonshot


Releasing the model weights and technical report of Kimi K3.
Kimi K3 is our most capable model: a 2.8T MoE model with native visual understanding and a 1M-token context window.
New model architecture: 2.5x the intelligence per unit of compute, not just more params.
Alongside Kimi K3, we're opening up more of the stack behind it — high-performance attention kernels, MoE communication library, and infrastructure for running agent environments at scale.
Model weights: huggingface.co/moonshotai/Ki…
Tech report: github.com/MoonshotAI/Kimi-K…
Tech blog: kimi.com/blog/kimi-k3

DDd retweeted

I rebuilt FIFA's VAR offside tech run on a single camera for about $2 a match 📈
-Find pitch lines + vanishing point- HSV color matching
-Find players - RF-DETR
-Recreate the moment in 3D - SAM3D Body + 3js
DDd retweeted

📢 GenRecon Code Release 📢
Few images in → complete, high-fidelity 3D scene out!
GenRecon builds a generative prior on full scenes, resulting in unprecedented 3D reconstruction quality.
🔗 github.com/kasothaphie/GenRe…
🌐 kasothaphie.github.io/
📄 arxiv.org/abs/2605.23888
DDd retweeted

Introducing SubQ - a major breakthrough in LLM intelligence.
It is the first model built on a fully sub-quadratic sparse-attention architecture (SSA),
And the first frontier model with a 12 million token context window which is:
- 52x faster than FlashAttention at 1MM tokens
- Less than 5% the cost of Opus
Transformer-based LLMs waste compute by processing every possible relationship between words (standard attention).
Only a small fraction actually matter.
@subquadratic finds and focuses only on the ones that do.
That's nearly 1,000x less compute and a new way for LLMs to scale.

