

Research Scientist @NVIDIA | PhD @GeorgiaTech| RL and LLM reasoning
Joined September 2018
- Tweets141
- Following511
- Followers1.3K
- Likes4K





Pinned Tweet
We released Nemotron Cascade 2 30B A3B.
What makes this release especially meaningful to me is that it reflects a 1.5-year journey at NVIDIA around one core idea: improving AI math reasoning through self-improvement at test time.
Each project tackled a different part of that problem.
With AceMath (24 Q4), we built an external verifier model to identify the right solution during test-time scaling.
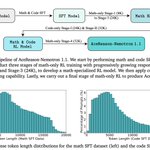
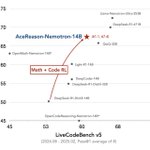
With AceReason (24 Q1-2), we scaled the reasoning capabilities of the model through RL so the model could spend more time reflecting while solving problems. Along the way, we found a general, simple and effective RL recipe that we’ve kept using since.
And now with Cascade 2 (25 Q1), we’ve pushed that effort further: the model can generate hypotheses, verify them, and refine them on its own. That self-improvement loop is what enabled IMO gold-level performance at 30B level.
From MATH500, to AIME, and now IMO Proof.
This team is THE BEST.
Technical report:
huggingface.co/papers/2603.1…


🚀 Introducing Nemotron-Cascade 2 🚀
Just 3 months after Nemotron-Cascade 1, we’re releasing Nemotron-Cascade 2: an open 30B MoE with 3B active parameters, delivering best-in-class reasoning and strong agentic capabilities.
🥇 Gold Medal-level performance on IMO 2025, IOI 2025, and ICPC World Finals 2025:
• Capabilities once thought achievable only by frontier proprietary models (e.g. Gemini Deep Think) or frontier-scale open models (i.e. DeepSeek-V3.2-Speciale-671B-A37B).
• Remarkably high intelligence density with 20× fewer parameters.
🏆 Best-in-class across math, code reasoning, alignment, and instruction following:
• Outperforms the latest Qwen3.5-35B-A3B (2026-02-24) and even larger Qwen3.5-122B-A10B (2026-03-11).
🧠 Powered by Cascade RL + multi-domain on-policy distillation:
• Significantly expand Cascade RL across a much broader range of reasoning and agentic domains than Nemotron-Cascade 1, while distilling from the strongest intermediate teacher models throughout training to recover regressions and sustain gains.
🤗 Model + SFT + RL data:
👉 huggingface.co/collections/n…
📄 Technical report:
👉 research.nvidia.com/labs/nem…

Yang Chen retweeted

Let's remove VAEs and ViTs from video models!
🚀 Introducing 𝗣𝗶𝘅𝗲𝗹𝗨𝗠𝗠: an encoder-free unified multimodal model for image and video understanding and generation, directly in pixel space.
Code and model available today!
🌐 nv-tlabs.github.io/PixelUMM
📄 arxiv.org/abs/2609.38597
Thrilled that Nemotron-Cascade has been accepted as an Oral at #NeurIPS2026! 🎉
It's our fully open-source RL recipe for LLM post-training. Huge thanks to all my amazing teammates at @NVIDIA.
model+data: huggingface.co/collections/n…


Yang Chen retweeted

worth pointing out the nemotron folks have been doing exceptional open-weight model work for years now, and in general @nvidia has been a major supporter of many key open source efforts that all frontier labs have benefited from (directly or indirectly)

Yang Chen retweeted
For my first post, I’m sharing a letter @NVIDIA signed on why open models matter.
AI will transform every industry, power every company, and be built by every country.
Open models strengthen safety and cybersecurity, accelerate innovation and diffusion, and enable sovereignty.
The world needs both frontier closed models and frontier open models.
images.nvidia.com/pdf/Open-W…


Yang Chen retweeted

NVIDIA Nemotron just dropped an audio-native model that hears the world, not just words 🔥
transcription, translation, sound recognition & audio Q&A, TTS and full speech-to-speech, hears, thinks, and talks back natively
open weights, 2B and 30B
▶️ hf.co/spaces/nvidia/Nemotron…
Yang Chen retweeted
💡LLM agents should do more than rewrite prompts—they should actively search for and organize useful multimodal context to support the generator.
Introducing SearchGen, which co-trains an LLM agent and a generator to expand the knowledge boundary of image generation.
Try our Live Demo: tinyurl.com/searchgendemo
Search a frozen 1M Web corpus; no live API needed.
Read our project blog: haozheh3.github.io/SearchGen…
(1/N)
📢Excited to share a best-in-class end-to-end audio LLM that listen and speak with no loss in reasoning capability.
Building on Nemotron-Cascade-2, Audex tackles the core challenge that has bottlenecked audio model intelligence.
Check more details below!

🚀 Introducing Audex, a unified audio-text LLM for text, speech, sound, and music 🚀
🏆 Audex delivers best-in-class performance among open models across:
🎧 Audio understanding
🗣️ Speech recognition and translation
🔊 Text-to-speech
🎵 General audio generation
🔄 Speech-to-speech generation
🥇 Audex also achieves best-in-class results in math and code reasoning, alignment, and instruction following, even outperforming the text-only Qwen3.5-35B-A3B.
🧩 Minimalist architecture: a single 30B-A3B MoE model. Audio inputs are projected into the text embedding space, while text tokens and quantized audio output tokens are treated uniformly during generation.
🧠 Strong text intelligence, preserved
• Built on the Nemotron-Cascade-2-30B-A3B text backbone
• Trained with multi-stage SFT on blended audio-text data, Cascade RL, and multi-domain on-policy distillation
• The result: broad and SOTA audio capabilities with no regression in text intelligence.
🤗 Model:
👉 huggingface.co/nvidia/Nemotr…
📄 Technical report:
👉 arxiv.org/pdf/2607.05196

Yang Chen retweeted

🚀 Introducing Audex, a unified audio-text LLM for text, speech, sound, and music 🚀
🏆 Audex delivers best-in-class performance among open models across:
🎧 Audio understanding
🗣️ Speech recognition and translation
🔊 Text-to-speech
🎵 General audio generation
🔄 Speech-to-speech generation
🥇 Audex also achieves best-in-class results in math and code reasoning, alignment, and instruction following, even outperforming the text-only Qwen3.5-35B-A3B.
🧩 Minimalist architecture: a single 30B-A3B MoE model. Audio inputs are projected into the text embedding space, while text tokens and quantized audio output tokens are treated uniformly during generation.
🧠 Strong text intelligence, preserved
• Built on the Nemotron-Cascade-2-30B-A3B text backbone
• Trained with multi-stage SFT on blended audio-text data, Cascade RL, and multi-domain on-policy distillation
• The result: broad and SOTA audio capabilities with no regression in text intelligence.
🤗 Model:
👉 huggingface.co/nvidia/Nemotr…
📄 Technical report:
👉 arxiv.org/pdf/2607.05196
Yang Chen retweeted
Huge congratulations to the @SpaceX team on a historic IPO debut.
Fueling the next frontier of space and AI. 🌌
NVIDIA's partnership with SpaceX spans nearly a decade, from hand-delivering the world's first #NVIDIADGX-1 supercomputer in 2016 to the custom DGX Spark handoff at Starbase. Together, we've been pushing the boundaries of accelerated computing to help power the future of space exploration.
Yang Chen retweeted

The Jensen Huang Buff is real!🤩
T1 BASE CAMP 홍대점에 깜짝 방문을 해주신 NVIDIA의 젠슨황 CEO님과 T1 LoL 선수단의 만남이 성사되었습니다!
오늘의 만남을 원동력으로, 다가오는 경기에서 완벽한 경기력을 보여드리도록 하겠습니다.
The T1 LoL team was able to meet with NVIDIA’s CEO Jensen Huang during his surprise visit to T1 BASE CAMP Hongdae to celebrate @RiotGames coming to @NVIDIARTXSpark .
Fueled by this amazing energy, we’ll bring our best to the upcoming matches!
@NVIDIAGeForce #TogetherAs1


Yang Chen retweeted

We are releasing Nemotron 3 Ultra, the largest of the Nemotron 3 series with 550 billion total and 55 billion active parameters. It achieves frontier level accuracies while being much faster than the competitive models.
For more details: research.nvidia.com/labs/nem…
Check it out!


Yang Chen retweeted

The world’s first @nvidia Vera Rubin NVL72 server rack is here.
We’re thrilled to deliver the first working, liquid-cooled @Dell PowerEdge XE9812 for @CoreWeave.
Built for the next era of AI infrastructure. 🚀🤝


