
Research @GoogleDeepMind | Prev: PhD @mldcmu, AI resident @GoogleAI, BS @Berkeley_EECS. Trying to understand stuff.
Joined December 2015
- Tweets410
- Following664
- Followers2.7K
- Likes2.8K


Pinned Tweet
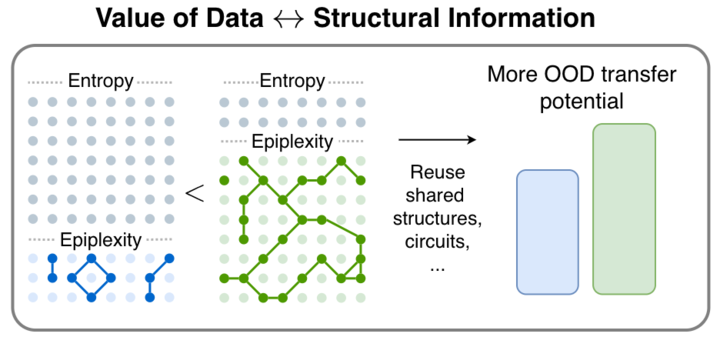
Information theory often gives unintuitive conclusions when it comes to data. Many of these inconsistencies can be resolved elegantly if we limit the amount of computation the observers can use. Very happy to finally introduce our work on epiplexity! 1/🧵

1/🧵 We are very excited to release our new paper! From Entropy to Epiplexity: Rethinking Information for Computationally Bounded Intelligence
arxiv.org/abs/2601.03220
with amazing team @ShikaiQiu @yidingjiang @Pavel_Izmailov @zicokolter @andrewgwils
This kind of result would be unimaginable one year ago. Congrats to the team!

We formally announced Mirendil less than 4 months ago. Today, I'm excited to share an important milestone for:
Pretraining at scale without a pretraining team.
Mirendil's mission is to solve Recursive Self-Improvement (RSI) and use it to democratize frontier AI development, ultimately accelerating science and technology. At Mirendil, when we think about RSI, we think holistically about the company as an intelligent entity that self-improves toward its goal. From that perspective, the most powerful notion of acceleration is reducing the time and resources (number of human experts, compute, and other costs) needed to achieve ambitious goals.
Given that pretraining is perhaps the most important yet most challenging part of frontier AI development, we decided to run an ambitious controlled experiment: Starting fully from scratch, can we significantly reduce the time, number of human experts, and compute resources needed to go all the way to successfully pretraining a strong coding model at scale?
Mirendil-Base is the result of this experiment. Our first pretrained model was built by one researcher in 3.5 months, with less than $10M in compute. This includes all the research and small-scale experiments it took to get there, as well as the final training run.
The recipe holds up as the models get bigger. For reference, Mirendil-Base is in the 100B-500B parameter range, Mirendil-Base-Large in the 500B-2T range, and Mirendil-Base-XL in the 2T-10T range.
We're beginning to see a world where a single researcher, empowered by AI, can take on work that once required an entire research organization. As these systems improve, the bottleneck shifts from the size of a team to the ambition and judgment of the people directing them. This has profound implications for who gets to build AI and, ultimately, who gets to push the frontiers of science and technology forward.
We’ll share independent evaluations, post-training benchmarks and API-access sooner than you think so stay tuned!

Yiding Jiang retweeted

1/ RL for improving task success has made LLMs remarkably capable. But what happens when the model fails? Turns out, training for graceful failure can be surprisingly tricky!
Very excited to share our new paper: Training Language Models to Fail Gracefully
🧵
This (model) is a monster.

Lots of discussion out there about our next model(!), so I wanted to give an early look as soon as possible. Introducing Gemini 4 Argon!
It shows frontier performance in complex workflows, cyber defense and software engineering. Teams are using it extensively at Google, from coding to quantum computing, great feedback.
Here’s a look at the benchmarks:



Yiding Jiang retweeted

In our Nature paper, we introduce the first superhuman Stratego AI, which we built using general techniques that we developed for RL & test-time compute under imperfect information. 1/N

Yiding Jiang retweeted

Is RL optimizing the right objective? 🤔
Should we maximize mean reward? Best-of-k? Which k?
Standard RL pulls on the mean and often the distribution collapses to a spike. The tail dies 🥲
We introduce Tail-Likelihood Reinforcement Learning (TailRL).
It maximizes the mean reward while simultaneously maximizing coverage over high reward outputs.
🧵 1/n
Yiding Jiang retweeted

Introducing Gemini 3.8 Flash, another jump in Gemini's agentic + coding capabilities, and our 3rd updated Flash model in only 6 weeks...
This model has been a ton of fun to work with, excited to see what you all think!


Yiding Jiang retweeted

Continuous self-improvement needs an ever-expanding supply of training environments (goals).
SPADE: one model self-plays the Environment Designer and the Reasoning Agent, writing executable, agentic environments that get harder as it improves. Environment scaling on its own. ♠️
Yiding Jiang retweeted
Introducing Gemini 3.7 Flash : )
- it is fast!
- 50% lower price than 3.6 flash (through end of year)
- strong intelligence increase in only ~3 weeks (thanks to some awesome algorithmic improvements)
- available in the API, AI Studio, Antigravity, and more!


Heading to Seoul for ICML ✈️ Haven’t made any particular plans but looking forward to meeting new and old friends. If anyone wants to chat about generalization, RL/exploration, epiplexity or anything else, please DM or email!
My coauthors will also be giving an talk on MaxRL 👇

Are we done with new RL algorithms? Turns out we might have been optimizing the wrong objective.
Introducing MaxRL, a framework to bring maximum likelihood optimization to RL settings.
Paper + code + project website: zanette-labs.github.io/MaxRL…
🧵 1/n
Behnam is one of the first people I worked with when I started doing research. I learned how to be a rigorous scientist and an ambitious researcher from him.
Can’t wait to see what they will do at Mirendil. Congrats Behnam!
Today, I’m excited to formally announce @mirendil with my amazing co-founders Harsh Mehta, Shayan Salehian, and Tara Rezaei!
We’re fortunate to work with @a16z and @kleinerperkins, who led our seed round of $200M, followed by a major investment from NVIDIA, among others.
Mirendil exists to accelerate science and technology, and through them, to help solve humanity's most pressing problems.
Self-accelerating AI R&D is the most direct path to delivering on AI's broader promise, which is why we believe the most important application of AI is AI itself. Get this loop right, and it compounds. It fundamentally changes the rate of progress itself across all domains.
We believe this capability should be democratized. It should be used to power all scientific efforts trying to innovate at the frontier. There are far more important problems—and broader ones—than any single lab can take on, so more groups should be able to pursue them.
This pulls concentration of power away from a few labs: businesses and science labs can own their AI and infrastructure, keep their margins, and control their own destiny instead of ceding it all to a single AI lab.
We’re a small team with a singular focus. Our founding team consists of 20 researchers and engineers from frontier institutions including Anthropic, xAI, Google DeepMind, and OpenAI, united by a passion for science and a drive to build the technologies that move it faster. If you want to build the system that builds systems, join us!
@HarshMeh1a, @shayan_, @tararezaeikh

Yiding Jiang retweeted

Gemini 3.1 Pro is here.
We’ve significantly improved the model’s overall intelligence so it can solve tougher problems. 🧵
Yiding Jiang retweeted
We’ve upgraded our specialized reasoning mode Gemini 3 Deep Think to help solve modern science, research, and engineering challenges – pushing the frontier of intelligence. 🧠
Watch how the Wang Lab at Duke University is using it to design new semiconductor materials. 🧵
Yiding Jiang retweeted

Are we done with new RL algorithms? Turns out we might have been optimizing the wrong objective.
Introducing MaxRL, a framework to bring maximum likelihood optimization to RL settings.
Paper + code + project website: zanette-labs.github.io/MaxRL…
🧵 1/n
Yiding Jiang retweeted

Epiplexity, Reasoning & The "Alien" Behavior of LLMs:
my conversation with @Pavel_Izmailov, AI researcher at @AnthropicAI and professor at @nyuniversity.
00:00 - Intro
00:53 - Alien survival instincts: is continual learning about to create a major alignment problem? Riffing on the post by @iruletheworldmo
03:33 - Did AI learn deception from sci-fi literature?
05:55 - Defining Alignment, Superalignment & OpenAI teams
08:12 - Pavel’s journey: From Russian math to OpenAI Superalignment
10:46 - Culture check: OpenAI vs. Anthropic vs. Academia
11:54 - Why move to NYU? Academia and the need for exploratory research
13:09 - Does reasoning make AI alignment harder or easier?
14:22 - Sandbagging: When models pretend to be dumb
16:19 - Scalable Oversight: Using AI to supervise AI
18:04 - Weak-to-Strong Generalization
22:43 - Mechanistic Interpretability: Inside the black box
25:08 - The reasoning explosion
27:07 - Are Transformers enough or do we need a new paradigm?
28:29 - RL vs. Test-Time Compute: What’s actually driving progress?
30:10 - Long-horizon tasks: Agents running for hours
31:49 - Epiplexity: A new theory of data information content - Pavel's work with @m_finzi, @zicokolter, @andrewgwils, @yidingjiang and Shikai Qiu.
38:29 - 2026 Predictions: Multi-agent systems & reasoning limits
39:28 - AI & Scientific progress
41:42 - Advice for PhD students
Yiding Jiang retweeted

1/ We found that deep sequence models memorize atomic facts "geometrically" -- not as an associative lookup table as often imagined.
This opens up practical questions on reasoning/memory/discovery, and also poses a theoretical "memorization puzzle."
Yiding Jiang retweeted

I think this is an important fundamental paper.
«information can be created with computation»
«likelihood modeling can produce more complex programs than present in the data generating process itself.»
A butterfly *can* be born of a worm, doomslide.


1/🧵 We are very excited to release our new paper! From Entropy to Epiplexity: Rethinking Information for Computationally Bounded Intelligence
arxiv.org/abs/2601.03220
with amazing team @ShikaiQiu @yidingjiang @Pavel_Izmailov @zicokolter @andrewgwils
Yiding Jiang retweeted

We introduce epiplexity, a new measure of information that provides a foundation for how to select, generate, or transform data for learning systems. We have been working on this for almost 2 years, and I cannot contain my excitement! 1/7
1/🧵 We are very excited to release our new paper! From Entropy to Epiplexity: Rethinking Information for Computationally Bounded Intelligence
arxiv.org/abs/2601.03220
with amazing team @ShikaiQiu @yidingjiang @Pavel_Izmailov @zicokolter @andrewgwils
Yiding Jiang retweeted

Very excited to finally release this work. Conceptually, we study how information appears different to an observer depending on how much compute they have, with connections to synthetic data, generalization and scaling laws.
1/🧵 We are very excited to release our new paper! From Entropy to Epiplexity: Rethinking Information for Computationally Bounded Intelligence
arxiv.org/abs/2601.03220
with amazing team @ShikaiQiu @yidingjiang @Pavel_Izmailov @zicokolter @andrewgwils