
Pinned Tweet
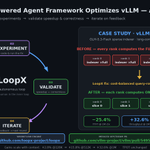
I built agent-driven framework with LoopX as workflow engine to automatically optimize inference performance on vLLM. As a case, automatically discovered sequence parallelism for sparse indexer in GLM-5.3-Flash, resulting in 32.6% throughput increase under 1M long context length.


Workflow Engine:
github.com/loopx-project/loo…
Optimization PR:
github.com/vllm-project/vllm…
113
Through continuous iteration, the agent discovered an efficient sequence-parallel implementation for sparse indexer; this boosted inference throughput of GLM-5.3-Flash by 32.6% at a 1M-token context length, and the method is applicable to other models utilizing sparse attention.
3
588