

I build AI-ready documentation systems for developer tools companies open source contributor @0xIntuition @TheOdinProject @MezoNetwork
Joined July 2023
- Tweets9K
- Following743
- Followers520
- Likes16.1K


Pinned Tweet
I recently had an article published on the @hackmamba blog about a documentation problem I found while examining three documentation sites.
I wrote the article to explain what I found and help documentation teams avoid similar issues when preparing their docs for AI systems.

Lovely read.
I recommend.

some gold by @threepointone
sunilpai.dev/posts/collectin…

I used tools like Vim for years without knowing what a TUI was.
My mental model was simple: terminal = CLI, graphical elements = GUI.
Discovering TUI challenged that assumption, so I researched the difference and wrote about it.
0xdezman.cv/blog/tui-vs-cli/

0xDezman retweeted
checkout my website:
0xdezman.cv


Nice

Four payment gateways are now integrated into @StackAPI : @theflutterwave @paystack @bachs_hq, and Stripe
Meaning, if you use @StackAPI, you can switch to any one of your choice.
One registration and one KYC give you access to all.
We also have other APIs for KYC, KYB, Emails, SMS, Utility...
Anticipate.
0xDezman retweeted

I’ll give you first access to insane tech and pay you to share your experience whether good or bad with full disclosure
We work with frontier model and tech companies that want to scale early access and growth programs
Comment ‘access’ and I’ll DM you an invite. Adding just 50 more to the next cohort
0xDezman retweeted
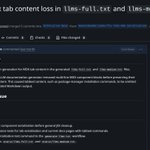
A few months ago, I found content loss in tab components across three documentation sites. I wrote about how teams can prevent it and opened a PR to fix it in @0xIntuition's docs.
And the good news? The PR is now merged.
My 4th merged PR in the repository.
#OpenSource


Started digging into agent-first documentation recently, inspired by Dachary Carey's work on agent-first documentation research, and that resulted in 3 merged PRs.
I was going through Intuition's docs @0xIntuition with my AI agent, to investigate how AI agents actually read documentation. At one point it started explaining staking, and kept referencing ETH.
That stopped me. I knew Intuition had migrated their staking infrastructure off Base onto their own new Intuition Network, and the staking token moved from ETH to TRUST along with it. So either I was missing something, or the docs were.
It was actually the docs. Several pages simply hadn't been updated after the migration. My AI agent wasn't wrong to say ETH, it was just reading exactly what was written.
A human with outside context catches that mismatch. While an agent reading the docs takes what's written as ground truth.
I verified it against the live product and the actual deposit contract, then opened a PR. Fixed a couple of smaller things along the way too.
Thanks to the Intuition team for the welcoming review.
I believe documentation needs attention more than ever, and AI agents need to be treated for what they are: a tool whose entire context is what's written in the docs.
(PR links in the comments section)

That is 2 different races right?
6 races already.
2nd from fastest race VS the other 4 from the fastest person group.
3rd VS the same 4.
Or am I missing something?


A few months ago, I found content loss in tab components across three documentation sites. I wrote about how teams can prevent it and opened a PR to fix it in @0xIntuition's docs.
And the good news? The PR is now merged.
My 4th merged PR in the repository.
#OpenSource
Started digging into agent-first documentation recently, inspired by Dachary Carey's work on agent-first documentation research, and that resulted in 3 merged PRs.
I was going through Intuition's docs @0xIntuition with my AI agent, to investigate how AI agents actually read documentation. At one point it started explaining staking, and kept referencing ETH.
That stopped me. I knew Intuition had migrated their staking infrastructure off Base onto their own new Intuition Network, and the staking token moved from ETH to TRUST along with it. So either I was missing something, or the docs were.
It was actually the docs. Several pages simply hadn't been updated after the migration. My AI agent wasn't wrong to say ETH, it was just reading exactly what was written.
A human with outside context catches that mismatch. While an agent reading the docs takes what's written as ground truth.
I verified it against the live product and the actual deposit contract, then opened a PR. Fixed a couple of smaller things along the way too.
Thanks to the Intuition team for the welcoming review.
I believe documentation needs attention more than ever, and AI agents need to be treated for what they are: a tool whose entire context is what's written in the docs.
(PR links in the comments section)
0xDezman retweeted

Shipped to Thally in the last 2 weeks:
🌐 Import docs from a URL
🤖 Built-in WebMCP
🧪 Refreshed API playground
✍️ Support for custom writing style guides
⚡ One-click docs generation
🎟️ 50,000 monthly Cloud AI credits
🔐 Password protected docs & revocable agent tokens
🛡️ Password-protected deploy previews
🔑 Refreshed sign-in & password recovery for social accounts
📦 Leaner starter & more reliable framework updates
🔎 Updated MCP server with section search & API tools

Big upgrade to Thally’s migration engine 🚀
Previously, migrating your docs required the source GitHub repo. Now, just paste your public docs URL and let Thally handle the migration.
Moving your docs just got a lot easier.
thally.io/blog/migrating-doc…

0xDezman retweeted

small tl;dr on deep research APIs coz everyone building agents should know this
search api = gives u links + snippets. ur agent does the rest.
deep research api = plans the research, searches in multiple rounds, reads full pages, cross-references sources, and gives u a cited report.
2 types:
model-native = openai, gemini. the same provider handles planning + search + writing.
web infra = octen, exa, tavily, firecrawl, parallel, perplexity. research capabilities u can plug into ur own agent stack, with varying levels of model flexibility.
some jargon u should know:
SERP snippet = the 2-line preview google shows u. useful for discovery, but rarely enough for an agent to reason deeply.
fan-out = firing 20-50 searches in parallel to explore different angles of a question.
field-level citations = every value in ur JSON output has its own source, not just a citation dumped at the end.
plan review = the agent shows u its research plan before executing it, so u can inspect or modify the direction.
if you are building/learning research-heavy agents, give this article a read, it covers the major deep research APIs and their key capabilities 🫡
octen.ai/versus/best-deep-re…


0xDezman retweeted

if you’re a student in a southwestern university, you should participate in this hackathon I’m organizing.
If you know anyone there, please retweet or share with them as well.
More details:
hackathon.busha.io


