AlphaMFPEFM (@AlphaMFPEFM) profile picture

Software developer

Paris
Joined January 2012
Photo by AlphaMFPEFM (@AlphaMFPEFM)Photo by AlphaMFPEFM (@AlphaMFPEFM)Photo by AlphaMFPEFM (@AlphaMFPEFM)Photo by AlphaMFPEFM (@AlphaMFPEFM)Photo by AlphaMFPEFM (@AlphaMFPEFM)Photo by AlphaMFPEFM (@AlphaMFPEFM)Photo by AlphaMFPEFM (@AlphaMFPEFM)Photo by AlphaMFPEFM (@AlphaMFPEFM)Photo by AlphaMFPEFM (@AlphaMFPEFM)Photo by AlphaMFPEFM (@AlphaMFPEFM)
Replying to @aidan_mclau
2026 evals can it beat Elon Musk at Diablo IV
2
24
3,405
AlphaMFPEFM retweeted
Team is locked in, upgrade your desktop app. Faster, simpler and a lot more pleasant to use.
NEW: - ChatGPT Space for Plus! - new, simpler visual design across the app - huge performance improvements everywhere - completely rebuilt threads– better perf and design - redesigned Space home - much faster pages and slides - edit pages on mobile - more reliable Codex Remote much more to come soon!
219
24
7
1,257
100,384
RT @ArtificialAnlys: Introducing AA-Millennium: seven problems, one human solution since 2000, and only two labs have scored above zero ➤…
AlphaMFPEFM retweeted
Oh my god: Anthropic mathematician Levent Alpöge (@__alpoge__) says he has proven the Riemann Hypothesis, open for 167 years. "I believe I have, working with Claude, discovered a proof of the Riemann Hypothesis." He says the method also covers the Generalized Riemann Hypothesis. The proof is out as Lean code (a proof language where a computer checks every step), so experts should be able to check it quickly, Scientific American reports. Same Alpöge who was behind this year's Jacobian conjecture result and the Navier-Stokes work with Tristan Buckmaster. I assume we will get an official statement very soon from him!!
229
528
221
5,698
531,294
AlphaMFPEFM retweeted
🚨 GEMINI NEON HITS NUMBER ONE ON LIVEBENCH Yes, it beats Fable and Astra as well!! Available today on ChatLLM... BEST MODEL EVER Details coming
59
48
6
1,087
46,136
AlphaMFPEFM retweeted
$ANT might be the biggest IPO in history with the smallest moat. If you use Apple, the ecosystem keeps you locked in. If you use Nvidia, CUDA keeps you locked in. If you use AI, the moment a better or cheaper model drops, you cancel your subscription and switch overnight. It has the lowest user loyalty of any industry out there.
91
64
11
1,090
59,297
Not every workflow requires an immediate response. For single- or multi-turn workflows that can wait, save up to 40% per token than Standard on GPT-6.2 Astra or GPT-6.2 Sol. In Responses API background mode, choose a 2h or 8h target for the first response. These discounted windows are now in public beta.
206
127
133
2,947
263,099
Build your own custom index in the Artificial Analysis Data Playground Add any Artificial Analysis benchmarks, customize their weights, and plot the results with other chart axis. Models receive a score only if they have results for every evaluation in your index, consistent with the Intelligence Index methodology. Also in the Data Playground: ➤ Formula metrics: combine any metrics with +, -, *, / and functions such as log and sqrt ➤ Playback: play a scatter chart forward by launch date, with the frontier drawn as it stood at each date ➤ Heat maps across many evaluations, and box plot distributions by group, such as open weights vs proprietary ➤ A workbench with sheets, Columns/Rows shelves and a dashboard view The Data Playground is available with Artificial Analysis Pro.
17
5
3
67
12,718
AlphaMFPEFM retweeted
I thought I'd take Ashish's image and add the prices in. What it shows to me: • How expensive Hydrogen is in its category (it's more of a mid-tier model) • How expensive Sonnet is in comparison to Terra, or how cheap Terra is compared to Sonnet • Argon and Carbon are identical prices, so really you need to pick the model based on what they're good at. Also, Logan confirms that Carbon is the next iteration of Argon anyway. And of course, this doesn't show just how many tokens the models use and how quickly they get to the results.
🤖 Made with AI
5
4
1
16
1,555
Introducing Model Factory. Train, deploy, and continuously improve your own models on one stack. Run on-demand, on dedicated clusters, or bring your own. Own your intelligence. Own your model factory.
76
220
88
2,214
232,903
AlphaMFPEFM retweeted
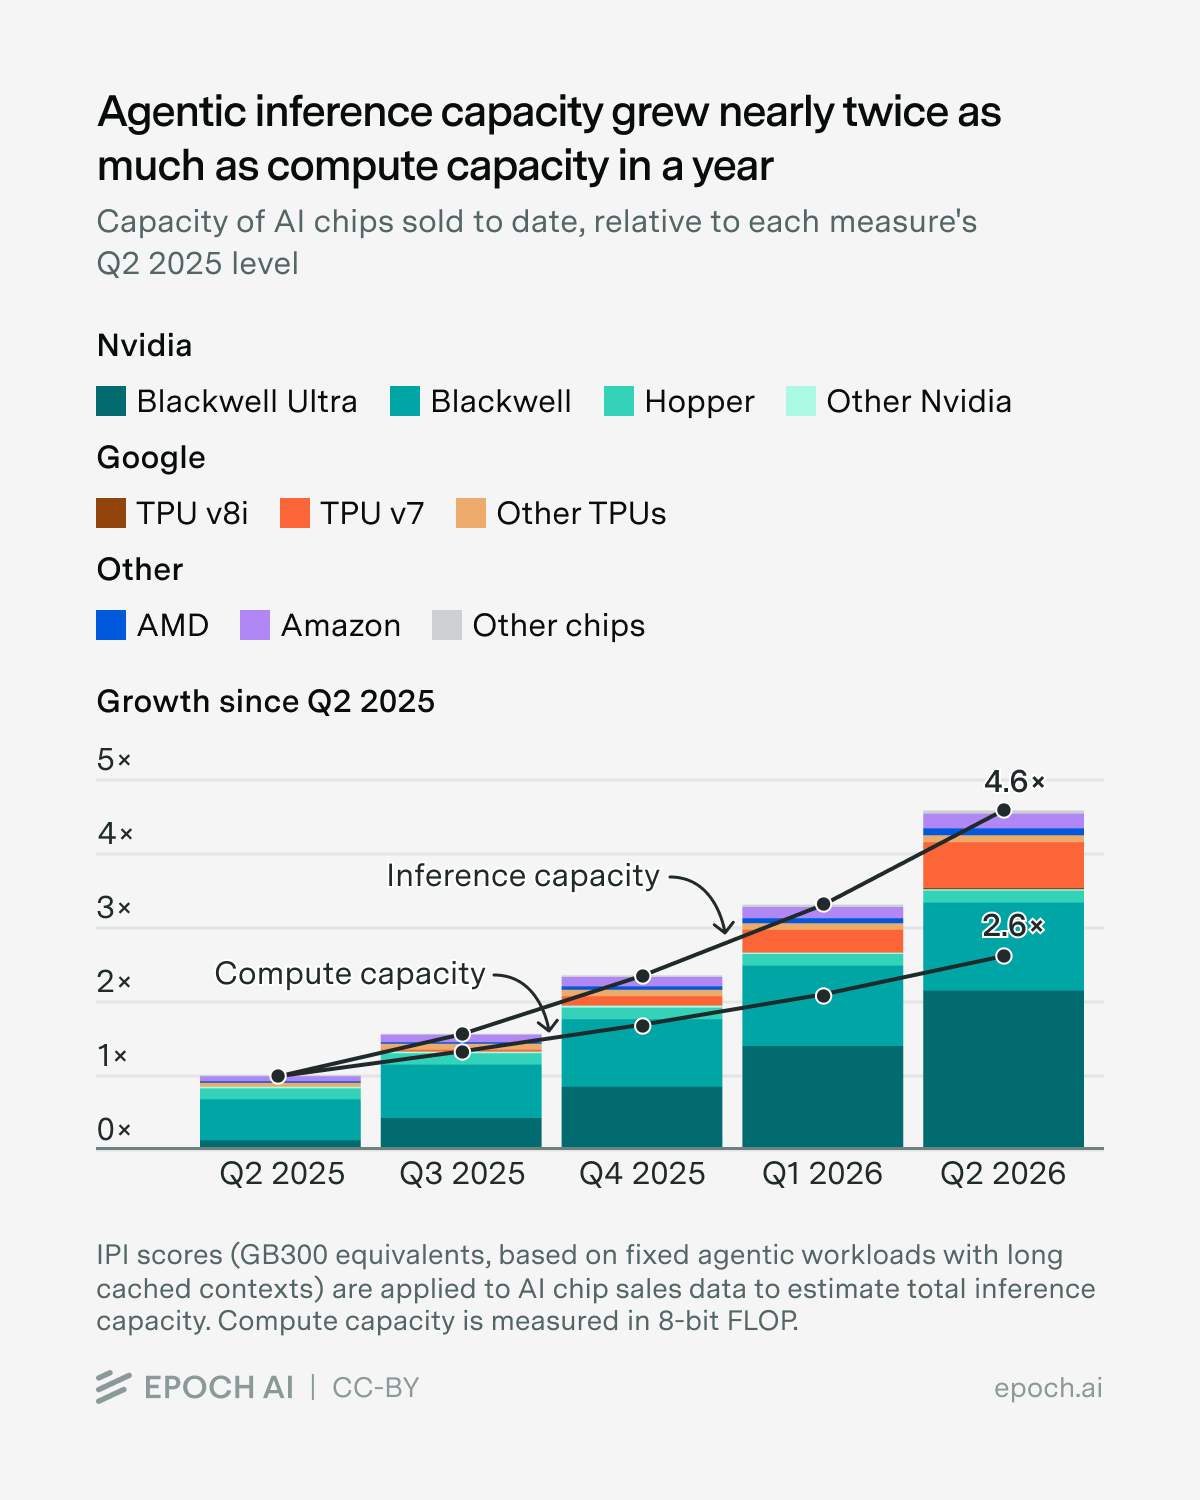
Agentic inference capacity grew 4.6× from Q2 2025 to Q2 2026. This compares with just 2.6× growth in compute, according to our Inference Performance Index (IPI). Nvidia’s Blackwell generations accounted for 74% of the added inference capacity, reflecting both growing sales and higher inference performance per GPU. This shows that FLOP/s alone understate how quickly the capacity to run AI models is growing.
We estimate that FLOP/s alone understates GB300’s inference advantage over H100 by 10×. The standard AI chip comparison misses most of what matters for inference. We’re introducing the Inference Performance Index (IPI), a new measure that accounts for memory bandwidth and inter-chip communication alongside compute. These factors determine how many users or agents a chip can support simultaneously at a given output speed. Scores in GB300 equivalents let you compare chips directly and estimate the total inference capacity of a data center, or even the world.
12
40
3
223
20,041
AlphaMFPEFM retweeted
We estimate that FLOP/s alone understates GB300’s inference advantage over H100 by 10×. The standard AI chip comparison misses most of what matters for inference. We’re introducing the Inference Performance Index (IPI), a new measure that accounts for memory bandwidth and inter-chip communication alongside compute. These factors determine how many users or agents a chip can support simultaneously at a given output speed. Scores in GB300 equivalents let you compare chips directly and estimate the total inference capacity of a data center, or even the world.
19
38
9
393
34,473
AlphaMFPEFM retweeted
I think a lot of people aren't using Grok Bot to its full potential, because knowing how to automate things is actually quite a difficult skill to learn. I wrote this post to break down how I approach automating anything with Grok Bot!
1,206
1,850
540
17,160
2,771,690
AlphaMFPEFM retweeted
GPT-6.2 Astra is an incredibly capable model. Sadly, that's not enough anymore. I did my best to show the good, bad and ugly parts of Astra in this video.
84
21
8
852
313,521
AlphaMFPEFM retweeted
Google cooked. I tested Gemini 4 Neon on real work. 2 repos, 105 replanted bugs. Find and fix what you can. It's the new #1. The results: - Gemini 4 Neon (xhigh): 63 - GPT-6.2 Astra (max): 62.7 - GPT-6.2 Astra (xhigh): 60.2 - Fable 5.2 (max): 58 - Gemini 4 Carbon (high): 57.3 - Gemini 4 Neon (high): 57 - Gemini 4 Carbon (medium): 56 More effort levels for Neon (medium, low) are dropping in the thread soon 🧵
165
137
57
1,816
130,386
AlphaMFPEFM retweeted
🏆 AND WE HAVE A WINNER! GPT-6.2 Astra defeats Claude Fable 5.2 ♟️ Final Stats: 71 moves | 204,219 tokens | $2.0671 Token & Cost Breakdown: • GPT-6.2 Astra: 70,203 tokens | $0.6052 • Claude Fable 5.2: 134,016 tokens | $1.4619 Astra takes the win using almost half the tokens and costing significantly less. GG! ♟️
Ladies and gentlemen, place your bets! GPT-6.2 Astra vs Claude Fable 5.2 Who's winning this one? ♟️ 🏆 Results at 9 PM IST.
63
66
11
892
70,694
68 % des Français voient l'IA comme une menace pour l'emploi. 80 % trouvent que les politiques n'en parlent pas assez. Mais seuls 14 % en font une priorité pour la présidentielle. Leurs priorités : le pouvoir d'achat et les retraites. Exactement ce que l'IA va toucher. Cherchez l'erreur. Nos retraites sont payées par des cotisations sur le travail. Moins d'emplois et moins de salaires, c'est moins de cotisations : une baisse de 6 % des salaires versés dans le privé pourrait coûter 18 à 20 milliards d'euros par an, selon l'économiste Axelle Arquié. Ce calcul est cité dans un avis de l'Assemblée nationale depuis le 14 octobre. Et pendant ce temps, voilà ce que nos politiques disent de l'IA. - Édouard Philippe : « 100 000 ingénieurs formés chaque année. » - Bruno Retailleau : « Avec l'IA, on peut économiser 300 000 postes. » - Raphaël Glucksmann : « Tout ce qui relève de la pure bureaucratie peut être désormais assumé par l'intelligence artificielle. » - Marine Le Pen : les robots doivent remplacer « les travaux pénibles, pas les travailleurs ». - Anne Le Hénanff, ministre chargée de l'IA, au Sénat : « Nous pensons aujourd'hui que le solde d'emplois permis par l'IA sera positif. » - Jean-Luc Mélenchon : faire cotiser les revenus du capital. - David Lisnard : ne pas taxer les machines. Sur ce que l'IA va coûter à nos retraites : pas un chiffre. C'est nul, nul, nul 😴 Ce lien entre l'IA et nos retraites, les gens ne le voient pas, parce que les politiques ne font pas leur travail. Ça fait deux jours que je fouille, et moi, je trouve les infos. Pour moi, on va droit vers la catastrophe. Je ne suis pas un politique, mais il faut un grand débat, maintenant. Et pas une taxe sur l'IA votée dans la panique. Si nos entreprises tournent surtout avec des IA américaines, c'est aux États-Unis que partent les bénéfices, pas dans nos caisses. Il nous faut des boîtes d'IA fortes en Europe, comme Mistral, et elles sont sous-financées face aux américaines. Alors c'est à nous de leur poser la question. Pas « est-ce que l'IA est importante ? », mais « qui paiera nos retraites si le travail cotise moins ? ». Sans nous, ils ne bougeront pas.
11
3
22
1,201
The personalities of GPT-6.2 Astra and GPT-6.2 Sol changed noticeably from prior releases: both use less structure, are less likely to admit uncertainty, and give shorter responses ➤ Shorter responses: 352 to 210 words per response (Astra), 337 to 223 (Sol) ➤ Less structured but more answer-first: Organization Index 70 to 11 (Astra) and 86 to 27 (Sol), while Answer First rises 49 to 89 (Astra) and 64 to 87 (Sol) ➤ Less likely to admit uncertainty: Admits Uncertainty 96 to 24 (Astra) and 98 to 51 (Sol) ➤ More natural sounding: Natural Sounding 58 to 100 (Astra) and 54 to 79 (Sol) ➤ More evidence-based at higher effort: Evidence-Based rises from low to max effort, 12 to 54 (Astra) and 16 to 68 (Sol)
64
39
23
817
65,912
AlphaMFPEFM retweeted
GPT-6.2 Astra is pretty good at hard things. Here the team shared some results on AMD and Jalapeño chip optimizations. I do get the feedback on its communication style and we're working on that, but for really the hardest tasks in the world it does seem to be in a league of its own at the moment.
Working with @AMD, our models identified up to 14% PPA improvement on flagship GPU IP in less than five months—building on designs AMD’s engineers had already spent years optimizing. The same approach helped improve Jalapeño, our first custom inference chip, with gains verified on real silicon. New evaluations also show our models getting better at certain chip design tasks. We’re sharing these results and how we’re working with @Synopsys to bring our model capabilities and their trusted EDA design and validation tools to more chip designers. openai.com/index/advancing-c…
892
144
59
4,165
608,516
Excited to launch Gemini 4 Neon: frontier-level intelligence, super fast task completion, and available to Pro & Ultra users now!! We think you’ll enjoy this model. Alchemy at its finest… 🧪
420
794
185
12,679
865,520
AlphaMFPEFM retweeted
Working with @AMD, our models identified up to 14% PPA improvement on flagship GPU IP in less than five months—building on designs AMD’s engineers had already spent years optimizing. The same approach helped improve Jalapeño, our first custom inference chip, with gains verified on real silicon. New evaluations also show our models getting better at certain chip design tasks. We’re sharing these results and how we’re working with @Synopsys to bring our model capabilities and their trusted EDA design and validation tools to more chip designers. openai.com/index/advancing-c…
460
474
316
5,136
1,311,559