



Cutting AI costs isn’t just about routing to cheaper models. Coding agents can waste tokens in plenty of other places.
Our CEO @gidim unpacks what we learned building Cost Intelligence in a @cerebral_valley deep dive.
cerebralvalley.beehiiv.com/p…

We tested #Jev against gpt-4o-mini as the judge model evaluating the same set of 1,000 application traces. Jev came out 3.5x cheaper and 3.8x faster than the LLM judge, and agreed with it on 897 of them. Here's how we set up the experiment and what we learned: comet.com/site/blog/jev-mode…

We’re excited to announce that Opik is now available within @nebiusai Cloud Applications, giving AI builders application-level agent observability and evaluation inside one of the most powerful end-to-end AI cloud platforms available today.
Learn more about using Opik within your Nebius AI stack: comet.com/site/blog/opik-neb…

What if each #ClaudeCode session contained distinct, identifiable phases, and those phases could be used to optimize usage patterns and token cost without hurting productivity? Our team explores this concept as a new feature for Comet Cost Intelligence: comet.com/site/blog/claude-c…

Traditional APM wasn’t built for LLMs. It assumes deterministic behavior and loud failures.
That’s the observability gap our Principal Engineer, Andrés Cruz, has been tackling while building Opik from the early days 🧵
Next month, Andrés will share what he’s learned in a hands-on @_odsc AI West workshop on production-grade LLM observability + evals.
🔗 Preview the session:
opendatascience.com/llm-agen…

Everyone’s racing to build agent-first UX, but what does that really look like? Our Product Design Lead goes behind the scenes on her research, decisions, and challenges she faced optimizing Opik for users and agents working in the terminal instead of the application UI: comet.com/site/blog/agent-fi…

Did you know you can iterate on multiple AI prompts in your agentic system without having to redeploy the backend every time?
Learn how the @goDigibee team versions and updates prompts in production with Opik: comet.com/site/blog/digibee-…

Comet retweeted

The agent loop is just a small part of a coding agent.
Here's where the real engineering happens:
Everything around it.
After months of dissecting coding agents like Claude Code, Codex, OpenCode, and Pi...
...I'm finally clear on what an effective coding agent architecture looks like.
Here's the blueprint:
1/ Headless harness
The harness is the system.
The agent is just one component.
Everything else lives in:
Memory
Skills
Permissions
Sandboxes
Context engineering
LSP integration
Streaming
Human-in-the-loop workflows
The LLM simply decides what to do next.
The harness makes it reliable.
2/ LLM provider
Your harness shouldn't care which model it's talking to.
That's why I abstract the provider layer.
The same harness can run against:
Self-hosted open-source models on @modal
OpenRouter
Gemini
Whether you're serving an open-source model on @modal or calling a hosted API, the harness doesn't change.
Changing models becomes a configuration change instead of an architectural rewrite.
3/ Fast feedback loops
Coding agents improve by observing the consequences of their actions.
Every iteration follows the same cycle:
Edit code.
Run tests.
Read failures.
Try again.
Sometimes you don't even need to execute the code.
An LSP can flag syntax errors immediately after an edit, making it one of the cheapest and fastest feedback mechanisms in the entire harness.
4/ 2 interfaces, 1 core
The harness has no UI.
Instead, different interfaces connect to it.
For example:
A local terminal UI for interactive coding.
A remote runtime using Kitaru (by @zenml_io) to execute many harnesses in parallel.
Same core.
Different ways to interact with it.
5/ Evals aren't optional
Changing one prompt shouldn't silently make your coding agent worse.
But just in case, every model call and tool call is traced and evaluated.
Using Opik (by @Cometml), you can:
Run benchmarks and compare runs
Catch regressions
Understand why an agent succeeded (or failed)
... before users notice.
Here's my biggest learning from building a coding agent from scratch:
The LLM is only one dependency...
The harness is what turns it into a production system.
P.S. In the latest issue of Decoding AI Magazine, I break down the complete architecture while building a production-grade coding agent from scratch in Python.
Read it here: decodingai.com/p/building-a-…


Comet retweeted

New open-source course from @pauliusztin_: building a coding agent from scratch in Python, 8 lessons.
The premise: @LangChain's Terminal-Bench showed that swapping only the harness (same model) moved a coding agent from ~30th to the top 5. So the course builds the harness.
First lesson is live and the depth is real.
🤝Sponsored by @Cometml Opik
github.com/decodingai-magazi…

Comet retweeted
Here's an AI engineering pattern I wish more AI teams adopted:
(It's stolen from traditional software engineering)
Not every code change deserves the same validation process.
For example, I once waited 3 hours for my AI eval suite to tell me my change was correct after I updated one word in my documentation.
This shouldn’t be the case.
Tweaking a prompt or fixing a small bug shouldn't require rerunning your entire evaluation suite.
But if you introduce a new capability, manual testing isn't enough.
Here's how Alejandro Aboy approaches it with Evaluation-Driven Development (EDD)...
There are two different modes:
1/ Manual quick check
For small changes:
Prompt tweaks
Tool descriptions
Bug fixes
Minor routing improvements
Generate around 30 fresh traces.
Inspect them manually.
If needed, trigger an LLM judge to score the results.
Think of it like a unit test.
2/ Automated experiments
When shipping new functionality, those fresh traces become a dataset.
The dataset becomes an experiment.
Every trace is automatically evaluated.
Then you compare today's experiment against previous ones to catch regressions since the most dangerous AI failures are the silent ones.
One more design decision stood out to me...
The evaluation difficulty should be adjustable.
Happy-path conversations.
Edge cases.
Fully adversarial interactions.
The larger the change, the harder you push the agent before shipping it.
To sum up:
Traditional software engineering doesn't treat every change the same.
Neither should AI engineering.
Small changes deserve quick validation.
Big changes deserve experiments.
Using the same evaluation process for both slows you down or leaves regressions undiscovered.
P.S. We covered Alejandro Aboy's complete EDD workflow in a recent issue of Decoding AI Magazine.
Check it out here: decodingai.com/p/how-evaluat…

🚀 Opik just hit 20,000 GitHub stars.
We knew this community was growing fast. We didn't know it was this fast.
What started as an open source experiment in LLM evaluation has turned into something we couldn't have built alone: hundreds of thousands of developers choosing Opik as their trusted platform for AI observability and evaluation.
To everyone who starred the repo, opened a PR, built something with it, or spread the word: thank you so much. We can't wait to see what you build next.
👉 github.com/comet-ml/opik
Comet retweeted
🧵 The @aiDotEngineer World's Fair schedule just dropped. 600+ sessions, 29 tracks. I'll be there next week (June 29 - July 2 in SF). Here are the 8 talks and tracks I'm planning my days around:

Comet retweeted

Andrej Karpathy:
"Remove yourself as the bottleneck. Maximize your leverage. Put in very few tokens, and a huge amount of stuff happens on your behalf."
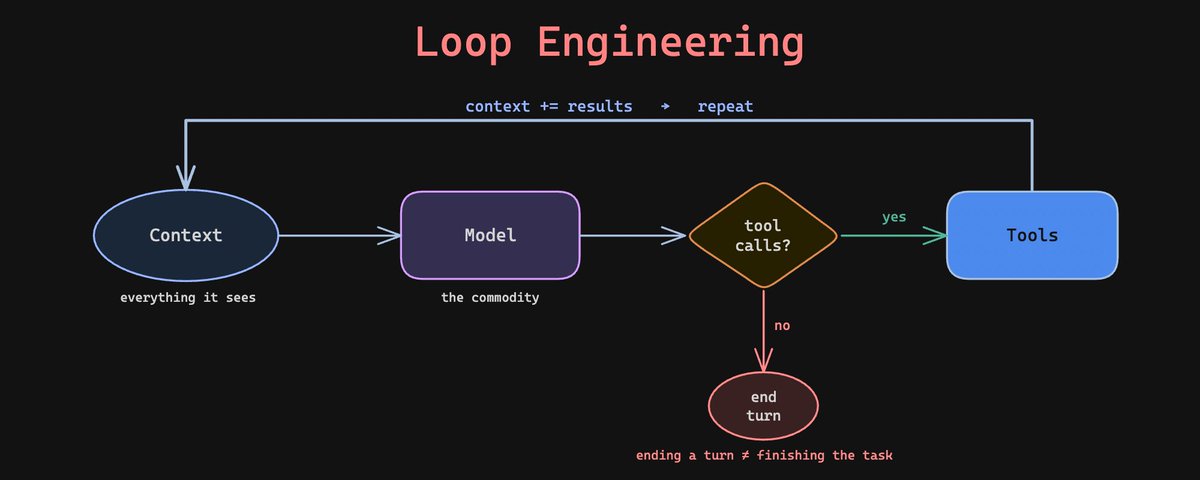
loop engineering is the exact thing that gets you there.
in a hand-run session you do two things. you decide what the agent runs next, and you check its output before the next step. both are manual, and both are the ceiling on how far the agent gets without you.
loop engineering moves both steps into the system. the diagram below shows the operating structure that surrounds the loop:
→ a trigger decides what to run, whether that's a message, an event, or a schedule, so the agent starts without you there to kick it off.
→ the loop is the maker that produces the work, thinking, acting, and observing until it's done or the brakes stop it.
→ a separate checker grades the output, because a model grading its own work justifies what it already did instead of catching where it failed. the checker's findings return to the maker as the next instruction, and the cycle repeats until nothing is left to fix.
→ state lives on disk, not in context, since the model forgets everything between runs. an MD file or a knowledge graph holds what's done and what's still open, so a loop can pick up again days later.
for that state layer, Zep's Graphiti is a clean open-source option, a temporal knowledge graph that invalidates stale facts and returns context through vector, full-text, and graph search in one call.
repo: github.com/getzep/graphiti
two things decide whether an unattended loop holds up.
the exit has to be set before the loop runs, not while it's running. a loop with no stop condition burns tokens, and the cost climbs fast once sub-agents and long runs stack up. a clean exit reads like "all tests pass and lint is clean, stop after two passes."
and the checker only catches failures inside a run. the harness around the loop, the prompts, tools, and checks wrapped around the model, still drifts and breaks in production as models change. catching that needs observability on every run, not a green checkmark.
Comet's Opik is built for that layer, an open-source tool that traces every call and turns a failing production trace into a regression test so the same break can't recur.
repo: github.com/comet-ml/opik
your job stops being the hands inside the loop. it becomes designing the machine that runs without you, then watching the traces closely enough to trust it.
the model is becoming a commodity. the loop around it is where the real engineering lives now.
I wrote the full breakdown. the article is quoted below.
stay tuned for more on this!

Did you know Opik integrates with #Openclaw? With the Opik/opik-openclaw plugin, every LLM call, tool invocation, and agent run is automatically traced and visible in your Opik dashboard. Three commands to get started: install, configure, restart.
Setup guide → comet.com/docs/opik/integrat…
Plugin repo: github.com/comet-ml/opik-ope…

We just published a public examples repo for Opik: integrations, use cases, and utility scripts you can clone and run.
Community contributions welcome.
github.com/comet-ml/opik-exa…

Comet retweeted
I used to think evals were something you added after building the AI system.
But the more AI agents I ship, the more backward that seems...
The scariest AI failures are the silent ones.
You change something and everything still runs.
But did the system get better?
Did you quietly break something that worked yesterday?
This is why I've become increasingly interested in Evaluation-Driven Development (EDD).
The idea is surprisingly simple...
Every feature starts as a hypothesis.
Before merging, you must answer two questions:
1. Did the new feature work?
2. Did I accidentally break something else?
To answer them, EDD introduces an offline validation gate between development and deployment.
The workflow looks roughly like this:
1. Generate test cases scoped to the new feature
2. Run the agent
3. Evaluate the results
4. Compare before vs after
Which looks remarkably similar to traditional software testing.
The only difference is that we're validating behavior via data rather than code.
And as agents become more complex, the more important this gets.
Because a working agent doesn't mean it's a good one.
P.S. I recently sat down with Alejandro Aboy to break down exactly how he implements EDD using Claude Code, Opik (by @Cometml), synthetic datasets, trace generation, and LLM judges.
Check it out here: decodingai.com/p/how-evaluat…
