
PhD candidate at @CSEhuji & Research Intern at @GoogleResearch
Joined December 2020
- Tweets81
- Following170
- Followers251
- Likes163





Gili Lior retweeted

Mark your calendars for ISCOL '26! 🤩
We're excited to announce that this year's ISCOL conference will take place on December 23rd at The Hebrew University.
See you soon in Jerusalem:)


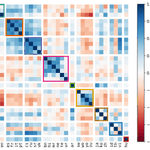
✨ Bonus: we analyze the fitted parameters themselves. The content-vs-language discriminability split captures signal raw accuracy can't — and the learned cross-lingual correlation matrix recovers known language families with no typological supervision

📄 Paper: arxiv.org/abs/2606.15643
Huge thanks to my collaborators @mataneyal1, @GabiStanovsky & Tzviel Frostig 🙏
We hope Multilingual-IRT makes multilingual evaluation cheaper, more reliable, and more insightful!

Excited to share my new paper from my internship at Google Research! 🌍
We present Multilingual-IRT, extending Item Response Theory to parallel multilingual benchmarks for cheaper and more meaningful multilingual evaluation.
Check it out! gililior.github.io/multiling…
🧵1/8

Happy to share Reef's amazing work!
We tested top reasoning models on their ability to infer how a hidden environment works by interacting with it, and got some really interesting findings.
Check out the paper for more details!

📢 New Paper
Can LLM Agents Infer World Models?
We turn a well studied automata learning task into an agent benchmark, where a hidden automaton serves as a world model that an agent must reconstruct using query tools.
Our findings show that SOTA LLM agents can sometimes perform non trivial interactive discovery, but remain far less robust and efficient than classic automata learning algorithms.
Beyond overall performance, our analysis reveals recurring failure modes in planning, reasoning, and using accumulated information over long contexts.
🔹 Think this task is easy? Try it yourself:
reefmenaged.github.io/Agenti…
🔹 Watch an LLM tackle an automaton of your choice:
agentic-automata-learning.on…
🔹 Read the paper:
arxiv.org/pdf/2606.16576
Grateful to my amazing co-authors for making this work possible: @GiliLior @ravfogel @roeeaharoni @GabiStanovsky

Gili Lior retweeted

New datasets keep coming,
New models keep coming.
Frustrating!
How can we evaluate everything on everything?
How do we keep scores comparable over time?
We propose a way to grow benchmark suites without losing comparability.
Details:👇🧵

Honored to have been part of the ISCOL 2025 panel with such great professors! @yoavgo @melhadad
It was an interesting discussion on AI’s role in academia and research, with diverse opinions and challenging perspectives.
Thanks @iscol_meeting and @ella_rabinovich for having me!


Gili Lior retweeted

🚨 New preprint!
One idea, many ways to say it – does your brain track those options before you speak?
Using LLMs, we put this to the test:
biorxiv.org/content/10.1101/…
We show for the 1st time that the brain represents many alternatives simultaneously in both listening & speaking 🧵
Excited to present our paper "ReliableEval: A Recipe for Stochastic LLM Evaluation via Method of Moments" at #EMNLP2025 🎉
Everyone knows LLMs are prompt-sensitive, yet we still report single-prompt scores.
Our work suggests a method to make evaluation statistically reliable!
Our method estimates the minimal subset size n* needed to achieve those guarantees, using the Method of Moments to estimate when it stabilizes (blue)
A reliable evaluation then reports not a single score, but the distribution of model performance across sampled prompts (pink)


Curious how to perform a reliable evaluation? Come meet me, @EliyaHabba and @ShaharLevy19 at the Findings poster session - Nov 5th, 1 PM CST
Huge thanks also to our collaborators @clu_avi and @GabiStanovsky
Paper 🔗 aclanthology.org/2025.findin…

Come meet me if you are around #EMNLP2025 and care about multi-prompt/reliable evaluation!

I can't make it to #EMNLP2025, but @EliyaHabba and @GiliLior will present our PromptSuite🌈(demo!): a framework tackling prompt sensitivity by generating benchmark variations for any task.
Try it with just a few lines of code or the web interface!
eliyahabba.github.io/PromptS…


Gili Lior retweeted
Our 🌈 PromptSuite paper has been accepted to #EMNLP2025 🇨🇳 (System Demonstrations)! 🎉
🌈 PromptSuite is a flexible framework for generating thousands of prompt variations per instance - enabling robust, task-agnostic evaluation of LLMs.
@Dahan_Noam, @GiliLior, @GabiStanovsky
