
PhD student @GeorgiaTech working on NLP | Research intern @MITIBMLab
Atlanta, GA
Joined October 2021
- Tweets93
- Following194
- Followers213
- Likes730





Junmo Kang retweeted

📣 New paper by my Ph.D. student @hyungjoochae
How can we build a safe, scalable learning environment for web agents?
Paper: arxiv.org/abs/2603.10505
We introduce VERIENV, which clones real websites into executable synthetic environments using coding agents.


Junmo Kang retweeted
🎉 Excited to see that our paper on cost-efficient data annotation for LLMs won an SAC Highlight Award!
🔗 Check out @mohit_rag18's work here: aclanthology.org/2025.acl-lo…


Check out @mohit_rag18's recent work analyzing data annotation costs associated with SFT vs. Preference Fine-Tuning.
Junmo Kang retweeted

Excited to share our paper on uncovering prompting patterns in Frontier LLMs using automated meta-analysis at @aclmeeting #ACL2025

Junmo Kang retweeted
🚨 Just Out
Can LLMs extract experimental data about themselves from scientific literature to improve understanding of their behavior?
We propose a semi-automated approach for large-scale, continuously updatable meta-analysis to uncover intriguing behaviors in frontier LLMs. 🧵

How should a fixed annotation budget be allocated between SFT and Preference-Tuning data? Check out @mohit_rag18’s awesome work exploring this!

Junmo Kang retweeted
Check out @mohit_rag18's recent work analyzing data annotation costs associated with SFT vs. Preference Fine-Tuning.
Junmo Kang retweeted

🚨Just out
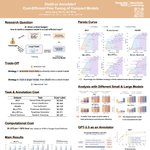
Targeted data curation for SFT and RLHF is a significant cost factor 💰for improving LLM performance during post-training.
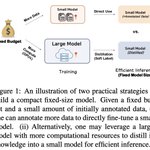
How should you allocate your data annotation budgets between SFT and Preference Data?
We ran 1000+ experiments to find out!
1/7

Junmo Kang retweeted

Ever wondered if style lexicons still play a role in the era of LLMs? 🤔
We tested 13 established and 63 novel language styles across different LLMs. 🧠✨ It turns out lexicons are still crucial for style understanding! But how can we better leverage this lexical knowledge? Our approach: meta-tuning LLMs to leverage lexical knowledge for generalizable language style understanding.
Check out our latest work at Main of #ACL2024NLP! 🚀
arxiv.org/abs/2305.14592
@mlatgt @ICatGT

Junmo Kang retweeted

Many retrieval-augmented generation (RAG) language models simply consider whether a retrieved document is "relevant" or not.
Excited to share our latest research published at #NAACL2024 Findings! 🔍📚
🎉Kudos to
@GiwonHong413849 @JunmoKang
Paper: arxiv.org/abs/2305.01579
Junmo Kang retweeted

@chrmanning at #EMNLP2023 to #NLProc PhD students, who are having an existential crisis over LLMs:
Aeronautics students do not build Boeings for their PhD theses. They do smaller models - and still make meaningful contributions. There's plenty of such opportunities for us too.


Junmo Kang retweeted

If you are interested in multimodal RAG, check out our new paper!
- We propose a unified multimodal retriever trained with instruction-tuning on 8 tasks (🖼️image/📝text query -> target)
arxiv.org/abs/2311.17136
#RAG #multimodal


Junmo Kang retweeted

Struggling to sift through endless tables and lengthy webpages for useful information?
👉Checkout our paper “Schema-Driven Information Extraction from Heterogeneous Tables” to see how LLMs are revolutionizing this process!
🔗arXiv: arxiv.org/abs/2305.14336
@ICatGT @mlatgt

Junmo Kang retweeted

Ever wondered “Am I oversharing on social media?”, and worried about privacy risks?
In our new paper, we use language models to pinpoint self-disclosures and provide diverse abstractions for users to choose from. All of these are backed and motivated by a real-world user study!

Junmo Kang retweeted

Self-specialization is crucially important for the ongoing development and progress of large language models (LLMs) for the following key reasons:
Expertise in Niche Domains
- As LLMs are applied to more specialized domains like biomedicine, law, etc., uncovering domain expertise is critical. Self-specialization provides an efficient way to carve out niche expertise from generalist LLMs.
Data Efficiency
- Acquiring expert annotations is challenging. Self-specialization only needs a handful of seeds, enabling domain specialization with minimal human involvement. This is far more practical than relying solely on manual data.
Parameter Efficiency
- Compact specialization modules can be overlaid on top of a shared base LLM, avoiding redundant parameters for each domain. This allows serving multiple expert models efficiently.
Adaptability
- The self-supervised approach inherently adapts the LLM to new domains by generating tailored data. This is more flexible than pre-defined training objectives.
Scalability
- By having LLMs self-generate data, self-specialization removes the training data bottleneck. This enables scaling to new domains easily without manual data collection.
In summary, self-specialization essentially provides a pathway to extract specialized knowledge in an adaptable, scalable, and extremely efficient manner. This will be a critical capability as we push LLMs into more and more expert domains while needing to maintain versatility and avoid exponentially growing data and parameter needs. Unlocking latent domain expertise will be key, and self-specialization offers a highly promising approach to make this feasible.

🚨Can we self-align LLMs with an expert domain like biomedicine with limited supervision?
Introducing Self-Specialization, uncovering expertise latent within LLMs to boost their utility in specialized domains.
arxiv.org/abs/2310.00160
@ICatGT @mlatgt @MIT_CSAIL @MITIBMLab
1/8

Please check out the paper for more details. This work was partly done during my internship @MITIBMLab. Huge thanks to all the collaborators! @lhyTHU, Yada Zhu, James Glass, @neurobongo, @alan_ritter, @RogerioFeris, @leokarlin.
8/8
🤗Huggingface page: huggingface.co/papers/2310.0…
The code will be released soon!
