





LLMFly is an LLM API platform for GPT, Claude, Gemini and more.
One account, one Base URL. 30–50% of provider pricing. Separate project keys, usage records, stable access, and real technical support.
Claude Code + CCSwitch setup 👇
youtu.be/_hnFKEkIdnM?si=ukBt…
2
973
LLMFly AI retweeted

LLMFly AI (@llmflyai)
"One API for leading AI models, at lower cost."
👏 Join us in celebrating this awesome launch!
fazier.com/launches/llmfly-a…

Claude Fable 5.2 is now live on llmfly.ai at a discounted price.✌️
Smarter reasoning, faster coding, and more capable agents.
- Up to 30% faster than Fable 5.1
- 1M context · 128K max output
- Prompt caching supported
Put the latest #Claude model to work with one #API and competitive pricing.
👉 Try it now: llmfly.ai

624
4/4
This changes how developers should think about API costs.
It’s not just about finding a cheaper model.
Cache-read pricing, context management, unnecessary tool calls, and model selection all matter.
The next frontier in AI development isn’t just making agents smarter.
It’s making them more economical to run.
40
3/4 Here’s the surprising part:
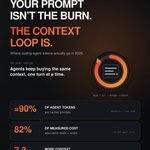
Cached input accounted for 97.4% of input token volume and 72.9% of modeled API costs in requests with reported cache usage.
Cached tokens are cheaper individually.
But when agents read hundreds of thousands of them across repeated requests, the bill adds up.
1
43
2/4 The median LLM request carried:
129K input tokens
Just 491 uncached input tokens
227 output tokens
Agents repeatedly send their growing context back to the model.
Most of it isn’t new information. It’s context being read again and again.
1
13
1/4 A new study of 12,000 real-world coding-agent sessions reveals something interesting about where API costs actually go.
Source: systems.seas.harvard.edu/blo…
1
49
Your coding agent might be spending more on remembering what it already knows than on generating new code. 🧵
🤖 Made with AI

1
1
837
Claude Code’s “5× faster drain” wasn’t one bug.
It was the stack:
xhigh + /goal + Workflows + Agent Teams + long SDK jobs.
Subagents inherit your effort setting too.
Token burn isn’t prompt length anymore. It’s context × turns × agents.
How bad is your /usage page? 👀

Thanks to everyone who shared session IDs. We went through all of them. We found a few smaller things along the way that made some sessions burn through tokens faster than they should have, and we're rolling out fixes to those right now.
We didn't find a single root cause or any regression in Claude Code. In most cases, users who saw faster usage against limits were traced back to one or two heavy sessions (xhigh effort, /goal, Workflows, Agent Teams, long SDK jobs). These are all good ways to use Claude Code, and it's on us to make it clearer when to use them and how much these features cost.
It's good idea to keep an eye on the effort level you're on. Subagents inherit it by default and it can add up fast. /usage also shows where a session's tokens went.
If something still looks off, we'd love your /feedback. We'll also follow up directly with everyone who shared an ID.
824

6 million tokens a day is table stakes now.
You there yet?
llmfly.ai/blog/2026/10/26/co…
#CodingAgents #AIAgents #LLM

733
$1,000 now buys ~4 hours of a human expert—or ~65 hours of AI agent runtime.
The new production budget is tokens. And it’s getting weird.
llmfly.ai/blog/2026/10/24/wh…
#AIAgents #BuildInPublic
1
2
760
Ideas are cheap. Iteration costs tokens.
Token budget is production budget.
llmfly.ai/blog/2026/10/22/ai…
#AIAgents #LLMAPI

2
759
LLMFly AI retweeted
6/6
There’s an interesting cost layer underneath all of this.
What are all those tokens actually costing, and does every step need the same frontier model?
More on the projects, models and token economics here ↓
llmfly.ai/blog/2026/10/15/ca…
6/6
There’s an interesting cost layer underneath all of this.
What are all those tokens actually costing, and does every step need the same frontier model?
More on the projects, models and token economics here ↓
llmfly.ai/blog/2026/10/15/ca…
5/6
@thebuggeddev built Anatomy Atelier using coding models and generated 3D assets.
@chetaslua built The Neural Museum, turning AI papers into a walkable museum.
@ChrisGPT built Ironveil Range, a playable ballistic-missile-defense simulator.
1
77
4/6
@anshuc used GPT-6 Astra to generate a playable 3D game from scratch in roughly 45 minutes.
@Dimillian has been using GPT with Blender / Unreal workflows to build explorable 3D environments.
@ashebytes built an interactive human anatomy atlas with 2,234 individual parts.
1
64