

Open-source Semantic Control Plane for long-horizon agents & agent teams (6.7k+ ★). Built by @huangruiteng. Works with Codex, Claude Code, Gemini & DeepSeek.
- Tweets44
- Following13
- Followers6
- Likes17




ALT vLLM sparse-indexer TP row sharding. The old activation floor was 16,384 prefill rows per rank: 65,536 total rows at TP4, but 131,072 at TP8. In the reported 8-H100 setup, a 65,536-token batch budget could not reach the TP8 floor; raising the budget to 131,072 caused an out-of-memory failure. Merged PR 61647 sets the default floor to 65,536 total prefill rows through AttentionConfig.indexer_tp_shard_min_rows. It counts the current prefill batch, not full prompt length. To first order, both saved indexer computation and per-rank index exchange scale with (TP minus 1) divided by TP; a total-row floor need not grow linearly with TP. The default was calibrated on H200 with NVSwitch, not every interconnect. Other backend conditions still apply. TP2 deliberately moves from 32K to 64K. This diagram explains activation thresholds and a user report; it is not a new speed benchmark. Sources: zigzagcai, vLLM PR 54951 comment r4267244007 and PR 61647 (merged Oct 15). K means 1024 rows.

ALT Fork-and-Flush schematic: copy workspace files into four branches with new chats; select by score and continue. Polyomino mean scores: single run 88.56, flush only 85.91, fork only 90.74, fork-and-flush 94.41. Credits exclude solver/training compute. Paper-reported results, arXiv2610.07447v1; not independently replicated.


ALT Contributor case by @zigzagcai, vLLM PR #54951. Reported throughput includes input and output tokens: 17,856 to 23,675 tokens/s, +32.6%; TTFT 54.15 to 40.39 seconds. Conditions: GLM-5.3-Flash, 4 H200 GPUs, tensor parallelism 4, one sequential request, 1M input tokens, 256 output tokens, 65,536 batch budget, legacy runner with FA3. Mechanism: instead of every rank repeating all sparse-indexer MQA scoring and top-k query rows during prefill, assign cost-balanced contiguous row slices. Each rank retains the full causal key history; all_gatherv reassembles final indices. Decode kernels unchanged. Diagram uses 12 illustrative rows. At TP4 the new path needs at least 65,536 scheduled prefill rows plus backend gates; 1M context with an 8,192 budget is insufficient. Targeted retrieval: answer present 132/132 in each arm. General quality and bitwise equivalence unproven. Measured commits 5893426b to 16934c6e differ from final head a9fd692d. No independent GPU rerun.


ALT Engineering diagram of LoopX periodic-report recovery from merged PR #7207 (0c0d3dd). Left: one recovery may be admitted for the exact stale_goal_authority prelaunch refusal while retaining the same native Turn, task and report window; no host start or output, no completed native phases or effects, no frozen report, and fresh authority, idle chat and native lease are required. Right: a timeout or lost transport alone, started work, unknown or conflicting history, an existing report, revoked authority, busy chat or failed recovery do not authorize automatic retry. The allowed branch resumes the original native transaction once, then report body and original-chat delivery need separate verification. This is a policy diagram, not a product screenshot. A pure source admission check does not verify installed delivery.

ALT Source-based mechanism diagram for LoopX PR #7191, merge b8b9c1d, not a product screenshot or an installed recovery demonstration. After a host restart interrupts an ordinary private project request with tool activity but no final answer: keep the original failed Turn, verify source/binding/grant and stable idle native inventory, then reserve one read-only review in the original thread. Review existing results or report a concrete verification gap; verify delivery through the original transport separately. Final answers, stop/correction intent, live work, unstable inventory, or revoked/changed source or grant block recovery. The review profile disables writes, network, MCP, Apps and delegation. Steward, attached and group requests are excluded. Observed tool activity is not proof of business success. Installed result return remains unverified.

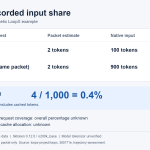
ALT Synthetic LoopX input-share example, not a product screenshot or a real research measurement. The same packet is estimated as two o200k_base tokens in request A (100 native input tokens) and request B (900). Summing per request gives four estimated packet tokens divided by 1,000 native input tokens, or 0.4%. Input includes cache. With partial request coverage, the overall percentage is unknown; packet cache allocation is unknown. Local tiktoken 0.12.0; the provider model tokenizer is unverified. Source revision 385771e.

ALT Two synthetic LoopX BM25 examples. Query 态机, document 状态机: default word analysis does not return it; explicit Han bigrams returns it via 态机. Query 状态机, document 状态检查: default word analysis does not return it; Han bigrams also returns it because only 状态 overlaps. Native calls on two synthetic documents, not a retrieval-quality benchmark. Source revision bd67d651ac.


