

OpenCompass focus on the evaluation and analysis of large language models and vision language models. github: https://xitter.cf/t.co/zF7ycuTXxs
China
Joined April 2024
- Tweets80
- Following47
- Followers283
- Likes64



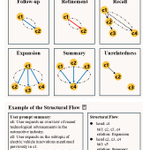
😉Introduce VideoScience-Bench, a benchmark designed to evaluate undergraduate-level scientific understanding in video models.
🥰Comprises 200 carefully curated prompts spanning 14 topics and 103 concepts in physics and chemistry.
👇
hub.opencompass.org.cn/daily…

😀A new study finds that long prompts cause a fidelity–diversity trade-off in leading T2I models: more detail but reduced diversity.
😉To evaluate this issue, the authors introduce LPD-Bench and propose PromptMoG, a training-free approach that enhances diversity by sampling prompt embeddings from a Gaussian mixture.
😉Experiments on SD3.5-Large, Flux.1-Krea-Dev, CogView4, and Qwen-Image show that PromptMoG improves long-prompt diversity without causing semantic drift.
👇
hub.opencompass.org.cn/daily…

😀SpatialSky-Bench, a comprehensive benchmark specifically designed to evaluate the spatial intelligence capabilities of VLMs in UAV navigation.
😉Two categories: Environmental Perception and Scene Understanding
😉13 subcategories, including bounding boxes, color, distance, height, and landing safety analysis, among others.
🥰SpatialSky-Bench is now part of the Daily Benchmark.
Explore more:
hub.opencompass.org.cn/daily…
#VLM #UAV #AI

🥰VP-Bench, a benchmark for assessing MLLMs' capability in VP perception and utilization.
😊Two-stage evaluation framework:
1.Examines models' ability to perceive VPs in natural scenes, using 30k visualized prompts spanning eight shapes and 355 attribute combinations.
2.Investigates the impact of VPs on downstream tasks, measuring their effectiveness in real-world problem-solving scenarios.
👏VP-Bench is now part of the Daily Benchmark.
Explore more:
hub.opencompass.org.cn/daily…😊

🥰OutSafe-Bench, the first most comprehensive content safety evaluation test suite designed for the multimodal era.
😍Covers 4 modalities:
18,000+ bilingual (ZH/EN) text prompts
4,500 images
450 audio clips
450 videos
👏OutSafe-Bench is now part of the Daily Benchmark.
👇Explore more:
hub.opencompass.org.cn/daily…

🚀 OpenCompass Daily Benchmark is live!
✅ Daily updates of the latest AI evaluation papers
✅ AI-powered smart summaries
✅ Available in English & Chinese
😍Stay ahead of AI trends, key insights, and cutting-edge research—all in one place! 🔗 hub.opencompass.org.cn/daily…


OpenCompass retweeted

🔥China’s Open-source VLMs boom—Intern-S1, MiniCPM-V-4, GLM-4.5V, Step3, OVIS
🧐Join the AI Insight Talk with @huggingface, @OpenCompassX, @ModelScope2022 and @ZhihuFrontier
🚀Tech deep-dives & breakthroughs
🚀Roundtable debates
⏰Aug 21, 5 AM PDT
📺Live: youtube.com/live/kh0WSMoVZmA

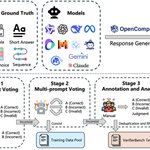
🚀 Introducing #CompassVerifier: A unified and robust answer verifier for #LLMs evaluation and #RLVR!
✨LLM progress is bottlenecked by weak evaluation, looking for an alternative to rule-based verifiers? CompassVerifier can handle multiple domains including math, science, and reasoning, as well as various answer types such as multiple-choice questions, sequences, and multiple subproblems.
🔍 Introducing #VerifierBench: A challenging dataset for evaluating the verification capabilities of different models!
🏆 Want to evaluate the verification abilities? We collected over 1 million LLMs responses using #OpenCompass framework, and selected the most challenging examples through multiple rounds of screening and manual annotation.
🏠 Main Page:
open-compass.github.io/Compa…
📄 Paper:
arxiv.org/pdf/2508.03686
💻 Code:
github.com/open-compass/Comp…
🤗 Model & Datasets:@huggingface
huggingface.co/collections/o…


