

A small farm in the mountains.
Joined February 2013
- Tweets342
- Following6K
- Followers760
- Likes6.1K




OpsConfig retweeted

We're proud to announce the launch of CS Learn, a new online learning platform that offers free access to select courses from Carnegie Mellon University’s top-ranked computer science program.
Check out the course offerings: bit.ly/4C4770z

I remember watching a chunk of a university network go down suddenly with similar traffic behavior.
At first we thought it was a denial-of-service attack.
The root cause was a student plugged one end of an ethernet cable into the wall jack and instead of plugging the other end into their laptop they accidently plugged the other end into another wall jack on the same switch creating a mini loop.
On a properly configured switch/network there is protection in place to detect the loop and shutoff the ports before they cause a problem.
However, when these features are disabled and you create a simple loop on the same switch a huge network storm ensues and takes out the network.
(Not saying that is what happened here I would expect this to take out a building not to propagate across an entire distributed network, but it is absolutely possible to have a mundane network config issue that looks like something malicious when it is just simple human error.)

FAA acting CTO Rebecca Guy: "When we started to see the occurrence where our network was having instability, we started to look at what was the cause. We saw two places that were actually pinging our network at a very high rate -- 1,000 connections over every 4 to 5 seconds."
(That sure sounds like hacking!)
1
59
OpsConfig retweeted

"AI tends to solve the problems that can fit within its context window very well, but it's totally oblivious to the long term issues that can't be understood in that relatively small frame."
"AI writes overly complex code"
"Reliance on AI decreases human understanding"
Must read evanxmerz.com/post/ai-usage-…

OpsConfig retweeted

RIP, Gary Fisketjon. No editor in my lifetime—not even Gordon Lish—had a greater impact on American letters. He kept Cormac McCarthy’s novels in print before Cormac was a household name, and published The Border Trilogy at Knopf. Also: Richard Ford, Tobias Wolff, Donna Tartt, Richard Russo, Kent Haruf, and so many others.

OpsConfig retweeted

Jon Clardy: 1943-2026
One of the most impactful, creative, and (quietly) irreverent practitioners of chemical biology. Transformed how we think about nature's chemicals: their structures, their role in biology. Loved him -- he had tremendous influence on my thinking.


OpsConfig retweeted
Narrator: he was not, in fact, allowed to say “I’m quite unhappy with much of what OpenAI does.”

I’m quite unhappy with much of what OpenAI does.
I am very happy that I’m allowed to say “I’m quite unhappy with much of what OpenAI does.”
Readers added context they thought people might want to know
Korbak was fired ~3 weeks later. He says for safety concerns/METR talks (his job); OpenAI says mishandling sensitive info, not for speaking out.
x.com/tomekkorbak/st…
x.com/OpenAINewsroom…
OpsConfig retweeted

Getting to watch these beagles from Marshall Bioresources run on the grass for the first time was pure joy!
#beagles #dogsofx #marshallfarms #labdogs
OpsConfig retweeted

New Paper: Turns out that LLM think traces don't necessarily have any end-user semantics even on benchmarks specifically designed to showcase such semantics.. 🤷♂️
As some of y'all know, we have been looking at the question of end-user interpretable semantics for the reasoning models for a while (c.f. arxiv.org/abs/2504.09762 (#ICML2026),
arxiv.org/abs/2505.13792 (#ACL2026) &
arxiv.org/abs/2505.13775 (#TMLR➡️#NeurIPS2026))
One question I get asked is whether that lack of semantics just an artifact of the benchmarks *we* made.
What if we look at benchmarks that were specifically proposed to show off the semantics of thinking traces?
As it happens, earlier work by AllenZhu @ZeyuanAllenZhu has indeed created such a benchmark, iGSM, and made claims about intermediate token semantics based on it.
Since AllenZhu's work on "Physics of LLMs"--that is partly based on their analysis on iGSM was influential, we wondered whether they found conditions under which traces do indeed have semantics.
Turns out, (perhaps unfortunately for the "please let thinking traces have semantics" contingent), that iGSM traces don't have semantics either, and models trained with swapped/corrupted traces can do well too. The results seem quite in line with--rather than being contrary to--the position we have taken in our earlier work.
Read the details of this very crisp work, lead by @ratishsp and Pranabendu, in the following thread.👇 – at Tempe, AZ


Happy to share our paper, "Correct Answers, Invalid Traces: What Verifiable Grade-School Math Reveals About Chain-of-Thought Traces".
When a model gets the right answer, is the reasoning it produces also right? We test this on synthetic grade-school math where every step of a trace can be checked by a program.
Thread below.

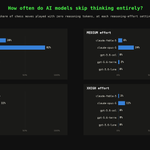
A few thoughts on why @AnthropicAI's Opus 5 sometimes felt lazy compared to @OpenAI 's models.
I like to use chess as a benchmark/eval for AI models.
It is a crude/toy benchmark, but it does a good job of giving a sense of when the frontier model's make leaps forward and helps temper some of the benchmaxxing.
1/
1
283
While regardless of chess performance Anthropic models have continued to get stronger in other domains, my own anecdotal experience was that Opus 4.5 and Opus 4.6 were the last Opus models to feel consistent.
Ever since Opus 4.7 I feel like I am constantly having to correct and double-check the model's work.
One moment the model feels smart, the next it is apologizing to me for the umpteenth time for having made a mistake.
These days anytime I use an Anthropic model for any serious work I am constantly farming out adversarial reviews to codex/OpenAI models.
This change in anecdotal vibes for me coincided with Anthropic's shift to "adaptive thinking".
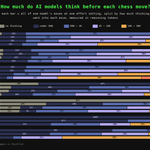
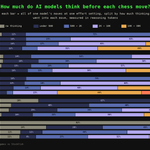
The older model's used the now deprecated "extended thinking" feature. If we add in data on the older model's we see a profile far closer to the OpenAI models as far as thinking token allocation.
Adaptive thinking definitely saves money on a per API call basis, but I do wonder to what extent that comes at the cost of quality.
8/

1
42
Comparing thinking tokens across models/providers is fraught, and of limited value.
Different models, different backend implementations, different tokenizers, etc.
Stronger models should be able to solve more complex problems using less thinking tokens/test time compute.
The older pre-adaptive thinking Opus models are weaker so even with higher thinking token allocation their performance on chess doesn't improve enough to catchup to latest OpenAI models.
With that said, I do think there is value in tracking reasoning/thinking token allocation to see how often low/zero thinking token allocation corresponds to poor performance.
21
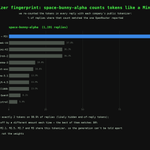
Based on the tokenizer data the new stealth model "space-bunny-alpha" appears to likely be part of MiniMax lineage.

1
1
366
Out of curiosity, I ran it through my standard chess eval gauntlet on low, medium, high, and max. It lost every game except one.
Here is one of its losses, mate in 7 moves with stockfish at 1320.
All match replays have been added to the library:
codeandstream.com/chess/#g=s…
134