
Research Scientist @GoogleDeepMind
Moutain View
Joined July 2021
- Tweets102
- Following440
- Followers896
- Likes401




Career update: I recently finished my PhD at @USC and joined @GoogleDeepMind as a research scientist, working on 3D coding for Gemini. Looking forward to the journey ahead!
This year, we won 2 Best Paper Awards at #CVPR2026 workshops:
Humanoid Everyday (humanoideveryday.github.io/) won a Best Paper Award at the Embodied AI Workshop
Ψ0 (psi-lab.ai/Psi0) won a Best Paper Award at the 3D-LLM/VLA Workshop
Congratulations to the team!
@zhenyuzhao123, Hongyi Jing, @SonglWei, @Boqian_Li_ , @yuewang314


Thanks @oier_mees and the team for this excellent survey! Proud to see DreamPlan, led by our students @JiaEmily84473 and Weiduo Yuan, featured among so many inspiring works in this space.
DreamPlan fine-tunes VLM planners entirely inside the "imagination" of a learned video world model, sidestepping costly real-robot RL for deformable manipulation.
Huge congrats to Emily and Weiduo on this recognition!
DreamPlan: arxiv.org/abs/2603.16860


𝐀𝐟𝐭𝐞𝐫 𝐕𝐋𝐀𝐬, 𝐰𝐨𝐫𝐥𝐝 𝐦𝐨𝐝𝐞𝐥𝐬 𝐚𝐫𝐞 𝐛𝐞𝐜𝐨𝐦𝐢𝐧𝐠 𝐭𝐡𝐞 𝐧𝐞𝐱𝐭 𝐛𝐢𝐠 𝐭𝐡𝐢𝐧𝐠 𝐢𝐧 𝐫𝐨𝐛𝐨𝐭 𝐥𝐞𝐚𝐫𝐧𝐢𝐧𝐠 — 𝐚𝐧𝐝 𝐭𝐡𝐞 𝐩𝐚𝐜𝐞 𝐢𝐬 𝐛𝐫𝐞𝐚𝐭𝐡𝐭𝐚𝐤𝐢𝐧𝐠 🚀 𝐒𝐨 𝐰𝐞 𝐰𝐫𝐨𝐭𝐞 𝐚 𝐬𝐮𝐫𝐯𝐞𝐲.
World models, predictive representations of how environments evolve under actions, have become one of the most important building blocks in modern robot learning. They power policy learning, planning, simulation, evaluation and data generation. And with the advent of large-scale generative video models, the field is moving faster than ever.
To help the community keep up, we wrote a comprehensive survey together with @pabbeel, @JitendraMalikCV, @jiajunwu_cs, @du_yilun, @mapo1, @philiptorr, @Jianfei_AI and many others 📖
"World Model for Robot Learning: A Comprehensive Survey"
Paper: arxiv.org/pdf/2605.00080
Project: ntumars.github.io/wm-robot-s…
@UCBerkeley @Stanford @Harvard @ETH @Microsoft @UniofOxford @NTUsg

Back in 2024, I talked to my labmates about the idea of leveraging massive ego-centric human videos for humanoid manipulation. Now we have made it! Happy to share our humanoid foundation model, Psi-0!

Introducing Ψ₀ (psi-lab.ai/Psi0) — an open foundation model for universal humanoid loco-manipulation.
🏆 Outperforms GR00T N1.6 by 40%+ overall success rate
📉 Uses only ~10% of the pre-training data
📦 Fully open-source: model, data, code, and deployment pipeline
1/10
Jiageng Mao retweeted

Introducing the USC Physical Superintelligence (PSI) Lab (psi-lab.ai). We are rebranding to better reflect our current focus. From here on out, we are tackling one thing: solving robotics and physical intelligence with every model, every bug, and every line of code. And yes, we are hiring at all levels, especially PhDs in this cycle and potential PostDocs who are excited about robotics. We hope you can join us in this journey! 1/9
Jiageng Mao retweeted

Full episode dropping soon!
Geeking out with @zhenyuzhao123, Hongyi Jing, Xiawei Liu, @PointsCoder @yuewang314 on Humanoid Everyday: A Comprehensive Robotic Dataset for Open-World Humanoid Manipulation humanoideveryday.github.io/
Co-hosted by @micoolcho @chris_j_paxton
I am incredibly honored to receive the NVIDIA Graduate Fellowship this year!
I'd like to express my sincere gratitude to @yuewang314 and @daniel_t_seita for their strongest support during the application.
I'd also like to thank the AV group at @NVIDIAResearch: @drmapavone,@iamborisi,@Boyiliee,@Yuxiao_Chen_,@yan_wang_9, Yurong You, @ChaoweiX, @danfei_xu for hosting me last and next summer. Their guidance has been instrumental to my research journey.
It's inspiring to witness @nvidia's continuous commitment to pioneering the future of Physical AI. 🤖🚀
blogs.nvidia.com/blog/gradua…
#NVIDIAFellowship #PhysicalAI #Robotics #AutonomousVehicles
Jiageng Mao retweeted

See you this Friday, Dec 5, 4:30–7:30 PM PST at Exhibit Halls C/D/E, Booth #4809. Huge thanks to my amazing coauthors and advisors!

"Who has seen the wind? Neither I nor you: But when the leaves hang trembling, the wind is passing through."
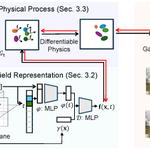
@ScottZhiyuanGao will present our work "Seeing the Wind from a Falling Leaf" at #NeurIPS2025! We teach AI to "see" invisible force fields directly from video using differentiable physics.
Project Page: chaoren2357.github.io/seeing…
Paper: arxiv.org/abs/2512.00762
"Who has seen the wind? Neither I nor you: But when the leaves hang trembling, the wind is passing through."
@ScottZhiyuanGao will present our work "Seeing the Wind from a Falling Leaf" at #NeurIPS2025! We teach AI to "see" invisible force fields directly from video using differentiable physics.
Project Page: chaoren2357.github.io/seeing…
Paper: arxiv.org/abs/2512.00762
(5/5) Our work will be presented at Poster #4809📅 Fri Dec 5, 4:30 - 7:30 PM PST 🏛️ Exhibit Hall C,D,E
Come visit on Friday to chat!
Huge thanks to my collaborators
@ScottZhiyuanGao, @PointsCoder, @Koven_Yu, @haozhelou_, @JiaEmily84473
and amazing advisors @JernejBarbic, @jiajunwu_cs, and @yuewang314.
(4/5) Physics-based Video Editing
Once we capture the wind field, we can seamlessly insert new objects into the original video.
These virtual objects interact with the real estimated wind, creating physically consistent simulations.
(3/5) We jointly model Geometry, Physics, & Interactions.
By integrating a differentiable physics simulator, we use backpropagation to minimize the error between simulated and observed motion, effectively "seeing" the force field.

(2/5) Humans have "Intuitive Physics"—we watch a leaf twirl and know the wind speed. But for computer vision, this is incredibly hard.
We propose an end-to-end Inverse Graphics framework that recovers complex, non-rigid force fields (like wind) purely from RGB pixels. No sensors, just vision.
Jiageng Mao retweeted

A robot could learn a task just by watching a generated video?
PhysWorld connects video generation with real-world robot learning.
It turns visual imagination into physical skill.
✅ Takes one image and a task prompt
✅ Generates a video showing how to complete the task
✅ Reconstructs a 3D scene from that video
✅ Learns real-world actions through object-centric RL
The result: zero-shot robotic manipulation that needs no real demonstrations.
Across pouring, inserting, sweeping, and placing tasks, success rates rise by 15% compared to earlier video-based learning.
It’s one of the first real steps toward robots that can learn from visual reasoning itself.
Thanks for sharing, @PointsCoder !!!
📍Paper: arxiv.org/abs/2511.07416
Project: pointscoder.github.io/PhysWo…
Interactive Demo: hesic73.github.io/OpenReal2S…
—-
Weekly robotics and AI insights.
Subscribe free: scalingdeep.tech
Jiageng Mao retweeted

Many people think practical robots are far away, because they can only walk and dance.
But thanks to technologies like below (training robots in simulations) we can now teach them various tasks 1000s of times faster than in real life.
That’s why humanoid robots will be extremely capable by late 2026.
Today they’re still like toys(although advanced). In a year, they’ll become one of the most useful, productivity increasing technologies we’ve ever developed.
"PhysWorld, a framework that bridges video generation and robot learning through AI (generated) real-to-sim world modeling."
This quoted post is unavailable.
Jiageng Mao retweeted

Real2sim should always be the prior to sim2real. The results look really promising! 👉Also checkout our similar paper with a real2sim2real pipeline here! teapaw.org/luccachiang/status/198…
We release OpenReal2Sim, an open-source toolbox for real-to-sim reconstruction and robot simulation.
A key difference from prior work is our focus on building an interactive digital twin from in-the-wild data — even Internet images or generated videos.
Try it out:
Interactive Demo: hesic73.github.io/OpenReal2S…
Code: github.com/PointsCoder/OpenR…
Jiageng Mao retweeted

An important step to bringing neural world models into the 3D physical world.
We release OpenReal2Sim, an open-source toolbox for real-to-sim reconstruction and robot simulation.
A key difference from prior work is our focus on building an interactive digital twin from in-the-wild data — even Internet images or generated videos.
Try it out:
Interactive Demo: hesic73.github.io/OpenReal2S…
Code: github.com/PointsCoder/OpenR…
We release OpenReal2Sim, an open-source toolbox for real-to-sim reconstruction and robot simulation.
A key difference from prior work is our focus on building an interactive digital twin from in-the-wild data — even Internet images or generated videos.
Try it out:
Interactive Demo: hesic73.github.io/OpenReal2S…
Code: github.com/PointsCoder/OpenR…