
Ph.D. student at MIT EECS, working with @phillip_isola and @vincesitzmann. Previous RA at @Oxford_VGG.
Joined August 2022
- Tweets123
- Following628
- Followers1.4K
- Likes365





Pinned Tweet
1/9 Current optimizers are static during training. What if the optimizer could think and react while the network trains?
We let an agent watch the training dynamics and rewrite the optimizer's source code as training goes: a reactive optimizer.
In every language and image setting we tried that has no tuned recipe, it matches or beats the best recipe one can one-shot, and it guards against loss spikes and overfitting by itself. In the near future, optimization decisions may belong to agents, not humans.
📝 xingjianbai.com/reactive-opt…
💻 Try it on your task: github.com/xingjian-bai/opal
🧵
OPAL also improves 0th-order optimization! A clean new piece of evidence found by Robert that online reactivity can power all types of optimizers.
“
There is an interesting moment at update 243: The record switches its gradient estimator (Boost → Cut), and the gradients change scale. All three agents had tuned their optimizers on Boost's gradients, and they lost ground right after the switch, up to 0.03 in training loss. OPAL noticed, rescaled the LM head's Adam statistics to the new gradients, and kept adjusting. By update ~620, every run was ahead of the record's optimizer again, and the informed runs stayed ahead to the end.
“

I was wondering if OPAL could help the optimizer for the 0-order noise val track.
So I took the (old 10M token) Noise benchmark's best validation-loss record (#14, 3.676) and wrapped its optimizer with OPAL. Every 50 updates, gpt-6.1-sol reads the loss and its own diagnostics, rewrites the update rule in Python, and tests it before it goes live.
Results (seed 0):
- record: 3.6758
- no agent (rerun): 3.6773
- agent, neutral prompt: 3.6791
- agent, prompt informed by the record: 3.6695
- same, xhigh reasoning: 3.6656 (−0.010 vs the record)
The OPAL system prompt mattered: telling the agent what its gradients are, how the record's optimizer came about, and how the end-of-run weight merge works turned no gain into a clear one.
There is an interesting moment at update 243: The record switches its gradient estimator (Boost → Cut), and the gradients change scale. All three agents had tuned their optimizers on Boost's gradients, and they lost ground right after the switch, up to 0.03 in training loss. OPAL noticed, rescaled the LM head's Adam statistics to the new gradients, and kept adjusting. By update ~620, every run was ahead of the record's optimizer again, and the informed runs stayed ahead to the end.
What the best agent changed, keeping the record's ANVIL II update for the weight matrices:
- per-layer rates for the residual mixing scalars, which it halved at the start
- matrix rate −10%, +20% on two query matrices, −15% on the value matrices
- longer momentum averaging (higher β1) for the scalars, head and gates
- the head's Adam rescale at the estimator switch
This is, of course, only anecdotal, and a minor improvement. Still, demonstrates that OPAL doesn't diverge and can mine small gains.
Intuitively, online agent-guided adaptation makes the most sense when hyperparameters/configurations haven't been tuned to death.
Sorry again to our infra engineers out there 😶 but changing architectures mid-training (e.g. adding and removing sub-modules) to respond to the fine-grained dynamics inside the network sounds pretty fun to me...

Xingjian Bai retweeted

I love the research direction!
You might be interested in arxiv.org/pdf/2405.16195. It tunes the HPs, architecture, and optimizer by itself, during training.
@AlexDGoldie also worked in that direction with learned optimizers arxiv.org/pdf/2407.07082
The 2 focus on autoRL.
Xingjian Bai retweeted
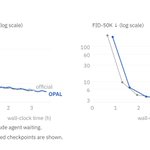
Indeed, it slows down training a bit! Section 4 of the blog discusses this, and I’ve attached some additional equal-time comparison plots. You’re right that, since I make agents react infrequently in my experiments, the overhead per run is manageable: at most 2 hours and $6–$15 in tokens. In general, the relative overhead is lower for larger-scale training runs.


Thanks @askalphaxiv for supporting blogs. Our Reactive Optimizers (OPAL) post is now on alphaXiv too.
alphaxiv.org/abs/2610.reacti…


1/9 Current optimizers are static during training. What if the optimizer could think and react while the network trains?
We let an agent watch the training dynamics and rewrite the optimizer's source code as training goes: a reactive optimizer.
In every language and image setting we tried that has no tuned recipe, it matches or beats the best recipe one can one-shot, and it guards against loss spikes and overfitting by itself. In the near future, optimization decisions may belong to agents, not humans.
📝 xingjianbai.com/reactive-opt…
💻 Try it on your task: github.com/xingjian-bai/opal
🧵

Agent cost: In our default settings, Opus 5.5 high costs $5 to $15 per run. We limit the reaction time to 100 at max; this can be adjusted at will to control budgets or perform more fine-grained control.
In the past decade, deep learning models have come to possess unreasonably effective power through training. Yet the very heart of their making, the optimizer, is still mechanistic.
Our post is an attempt to breathe the magic that training has given us into the core of training itself, forming a loop that we hope will create more capability in the future!
8/9
Send our pip package (OPAL, OPtimizer with an Agent in the Loop) to your agent and ask it to equip your training with reactive optimizers!
💻 github.com/xingjian-bai/opal
Joint work with Jia-Hao Liang, @jayden_teoh_ and @vincesitzmann.

Was playing with Astra with @sizhe_lester_li when my dad sent me this photo from ~20 years ago.
Naturally, I asked Astra to rebuild the tank I’d made as a kid — cube by cube, stick by stick.
Childhood memories came rushing back : )
🤖 Made with AI


I gave GPT-6 Astra photos of things in my apartment to rebuild in Minecraft.
The little fella walked, jumped, and built scaffolding to place blocks in survival mode. No flying or direct world edits.
This was so fun to watch! More on this soon!
With @SimulatedAnneal
Xingjian Bai retweeted

"Video models are world simulators."
Ok — can they predict a ball bouncing off another ball, off another ball? 🤨
We find standard video diffusion breaks down as the chain of dependent events lengthens — and more compute isn't the fix.
Meet the seriality gap. 🧵
1/n
Video models can now generate everything from anime clips to guitar-playing cats; language models, everything from poems to programs. Why shouldn’t robot policies eventually inherit the same generality? In VERA, we explore one route through reduction: plan in video space, then faithfully translate the visual plan into embodiment-specific actions.
This was my first robot-learning project, and I couldn’t have asked for a better introduction. I’m especially grateful to @sizhe_lester_li for bringing me into the collaboration, to @vincesitzmann for his passionate support, and to the whole team for making it such a rewarding journey!
Robot learning is moving beyond policies built for one robot, one scene, one task.
At MIT, we’re exploring a different path: turning video world models into embodiment-agnostic robot policies.
Introducing VERA: a 14B video-to-action system that controls robots across embodiments, skills, and environments.
From zero-shot pick-and-place on a real Panda arm to contact-rich cube reorientation with a 16-DoF robotic hand.
Different robots. Different environments. Different tasks.
Same video planner. Same weights.
We’re open-sourcing everything so you can fine-tune VERA for your own robot setup too. Deep dive in the thread:
🔗 vera.csail.mit.edu
🧵 (1/7)