
Ph.D. student at MIT EECS, working with @phillip_isola and @vincesitzmann. Previous RA at @Oxford_VGG.
Joined August 2022
- Tweets123
- Following628
- Followers1.4K
- Likes365





Xingjian Bai retweeted

I love the research direction!
You might be interested in arxiv.org/pdf/2405.16195. It tunes the HPs, architecture, and optimizer by itself, during training.
@AlexDGoldie also worked in that direction with learned optimizers arxiv.org/pdf/2407.07082
The 2 focus on autoRL.
Xingjian Bai retweeted
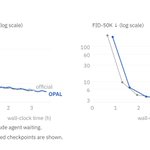
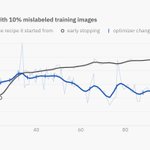
Indeed, it slows down training a bit! Section 4 of the blog discusses this, and I’ve attached some additional equal-time comparison plots. You’re right that, since I make agents react infrequently in my experiments, the overhead per run is manageable: at most 2 hours and $6–$15 in tokens. In general, the relative overhead is lower for larger-scale training runs.


