





what. almost felt out my chair looking at this?
it's basically a straight line for most of the time
can Google even make a model better than Gemini 4 Neon?


look at this smile man!
Dario Amodei on the Nasdaq podium minutes before ringing the bell for Anthropic's record $81.3B IPO

1
112

I've confirmed this is real
Gemini 4 Neon is 2x the price Gemini 4 Hydrogen, but 25% cheaper than Gemini 4 Carbon
Is this a new middle tier? Or is it actually better and cheaper than Gemini 4 Carbon?


Gemini 4 Neon is coming out today then
It's listed in the Google cloud billing catalogue, what on earth is going on

4
285
OpenAI's internal model is only ~2.5 points ahead of GPT-6.2 Astra on BenchCAD 2.1 at, ~7x the cost!
looks like they already distilled 'Bel' into 6.2 Astra?

42
This is crazy!
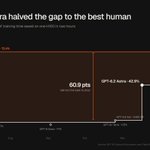
GPT-6.2 Astra just reached 59% of the best human score on OpenAI’s NanoGPT speedrun
• GPT-6 Astra: 7.7% faster
• GPT-6.2 Astra: 42.9% faster
• best human ever: 72.4%


RSI?
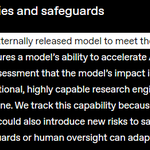
Buried in the GPT-6.2 blog
"the model’s impact is equivalent to giving every OpenAI researcher an additional, highly capable research engineer as an assistant, relative to their 2024 baseline."

32
RSI?
Buried in the GPT-6.2 blog
"the model’s impact is equivalent to giving every OpenAI researcher an additional, highly capable research engineer as an assistant, relative to their 2024 baseline."
It appears that this is the follow-up to the highly concerning post Vals AI made a few weeks ago


We have found a critical safety and alignment issue in recent public and internal models from multiple frontier labs which allows them to be misused in a high-stakes domain. It may also increase the risk of catastrophic misalignment.
We have disclosed it to the labs, and they are investigating and mitigating it. As an independent third-party evaluator, we maintain complete editorial independence and will share our findings publicly in the coming weeks.
1
19
I guess they're really doing it?
Anthropic waited... 69 days before releasing a new Frontier model (Fable 5.1 -> 5.2)
OpenAI... 75 days and counting... (6.2-Astra?)

1
59
Anthropics Fable 5.2 Promo has just ended right now
$20 Pro users no longer have access or their Fable reset

20
I feel like most models should only have 2 effort levels
Medium, and High (Extra High)
Because:
Low - really sucks
Medium - great default
High - actually just medium+
Max - experimenting (API only)


Auditors talking to staff:
OpenAI says auditors can interview, except OpenAI "will authorize and provide guidance to staff members who can speak to assessors"
Anthropic (Oct 15): "employees are encouraged to share information with them just as they would with a fellow employee"

We’re working with @ApolloResearch, @METR_Evals, @TransluceAI, and @GoodfireAI on embedded assessments: giving outside experts deep access to our internal models and systems to investigate alignment and test our safeguards.
These assessments build on our ongoing alignment and safety research, bringing independent scrutiny to how we identify and manage risks in our systems.
openai.com/index/our-first-p…

17
Some interesting stuff here:
Footnote 5 says OpenAI asks embedded third-party staff to observe a "brief cool-off period before embedding with another AI developer"
basically puts safety researchers on a noncompete cooldown from auditing Anthropic or Google
We’re working with @ApolloResearch, @METR_Evals, @TransluceAI, and @GoodfireAI on embedded assessments: giving outside experts deep access to our internal models and systems to investigate alignment and test our safeguards.
These assessments build on our ongoing alignment and safety research, bringing independent scrutiny to how we identify and manage risks in our systems.
openai.com/index/our-first-p…
29
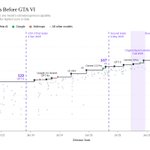
Recreated this but used ECI instead!
Since Dec 2023, ECI has climbed from 122 to 173
GPT-4 was the strongest model around the first GTA VI trailer!
Ya'll think we basically got AGI before GTA-6?


All this AI progress before GTA VI!
Since the first GTA VI trailer in December 2023, the top score on the Artificial Analysis Progress Index has more than doubled, from 160 to 358:
➤ 481 of the 491 models on the Index were released
➤ The top score was beaten on 23 separate days, by models from @OpenAI, @GoogleDeepMind, @SpaceXSI and @AnthropicAI
➤ GPT-4 Turbo held the top score on trailer day and would now rank 379th
➤ 7 of those 23 came after the revised launch date of May 26
GTA VI launches November 19. To the AI labs, please no launches that day, the team seems to be coming down with something.

42
would be really funny and kinda sad if OpenAI finally released GPT-6.2 during the same week Anthropic IPOs
that could honestly show how far they've fallen

58
Claude Fable 5.2 - Solstice Pavilion
"A concrete hall on a hillside above a bay, a basalt pool, a round hole in the roof, and the sun."
"Every pixel is ray traced in a browser shader. No meshes, no textures, no libraries."
"The light is solved, not painted"


23
Exactly this
Progress is jagged


In some ways the new Fable is a monster. This is SimpleQA Verified from Epoch. There are few benchmarks like this where Fable 5.2 jaggedly jumped ahead of the entire pack.
For me there are two big indicators arriving next week that will tell us a lot about the shape of things going into 2027. I'm assuming two things happen next week: Anthropic releases their internal progress report (from which we will get updated numbers on RSI), and OpenAI releases GPT-6.2 Astra.
With the new Astra, we will see how OpenAI answers Fable, and Fable needs to be answered. They need to close the gap, but they also need to close the gap that doesn’t show up on benchmarks: that a lot of people love working with the new Anthropic models, particularly Opus 5.5. And this is starting to tip the table a little. Also expect another huge math release simultaneously with the new Astra. The previous one took five weeks and produced 700 papers; they've had another five weeks since then. They have also been working on other Millennium problems. Don't be shocked by anything.
Astra's capability, and if it catches or surpasses Fable, is the first one. The second is where Anthropic is on AL4. The AI Futures Project (the AI 2027 guys) predict that AL4 reached 50% last month. If that's true, that means it will probably hit 80% by January. And at that point, assuming the overall pattern holds, some of the work at Anthropic will be at AL5 - aka fully autonomous with no human input. Probably about 5–10% of work at Anthropic would be at that level. If this number is actually higher than 50%, then things are moving even faster than believed, and that would be a big update for a lot of people, including me, who already has pretty short timelines. Above AL4 50% in October would probably mean RSI before the end of the year. Or possibly, already. So, a very important week for finding out where we are, and where we are headed.

1
21
If OpenAI doesn't release this week, then the next window is all the way in December because of Holidays!

It has been 72 days since OpenAI last released a frontier model - officially the longest gap since the wait between GPT-5 to 5.1 (Aug-Nov 2025)
If it doesn’t release in the next few weeks, it would become the longest gap between two OpenAI frontier model releases since o3 to GPT-5 (Apr-Aug 2025)
39