

Observations about AI, technology, war, and human behavior. Trying to understand the world. Lately, unhinged.
Jena, Germany
Joined June 2014
- Tweets3.8K
- Following251
- Followers291
- Likes5.4K







Yugant 💻 retweeted

जब लड़ना था तो अंग्रेजों की मालिश कर रहे थे अब लोकतंत्र में जोकर बनकर घूम रहे है

#WATCH | Gwalior, Madhya Pradesh: Union Minister Jyotiraditya Scindia and his son Mahanaaryaman Scindia perform traditional shastra and flag puja at Dev Ghar on the occasion of Dusshera

This is not a protest, it is a fight for freedom like we did before 1947.
This quoted post is unavailable.
17/18 My takeaway: Ornith is a strong candidate for fast local work on this 48GB Mac. Saluki is useful when memory/storage are tighter.
Before claiming Qwen-level parity, I'd want real repository tasks, more seeds, larger Qwen thinking budgets and stricter JSON output tests.
18/18 Model cards for the tested families:
Qwen: huggingface.co/Qwen/Qwen3.8-…
Saluki: huggingface.co/ConwayResearc…
Ornith: huggingface.co/ornith-ai/Orn…

14/18 Runtime: llama.cpp build 10107, Metal offload, flash attention, 32,768-token context, F16 KV, one slot.
Text-only, serial runs; no prompt reuse or speculative decoding.
Coding used the official EvalPlus checker with original + augmented tests for all 48 tasks.
15/18 Limits: small public subsets; training contamination is possible.
Coding confidence intervals are broad. Paired Qwen/Ornith coding comparison: exact McNemar p=0.25, unadjusted.
These observations establish neither general superiority nor full Qwen-level parity.
12/18 Memory trade-off:
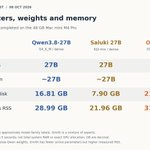
Peak process RSS: Qwen 29.0GB, Saluki 22.0GB, Ornith 31.5GB.
Main weight files: 16.81GB, 7.90GB, 21.71GB.
Ornith has fewer active parameters but higher measured RSS. Saluki is the smallest build. RSS is not total system RAM or exact GPU allocation.

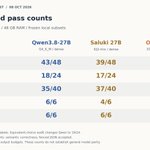
8/18 Reasoning used official MMLU-Pro labels: Qwen 18/24, Saluki 17/24, Ornith 18/24.
One question has two logically equivalent options. Accepting both gives Qwen 19/24; the others stay unchanged.
Equal official totals did not mean identical answers.

10/18 Six stateful mock workflows checked required calls, returned identifiers/data and final answers: Qwen 6/6, Saluki 4/6, Ornith 6/6.
All scored 6/6 on synthetic document tasks, up to ~24.5K prompt tokens. This does not test the models' full advertised context limits.
9/18 Tool calling: Qwen 35/40, Saluki 37/40, Ornith 38/40.
8 cases each: simple, multiple, parallel, parallel_multiple, irrelevance.
A validated local matcher checks native JSON calls against BFCL references. No LLM judge; these are not official BFCL leaderboard scores.
6/18 Median coding response time:
Qwen: 49.70s
Saluki: 89.69s
Ornith: 14.25s
Median reasoning response:
Qwen: 62.77s
Saluki: 142.89s
Ornith: 14.21s
Inference timing includes prompt + generation, excludes code grading. Answer lengths vary.

1/18 I wanted Qwen3.8-like quality with fewer active parameters on my 48GB Mac mini M4 Pro.
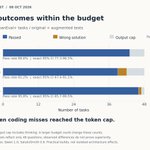
Ornith surprised me: 4.4x Qwen’s measured token rate and 46/48 vs 43/48 coding passes.
The thinking-budget caveat matters.
@ornith_ @Alibaba_Qwen

