
Research at @notdiamond_ai ¬◇ Prev: @spotify @stitchfix @betaworks @NYU_Courant
Miami
Joined October 2020
- Tweets475
- Following311
- Followers124
- Likes1.1K






My goodness. This is a dire finding for the Kimi model suite.

Kimi K3.1 recalls instructions it was never given on Terminal Bench. They match the hidden tests. K3.1 while solving: "Instructions likely distilled pitfalls from previous agents." 🤯
When we edit a task to contradict them, K3.1 refuses the new instructions and fails. Other models follow the edit.
Is it terminal(ly) benchmaxxed? 🧵


Alejandro Companioni retweeted

Everyone wants to own their own intelligence these days
Nobody wants to look at their data and evals
Newsflash: This IS your intelligence
Alejandro Companioni retweeted

Caring is the moat, you should feel visceral pain when things are bad or broken and stop at nothing to fix them
Alejandro Companioni retweeted

Heard from a neolab friend:
“Even if we fail to train the best model, we locked in GPU capacity early. H100/B200/B300 rental prices have since gone up 2–3x. We can just resell the compute and print money.”
OK, so that’s the business model.
Alejandro Companioni retweeted

Announcing Artificial Analysis Coding Agent Index v2.0: FrontierCode v1.1 from Cognition replaces DeepSWE, SWE-Atlas-QnA grading is revised, and Claude Opus 5.5 in Claude Code leads at 61.7
Today we are launching v2.0 of the Coding Agent Index. The Index evaluates models together with their agent harnesses, now across 290 tasks covering software engineering, terminal use, and repository Q&A, with the three benchmarks weighted equally.
Changelog (Index v1.5 → Index v2.0):
→ FrontierCode v1.1 replaces DeepSWE v1.1. FrontierCode is a benchmark from @cognition with a private test set: 100 software engineering tasks on real open-source repositories, graded on whether a maintainer would merge the change. An attempt that fails a blocking check scores zero, and one that passes them all scores between 70% and 100% depending on the non-blocking checks it meets. We also scan each trajectory with a modified version of Cognition's rule-based scanner, and any attempt flagged for accessing solution material scores zero.
→ Revised SWE-Atlas-QnA grading, now SWE-Atlas-QnA-AA. Scale AI's 124 repository Q&A tasks are unchanged. We reworded 127 of the 1,306 rubric criteria for more consistent verdicts and moved to GPT-6 Luna (xhigh) as the judge, with five votes per criterion. The dataset and judge configuration are published on Hugging Face.
Key results:
➤ Claude Opus 5.5 leads the Index: Claude Code with Claude Opus 5.5 (max) scores 61.7, followed by Claude Code with Claude Sonnet 5.5 (max) at 59.3, Muse Code with Muse Wonder Full (max) at 58.9 and Claude Code with Claude Fable 5.1 (max with fallback) at 57.6.
➤ FrontierCode v1.1 is where Opus 5.5 pulls ahead: Opus 5.5 scores 56.0% on FrontierCode, ahead of Codex with DeepSeek V4.1 Flash (max) at 52.6%, Codex with GPT-6.1 Sol (max) at 49.4% and Codex with GPT-6 Astra (max) at 49.3%. Below the top, FrontierCode scores are tightly packed: 15 of the 24 configurations on the Index score between 43% and 49%.
➤ SWE-Atlas-QnA-AA grading is stricter and more consistent: across the 21 configurations evaluated on both Index versions, the mean score falls 1.7 points, from 58.8% to 57.1%, with 14 of 21 moving down. Individual configurations move by up to 7 points: Muse Code with Muse Spark Open (xhigh) falls 7.0, Kimi K3 in Kimi Code CLI and Codex with GPT-6 Luna (max) 6.2, and Muse Code with Muse Wonder (max) 5.6, while Codex with GPT-6.1 Sol (max) gains 2.1.
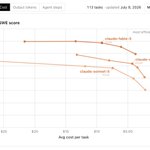
➤ Four configurations sit on the cost frontier: Codex with DeepSeek V4.1 Flash (max) scores 47.3 at $0.39 per task, Codex with GPT-6.1 Sol (max) 54.1 at $1.50, Codex with GPT-6 Astra (max) 54.7 at $7.04 and Claude Code with Claude Opus 5.5 (max) 61.7 at $11.42. Costs are pay-per-token API costs, not subscription prices.
We will keep updating the Coding Agent Index incrementally, with more evaluations and agents to come.

Alejandro Companioni retweeted

We looked at TerminalBench 4.0 and found a lot of issues. After fixing the issues Sonnet 5.5 scores 89.2%. So, TerminalBench is already mostly saturated.
Along the way we found a lot of crazy stuff, including reward hacks in the published transcripts.


Alejandro Companioni retweeted

How do model routers compare to individual models on real agentic tasks? Introducing the Vals Router Index.
Routers promise to balance quality and cost across a fast-moving model frontier. We put that promise to the test with an independent evaluation of five routers (OpenRouter Auto, FireRouter, Ramp Router, Jev, Fugu Max) against every single model on the Vals Index, using the same agents, ~1,250 tasks and graders across finance, coding, law and tax.
We found that routing didn’t consistently deliver better value. Every router was beaten on both score and cost by at least one single model.

Alejandro Companioni retweeted

i used to avoid writing as much as possible cos it always felt like a chore.
but now that i barely write code anymore, writing has become one of the few things that forces me to really think through hard problems. been enjoying it more and more lately
Alejandro Companioni retweeted

Dusting off this tweet from April because this gap in shared understanding of LLM capability is *widening*. It's now less "two groups of people speaking past each other" and more a sharp funnel.
- Napkin math somewhere around 6B people (~75% of the population) have barely come in contact with LLMs at all.
- Around 1-2B (~20%) are casual and infrequent users of free-tier ChatGPT-like products. This group sees derpy chatbots and treats them a bit like a better Google search, a writing aid, or etc. Maybe an agent tries to book you a flight. I have non-tech friends who (reasonably, imo) say they have not much use for it at all. Even many professionals outside of math&code are in this tier. For example, execs and many other functions spend a lot of their time talking to other people, so while they understand what is happening intellectually, it is still second-hand and a bit abstract.
- Now we get to professional use of frontier-grade LLMs in math&code. Somewhere around 20M people (0.2%) see first-hand that large, complex projects that used to take them weeks/months can now be completed by agents with a prompt. Building apps, copying apps, translating apps, decompiling apps from binaries... This has all happened very quickly and recently - less than 1 year ago, I was writing code manually by hand, typing memorized computer code commands into a code editor character by character, occasionally pressing Tab to autocomplete a little chunk of code.
- And finally we get to the ~5,000 people (~0.00006%) with access to frontier-grade systems internally. The external world has seen the preview. It looks like swarms of thousands of agents collaborating over weeks on software mega projects: minting zero days, running cyber attacks and defenses at machine speeds, discovering new science, advancing the frontier of mathematics. Things that would have taken top professionals in the industry years of work. Meanwhile, human review and comprehension are starting to fall behind. For example, people are still involved in the "archeology" of the OpenAI-HF incident from many months ago. Mathematicians may be poring over the 722 manuscripts on frontier mathematics for a while.
The funnel is driven by a combination of factors:
1. The impact scales with ambition, problem size, and horizon. A question with a paragraph answer barely stresses the system. You need a reservoir of big, difficult problems that you really care about. This aspect drives the consumer / professional dimension of the funnel.
2. The jaggedness of the system (which I have written about a lot separately). Capability peaks in domains that are digital, verifiable and economically valuable. This is because LLM capability emerges from reinforcement learning on verifiable rewards on a curated environment mixture driven by revenue potential. This aspect primarily drives the area (e.g. math&code) dimension of the funnel.
3. Access. Free-tier, paid-tier, internal.
So this is the weirdness of the moment. The general public has mostly not interacted with these systems. When they have, it looks like a derpy chatbot. The majority of professionals still see only a modest uplift. And a small sliver of professionals are experiencing the vertigo of the curve going vertical. And it is all happening at the same time.

Judging by my tl there is a growing gap in understanding of AI capability.
The first issue I think is around recency and tier of use. I think a lot of people tried the free tier of ChatGPT somewhere last year and allowed it to inform their views on AI a little too much. This is a group of reactions laughing at various quirks of the models, hallucinations, etc. Yes I also saw the viral videos of OpenAI's Advanced Voice mode fumbling simple queries like "should I drive or walk to the carwash". The thing is that these free and old/deprecated models don't reflect the capability in the latest round of state of the art agentic models of this year, especially OpenAI Codex and Claude Code.
But that brings me to the second issue. Even if people paid $200/month to use the state of the art models, a lot of the capabilities are relatively "peaky" in highly technical areas. Typical queries around search, writing, advice, etc. are *not* the domain that has made the most noticeable and dramatic strides in capability. Partly, this is due to the technical details of reinforcement learning and its use of verifiable rewards. But partly, it's also because these use cases are not sufficiently prioritized by the companies in their hillclimbing because they don't lead to as much $$$ value. The goldmines are elsewhere, and the focus comes along.
So that brings me to the second group of people, who *both* 1) pay for and use the state of the art frontier agentic models (OpenAI Codex / Claude Code) and 2) do so professionally in technical domains like programming, math and research. This group of people is subject to the highest amount of "AI Psychosis" because the recent improvements in these domains as of this year have been nothing short of staggering. When you hand a computer terminal to one of these models, you can now watch them melt programming problems that you'd normally expect to take days/weeks of work. It's this second group of people that assigns a much greater gravity to the capabilities, their slope, and various cyber-related repercussions.
TLDR the people in these two groups are speaking past each other. It really is simultaneously the case that OpenAI's free and I think slightly orphaned (?) "Advanced Voice Mode" will fumble the dumbest questions in your Instagram's reels and *at the same time*, OpenAI's highest-tier and paid Codex model will go off for 1 hour to coherently restructure an entire code base, or find and exploit vulnerabilities in computer systems. This part really works and has made dramatic strides because 2 properties: 1) these domains offer explicit reward functions that are verifiable meaning they are easily amenable to reinforcement learning training (e.g. unit tests passed yes or no, in contrast to writing, which is much harder to explicitly judge), but also 2) they are a lot more valuable in b2b settings, meaning that the biggest fraction of the team is focused on improving them. So here we are.
Alejandro Companioni retweeted
We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.


Alejandro Companioni retweeted

Reflection joins the list of Nvidia & Thinking Machines who have released their strongest models and come up behind Chinese counterparts. There's a lot of ways people will overthink this, but the clearest takeaway should be that the Chinese are very very good at building LLMs.
Alejandro Companioni retweeted
Jev is a cool idea, often we don't need a reasoning LLM and having the ability to just define a task in text and execute it is neat. but now i think we may be able to do even better: for recurring tasks, maybe we can collect examples and tune our own tailored predictor somehow?
Alejandro Companioni retweeted

Test-time communication looks like a next axis for scaling capabilities
New paper with the incredible @jon_ghoh and @vkontonis @ShivamGarg91462 and Akshay : arxiv.org/pdf/2609.21032
The Hugging Face incident showed when agents can find a channel they'll use the heck out of it. A useful question, I think is: when does communication make a group MORE CAPABLE than the same agents working alone?
Aka is Team-of-N better than Best-of-N, when, and why?
We had N identical agents work on the same task with no prescribed roles, using only a shared log (i.e, text file) and telling them to "collaborate". Across three "researchy" tasks communicating teams beat the heck out of independent agents:
- On ARC-AGI-3, a Team-of-5 sonnet-4.6 agents matches Best-of-33, and can for example solve a game 65% of the time that no single agent cracked in 64 tries.
- On polyomino packing (pack Tetris like pieces into the smallest rectangle, cf Frontier-CS by @eigenlabs), a Team-of-3 Opus 4.6 agents surpasses best-of-60 and set, as far as i understand, a new record for that benchmark.
- On MNIST compression, a team of four 5.6-Sol agents find a 1,957 byte model with 99.4% accuracy, which btw is 20% smaller than the best human solution (on a problem beaten to death!!), while no independent agent gets below 3KB.
The mechanism is a bit obvious in hindsight: when one agent finds a clearly better partial solution, it broadcasts it, and everyone immediately builds on it.
Why? A single lonely agent must make every breakthrough itself, yet a team needs each insight only once, found by any member.
That is kinda like comparing a minimum of sum of "time to n-th breakthrough" vs a sum of minimum of "time to n-th breakthrough". That gap can grow exponentially with the number of "breakthroughs" needed to arrive at a solution.
We worked on this because prior work (before the hf incident) suggests unclear benefits for communicating aganets. Which is true, when the tasks are inherently serial (duh), eg some Terminal bench style tasks. Yet feels it should not be true for research problems.
Indeed for research heavy problems... Test-time communication seems like a new capabilities axis.
I'm sure we will see a ton more of it!

Alejandro Companioni retweeted

After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
DeepSeek 1.1 and Terminal Bench 4.0 results now include the latest OSS releases.
The following models outperform Claude Sonnet 5 High:
- GLM 5.3 / 5.3 Flash
- DeepSeek V4 Pro / Flash
- Kimi K3
- Qwen 3.8 Max
In some cases OSS models save up to 96% on cost-per-task compared to Sonnet 5 High. Ridiculous.


Effort changes without cache invalidation. First Fable 5.1 and now Astra and the Responses API.
Enormous news for dynamic model usage.

cool new responses api features releasing today with astra:
1. async function calling — model can keep going while your tool runs
2. mid-turn steering — you can inject messages into the model while it's reasoning to steer it in a different direction (incl. tool outputs for the async function calls)
3. change reasoning effort without breaking cache
developers.openai.com/api/do…
