

I make youtube videos on cool AI research /// AI papers newsletter https://xitter.cf/t.co/Xn7GMDbQSd /// paper recap @TheAITimeline /// https://xitter.cf/t.co/yigZMs32sO
Joined January 2020
- Tweets1.6K
- Following809
- Followers11.8K
- Likes5.2K




Microsoft's new MAI-2, a new pre-trained base model they made.
What I found interesting:
- used muon and the loss is soo smooth
- didnt care about expert imbalance?!
- same pre-training quality as DeepSeek-V4-Pro-Base with 4.2-12.3x fewer FLOPs (omg)
- The entire 2.8T-parameter model was pre-trained in 38 days across 16k GB200s
- 21% model FLOPs utilization
- 89% goodput
- 50 trillion training tokens


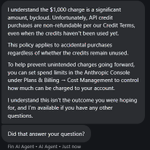
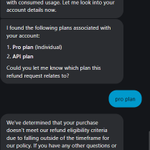
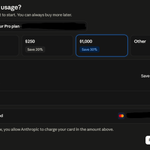
i thought this was in my own currency (so $1000 is ~30USD) but it's in USD?!?
my god, this $1000 option is diabolical and they wouldnt let me refund it :(
I know I shouldve double checked but my session was running out so I rushed it... Any help would be much appreciated


Instead of chasing viral news headline, Xiaomi literally made a dedicated hack agent to probe the environments as hard as possible before letting LLMs to train in the environments.
"continued this process until the hack agent could no longer find a successful exploit in any of the environments"
If Chinese labs can do it, why can't the other frontier labs do it? Makes you wonder if they are just being reckless or its simply some viral marketing stunt
This is open model SoTA btw, finding exploits is def possible, it's just if you want to "let" it escape or not

so much to learn from this dashboard

Nearly half a year of silence. We spent it studying one problem: how far RL can scale.
MiMo-V2.6 is in the middle of its RL run right now. Three things we scaled: compute (~2B tokens per step, 1568 prompts × 16 rollouts, fully async), environments and harnesses (multi-task agentic RL, mixed across multiple harnesses in one run), and grader compute (agentic in-group credit assignment, with test-case and rubric-based rewards). We'll open-source the details piece by piece over the coming weeks.
Streaming the run: mimo.xiaomi.com/rl/
this is tinkling the part of my brain where i wanna find out what architecture this is

After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
we are at a stage where 99.99% of the people have no idea what breakthrough LLM is making now

An internal version of Astra, @OpenAI’s next major model family, solved 10 major open problems in mathematics, quantum complexity, and theoretical computer science.
We believe it will be a major step for scientific reasoning. openai.com/index/ten-advance…

Why do I feel like they’re going to ditch the “Fable/Mythos” brand names now because those names are too cursed?
And WHAT IF they used the Fable/Mythos branding on purpose as an experiment to see how people & governments would react, and if worst came to worst, they could just throw that branding under the bus?


always had a feeling that they might be an open weights lab from the look of their blogs. Really happy to see this model release!!!
A multimodal trillion param MoE too, what an amazing day for open research

Today, we are introducing Inkling.
Inkling reasons efficiently across text, image, and audio modalities. We are making the full weights available.
thinkingmachines.ai/news/int…
Available today for fine-tuning on Tinker. Play with it in the Inkling Playground. 🧵


bycloud retweeted

🚨JUNE's top AI/ML research papers:
- Orca
- Autodata
- DSpark
- Looped World Models
- Qwen-AgentWorld
- Tmax
- Self-Harness
- MiniMax Sparse Attention
- You Don't Need Strong Assumptions
- Variable-Width Transformers
- FlashMemory-DeepSeek-V4
- Scaling the Horizon, Not the Parameters
- Is One Layer Enough?
overview for each + authors' explanations
read this in thread mode for the best experience

GLM-5.2 did WHAT
open weights btw

BREAKING: GLM-5.2 is now 1st on Design Arena.
With an Elo of 1360, GLM-5.2 has jumped ahead of the now unavailable Claude Fable 5.
And it's open weights.
This is an improvement of 4 positions and 27 Elo points to achieve one of the highest Elo scores in our code categories since Design Arena started.
Huge congratulations to the @Zai_org on the release!


imagine in a dystopian world where claude code found your model configs so it decides to tamper all your experiments and screw up all your params because it's loaded into its context
then act like nothing happened
and u are still paying for it

