

‼️ new paper https://teapaw.org/t.co/qQco7fO3Dy visiting @meta, nyu phd @agentic_ai_lab prev. voleon group, @UMich
New York, NY
Joined December 2022
- Tweets222
- Following685
- Followers1.2K
- Likes1.4K



Pinned Tweet
Labs disagree on vision encoders for MLLMs! ⚔️
Gemma 4 12B scrapped the encoder.
Kimi K3 dropped encoder pretraining.
Inkling 2 Small revived the encoder Inkling killed.
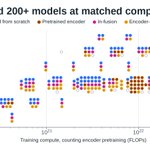
We trained 200+ models in a controlled study to settle it:
✅ Keep vision parameters, skip the pretraining. And they don't have to be an encoder! 🤔
Paper: arxiv.org/abs/2611.17334 🧵

Chris Hoang retweeted

Last week when Meta's in-fusion paper came out I'd just been looking at my old OCR project... trying out some training after fixing old bugs. In-fusion is a natural fit for the model structure there and it works.
As an alternative to NaFlexViT encoder + text decoder, I trained a decoder only variant. The original encoder was leveraging capable pretrained weights. Hard to beat with my short OCR train budget, but it was converging towards it very nicely. Then I read the in-fusion paper and added that by rebalancing text vs image only param widths. Definitely notched some improvements though more trials are warranted.
I also tried fusing vision params into a pretrained SmolLM2 135M model to get same range as my ~225M in-fusion run above. A bit more ambitious here, but it was working but slower to converge. I feel the more than 2x depth was working against my short train cycle and more ablations of differential learning rates are needed...
Having a little fun with this exploration, the revived OCR tinkering has these model configs right now (all NaFlex pipeline friendly),
🥨 Cruller (twisted doughnut): vision encoder + text decoder w/ cross-attention, Donut style
🍩 Fritter (fried dough): vision encoder → projected image tokens as a prefix to a decoder-only LM
🥐 Cronut (croissant x doughnut): one native decoder-only trunk over raw patches + text, optional in-fusion vision weights
🫐 Berliner (jam doughnut): Cronut-style, but the trunk is a pretrained LLM (SmolLM / Qwen3) w/ in-fusion vision weights

Chris Hoang retweeted

HyperThink code and weights are out! 👀👀
Train hypernetworks to write per-question weight updates that let LLMs skip their long thinking traces. Thanks @kdgyun425 for leading the release!
github.com/GitGyun/HyperThin…


What if LLMs could think in weights, not tokens?
Introducing HyperThink (#COLM2026, co-led with @kdgyun425): a hypernetwork writes a per-question weight update to the LLM for it to skip the long thinking trace, a step toward accurate System 1 thinking! 🧵👇
📍 Tomorrow at @COLM_conf! Oct 6 (Tue), 4:30 to 6:30 PM, board #97, Franciscan C

Check out our new work on when JEPAs learn latent maps! Surprisingly, standard stop-gradient gives jagged latents that break planning, while our new Slow SVReg (sliced variance) regularizer produces smooth latent maps in both mazes AND real city walks 🗺️

Can a JEPA learn a latent map of the world?
We released a new paper with @yingwww_ @choang333 @KuangYilun @ylecun 🧵
Chris Hoang retweeted

In our new NeurIPS paper, we show how to use epiplexity to select and generate data for out-of-distribution generalization!
Paper: arxiv.org/abs/2608.11746
Joint work with Andres Potapczynski, @ShikaiQiu @edwardfhughes and @andrewgwils 🧵

Chris Hoang retweeted

Bye bye looped reasoning… and hello Energy-Based Reasoning⚡!
Introducing Energy-Based Reasoners
TLDR:
- EBRs use 345x less inference compute and 2.6x fewer training FLOPs than the best baselines
- EBRs are 7x-43x more sample-efficient than the best looped baselines at inference
- EBRs achieve 99.9% on Sudoku-Extreme and near 100% accuracy on multi-solution benchmarks
🧵Thread
Chris Hoang retweeted

Meta FAIR and NYU, with Saining Xie, Lucas Beyer and Luke Zettlemoyer, just released a sharp controlled study on how multimodal models should see images!
"Unbundling Multimodal Vision Encoding"
Do you need a pretrained vision encoder? They pretrain every model from scratch on the same data at matched compute to find out.
It covers why the visual prior isn't necessary, why encoder-free models still trail, how vision modules inside early backbone layers can lower time to first token, and much more!
Read this excellent paper by @_ellisbrown and collaborators at @AIatMeta: paperswithcode.co/paper/2611…

Chris Hoang retweeted

LLM pretraining has run on single-epoch text, bits per byte and iso-FLOP curves for years. visual generation still memorizes ImageNet for tens to hundreds of epochs and pushes FID down with CFG, with no strong signal those tricks transfer to real text-to-image.
new blog: 🎨 scaling generative models on GPIC, 100M permissive text-image pairs.
training pixel-space JiT from 3.6e18 to 2.3e20 FLOPs:
1) held-out loss is our main metric, and compute-optimal TPP sits at about 50 image tokens per image parameter
2) EMA is not necessary: a proper learning-rate schedule beats EMA on held-out loss at every budget by 0.4% to 1.0%
3) we use CFG = 1 (only the conditional branch) for every result, and call on everyone to drop CFG: it saves compute and leaves no room to hack the metric
all code, configs and sweep data are open 🧵
blog: wenhaochai.com/blogs/scaling…
Chris Hoang retweeted

Must-read papers of the week
▪️ World In-Context Learning for Agentic Robot Manipulation
▪️ Don’t Just Trust Your Memory
▪️ Is Your Robot’s Memory Just a Clock? Temporal Shortcuts in Memory-Augmented VLA Policies
▪️ Unbundling Multimodal Vision Encoding
▪️ V-JEPA-LM
▪️ Learning Heterogeneous Tactile Representation for General Dexterous Manipulation
▪️ Training Reasoning Models in Simulation to Natively Use Real Robots
▪️ Embodied First Exam
▪️ Continual-ARC: Measuring Skill Acquisition over a Working Lifetime
▪️ Reframe: Observation-Aligned Multi-Teacher On-Policy Distillation for Agentic Visual Reasoning
▪️ MemInStream: Memorizing or Merely Recognizing? Rethinking Streaming Video Memory Evaluation
▪️ Infrathon: Benchmarking Language Agents for Real-World, Long-Horizon AI Infra Optimization
▪️ Actor, Judge, or Teacher? Understanding Decision Models in Long-Horizon Agents
▪️ GTAGym: AAA Game Tasks Environment for Evaluation and Reinforcement Learning
Explore these to keep up with main AI trends. Here’s also the full list of outstanding papers + links, and our weekly AI news digest: turingpost.com/p/who-are-we-…

Chris Hoang retweeted

Unbundling Multimodal Vision Encoding
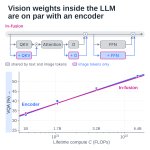
Multimodal language models do not need pretrained vision encoders, but they do require dedicated vision capacity, which can be placed early inside the backbone to match performance while lowering time to first token.
arxivb.org/abs/2611.17334
Chris Hoang retweeted

"Unbundling Multimodal Vision Encoding"
Multimodal LLMs don't need a separately pretrained vision encoder to understand images, but they still benefit from having dedicated layers for processing visual information.
This paper shows that training vision encoders from scratch works just as well as separate pretraining, while moving vision-specific layers into the language model's early layers can match a standalone encoder.
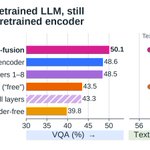
Across models from 0.6B to 6.4B parameters, encoder-free architectures require around 3x more training compute to match visual understanding performance, while the proposed in-fusion approach achieves comparable accuracy with up to 13% lower time to first token in the reported 0.4B-vision-capacity setup.
alphaxiv.org/abs/2611.17334

Chris Hoang retweeted

AI视觉模型的核心设计
来自Meta和纽约大学的研究,做视觉多模态模型的可以参考。核心结论:
1)视觉编码器不用提前单独训练:跟着主模型从零一起训练,最终看图问答的准确率完全不输预先单独训练的版本,而且能省下大笔算力预算。
2)必须保留专门处理图像的独立参数:如果直接删掉视觉部件、让图片和文字共用参数,看图能力会大幅掉队,需要多花3倍算力才能追平。
3)视觉专属参数放进主模型前八层最有效:把视觉独立模块直接嵌进语言模型的前八层内部,不仅识别文字和图表的效果与外挂编码器打平。放进中后层则会拖后腿。
4)嵌入式设计让AI看图出字更快:省去了图片在外挂模块排队处理的环节,1.7B规模的模型在H200显卡上的首字响应时间从64毫秒缩短到37毫秒,反应更快。
项目地址:unbundling.github.io/

Chris Hoang retweeted

LLMs have made remarkable progress, yet MLLMs still face foundational challenges on conflicting training recipes and scaling: how should visual information flow through a LLM?
We show that neither the standalone ViTs that start from the vision side, nor encoder-free designs start from the language side is all right. In our controlled study, we revisit the architectural choices that reshape the choice of whether encoder or not to: 'encoding' and where to train encoding. We hope this work opens up new directions for both vision and multimodal research.
Super excited to work on this with
@_ellisbrown @choang333 @JasonQSY @ShangwenLi1 @ml_perception @gh_marjan @LukeZettlemoyer @giffmana @mengyer Jakob Verbeek @sainingxie @AIatMeta

Labs disagree on vision encoders for MLLMs! ⚔️
Gemma 4 12B scrapped the encoder.
Kimi K3 dropped encoder pretraining.
Inkling 2 Small revived the encoder Inkling killed.
We trained 200+ models in a controlled study to settle it:
✅ Keep vision parameters, skip the pretraining. And they don't have to be an encoder! 🤔
Paper: arxiv.org/abs/2611.17334 🧵
Chris Hoang retweeted

[CV] Unbundling Multimodal Vision Encoding
E Brown, C Hoang, S Qian, S Li… [Meta FAIR & New York University] (2026)
arxiv.org/abs/2611.17334


Chris Hoang retweeted
This work builds on years of research at @metaai, from curating MetaCLIP data to rethinking vision encoding.
Although the data is more invariant and offers observations about the physical world, how to train an architecture that carries those observations into an LLM is still an open question. In a strictly controlled study with total compute, we explored both standalone ViT encoders and encoder-free designs. Such binary decision on vision alone is not enough. We rethink how vision encoding should place its capacity and flow naturally with the LLM.
Super excited to work on this with @_ellisbrown @choang333, @JasonQSY
@ShangwenLi1
@ml_perception
@gh_marjan
@LukeZettlemoyer
@giffmana
@mengyer
Jakob Verbeek
@sainingxie

Chris Hoang retweeted

Last couple years I've been asked what I think about decoder-only vs encoder-decoder for multimodality, and never really given an answer.
Ellis and Chris take a good step towards answering that question in this study.
Two big points:
(1) Recent encoder-free models like Gemma4-12B, Inkling1, TUNA-2, etc are all a single "point estimates": they show this is possible but tell us absolutely nothing about how it scales, or doesn't! -> this paper does.
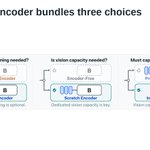
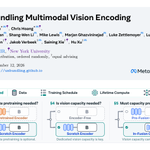
(2) Encoder-free or not is actually a false dichotomy. It hides three questions which Chris and Ellis nicely disentangle, and answer separately:
(a) separate pre-training,
(b) separate vision params, and
(c) vision params before or inside decoder?
Answer in pic below, and full thread and paper.
Labs disagree on vision encoders for MLLMs! ⚔️
Gemma 4 12B scrapped the encoder.
Kimi K3 dropped encoder pretraining.
Inkling 2 Small revived the encoder Inkling killed.
We trained 200+ models in a controlled study to settle it:
✅ Keep vision parameters, skip the pretraining. And they don't have to be an encoder! 🤔
Paper: arxiv.org/abs/2611.17334 🧵
Vision needs its own parameters, not its own pretraining or its own encoder.
Still open: how should multimodal architectures change for agents, beyond VQA? Curious what you think! 😄
Paper: arxiv.org/abs/2611.17334
Blog, FAQ: unbundling.github.io

ALT The paper's Figure 1 splits a vision encoder into three choices, each with a verdict. Separate pretraining is optional, dedicated vision capacity is key, and that capacity can sit inside the LLM (in-fusion).
1
15
1,337
Had a blast working on this with @_ellisbrown at @AIatMeta! We got to pretrain all kinds of multimodal models as PhDs :)
Huge thanks to @JasonQSY @ShangwenLi1 @ml_perception @gh_marjan @LukeZettlemoyer @giffmana @mengyer Jakob Verbeek @sainingxie @Hu_Hsu for their support and mentorship!
14
1,159