




Pinned Tweet
We've raised a $7.4M seed round led by @a16z to build the agent operating system for security teams.
Threat actors now scale with tokens. Campaigns that used to require a coordinated team can be run by a small group with the right model harness. Defense has been absorbing that hit with the same playbook and the same headcount. We built Cotool to make defense compound in the same way.
Grateful to the team at @a16z , @YCombinator, @WndrCoLLC , @homebrew , and our angels from Okta, Ramp, Cloudflare, and others who've lived this problem firsthand.
If you’re a security practitioner looking for more leverage in the AI age, come see how Cotool can help!
Last week, Cotool teamed up with @ycombinator to host security leaders from @WeAreLegora , @HelloSurgeAI , and @material_sec to talk about building a security org from 0 to 1 in hyper-growth environments.
Much of the conversation was around how to get the most leverage out of a lean (or non-existent!) team: starting where you already have buy-in, hiring builders over operators, and using AI agents to take on the noise humans used to spend time triaging.
Special thanks to our fantastic panelists @aluveaux, @ffwang2, Rajan Kapoor, and @maxpollard415.
And a huge shoutout to @koomen and team for the beautiful space and making the event happen in the first place!


Haiku punches above its price.
Claude Haiku 5.5 matches Argon’s detection engineering score. Average cost: $0.59 per task, less than a tenth of Argon’s.
The best model depends on the work. Explore the full results:
cotool.ai/research/bluebench
Here's our co-founder and CEO @maxpollard415 on the time he network-contained himself in the middle of a demo.
About a year ago, he hit approve when he meant to hit reject, and dropped out of the demo. With the tools available back then, getting back online took 30 to 45 minutes.
Max's point to @vtahowe on the @insecureagents podcast: sometimes that's the cost of doing business. When the value of reacting quickly is clear, you let the agent act and accept the consequences.

GPT-6 Astra remains the most consistent model we've tested, and still leads incident response and detection engineering.
The best model depends on the work. We publish capability, cost, reliability and per-track results so teams can make that tradeoff.
Explore the updated BlueBench results on our new research site.
Compare frontier and open-weight models, inspect the methodology, and follow the changelog as new results come in.
Full leaderboard: cotool.ai/research

Cotool is hosting Cyber Night at @ycombinator, an evening for builders, practitioners, and investors in security.
For us, it's a return to where Cotool started. Details below 🧵

Cotool cofounder @maxpollard415 will moderate a panel with:
Kyle Polley (@kpolley), CISO at @perplexity_ai
Jonathan Aluveaux (@aluveaux), CIO at @WeAreLegora
Frank Wang, Head of Security at @HelloSurgeAI
the panel will be bookended by time to connect over food and drinks with security leaders from across the industry.
space is limited, so please RSVP here: events.ycombinator.com/yc-cy…

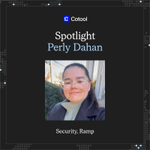
Introducing our inaugural spotlight series on X with
@_Shark_byte!!
Perly started as an artist; published three times, 35 pieces for startups. Then interned in vulnerability management at Universal Music Group and launched Shark Byte Labs to share her learnings with the community. Now a security analyst at Ramp, she ships on the team and runs CTFs and content on the side. 🧵

𝐖𝐡𝐚𝐭 𝐝𝐨 𝐦𝐨𝐬𝐭 𝐩𝐞𝐨𝐩𝐥𝐞 𝐠𝐞𝐭 𝐰𝐫𝐨𝐧𝐠 𝐚𝐛𝐨𝐮𝐭 𝐠𝐞𝐭𝐭𝐢𝐧𝐠 𝐠𝐨𝐨𝐝 𝐚𝐭 𝐬𝐞𝐜𝐮𝐫𝐢𝐭𝐲?
I think all the platforms like try hack me / hack the box etc
They’re really good, but I remember starting out I was very confused trying to work out a lot of CS basics backwards from the security applications
I think you should start with some IT fundamentals, learn to code, learn CS and THEN get on these platforms
𝐖𝐡𝐞𝐫𝐞 𝐝𝐨 𝐚𝐠𝐞𝐧𝐭𝐬 𝐡𝐞𝐥𝐩 𝐢𝐧 𝐲𝐨𝐮𝐫 𝐝𝐚𝐲-𝐭𝐨-𝐝𝐚𝐲, 𝐚𝐧𝐝 𝐰𝐡𝐞𝐫𝐞 𝐝𝐨 𝐭𝐡𝐞𝐲 𝐠𝐞𝐭 𝐢𝐧 𝐭𝐡𝐞 𝐰𝐚𝐲?
For me I use agents to analyze large sets of data and dig through the haystacks. normally looking up the supporting evidence for an alert could take a bunch of queries and organizing all of that to make sense
Now agents can do that for you, giving team the time to focus on building and experimenting with new ways they can cover more ground and go deeper
Today we're releasing BlueBench-Simulation, a brand new benchmark suite evaluating agent performance on defensive cybersecurity tasks against simulated enterprise environments.
BlueBench-Simulation is releasing with 12 scenarios across 3 new benchmarks, each covering a different stage of the intrusion lifecycle:
- Initial Access & Command-and-Control (C2)
- Identity & Active Directory Attacks
- Impact & Exfiltration
Every scenario is a generated enterprise environment with weeks of routine activity hit by an intrusion. Models start from a single weak alert and produce a threat hunting report, an incident response report, or a detection query.
- The most notable result, @spacexai's Grok 4.6 led the suite at 71.8%, taking two of the three benchmarks and finishing first overall on pure capability.
- @claudeai Opus 4.8 came in second at 68.9%. We'd expect Anthropic's newer models to do at least as well, but Fable 5, Opus 5, and Sonnet 5 all ran into cybersecurity refusals, so we couldn't get a clean read on them.
- The @OpenAI GPT-5.6 model family once again anchored the value end of the Pareto curve
More details in thread below ⬇️
Full results: cotool.ai/research

BlueBench is our series of benchmarks for AI agents doing defensive security work. The Intrusion benchmarks replay real compromises. Simulation builds on that with fully generated environments: a small enterprise with normal baseline activity, an intrusion, and benign lookalikes that punish pattern-matching without verification.
Because we author the environment, we're able to ensure the ground-truth is complete and that the data isn't leaked into model training sets.
Our last Intrusion release, if you missed it: xitter.cf/cotoolai/status/208835…

Today we're sharing BlueBench-Intrusion-003, a new benchmark testing cyber incident response using data from a real intrusion of a live AWS environment.
Each model started with a security alert and investigated events across CloudTrail, GuardDuty, S3 access logs, and VPC Flow Logs before writing a complete incident response report.
Key results:
1️⃣ GPT-5.6 Sol led at 88.3% and was the most consistent top-performing model. GPT model family dominates the pareto frontier.
2️⃣ Kimi K3 led the open-weight models at 85.1%.
3️⃣ Anthropic was the only provider affected by service-level cybersecurity refusals.
Full interactive results in 🧵⬇️

We @cotoolai have signed OpenAI's open letter calling for collective action on cyber defense, alongside @AnthropicAI , @Google , @CrowdStrike and other leading companies.
As models get more capable, AI-enabled attacks will become far more widespread and far more sophisticated. Those same AI advances have the potential to give security and technology teams new ways to defend, fix weaknesses, and make our digital world much more secure.
Cotool is committed to making AI-powered defense genuinely deployable for the teams protecting essential services, share what works instead of hoarding it, and measure ourselves on how many organizations are protected and whether the fixes hold
We're privileged to stand alongside these teams in accelerating defenders' priorities with tools, funding, and hands-on support.
The letter is worth reading in full: openai.com/collective-cyberd…
