

PhD on high troughput bioinformatics @ ETH Zurich; IMO, ICPC, Xoogler, Rust, road-cycling, hiking, wild camping, photography https://xitter.cf/t.co/wBv2zN4F80
- Tweets1.9K
- Following81
- Followers1.2K
- Likes4.7K

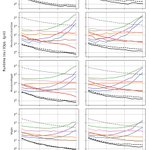




ALT Log-log time-per-operation plots for different workloads. The x-ax has increasing input sizes, and the y-ax has the normalized time per push-pop pair of operations divided by lg n. The binary heap, d-ary heap, and weak heap all slow down as n increases, while the I/O-efficient heaps all get faster. The SimdQuickHeap is 2x faster than the radix heap and up to 10x faster than the binary heap.

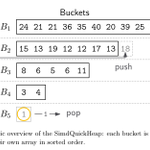
ALT Overview of the SimdQuickHeap data structure: a list (vector) of pivots is stored, and the elements between consecutive pivots are stored in their own bucket (also a vector). The elements in a bucket are in between the two pivots surrounding it.


ALT Priority queues are data structures that maintain a dynamic collection of elements and allow inserting new elements and removing the smallest element. The most widely known and used priority queue is likely the implicit binary heap, even though it is has frequent cache misses and is hard to optimize using e.g. SIMD instructions. We introduce the SimdQuickHeap, a variant of the QuickHeap that was introduced by Navarro and Paredes in 2010. As suggested by the name, the data structure bears some similarity to QuickSort. We modify the data layout of the original QuickHeap to have all pivots adjacent in memory, with elements between consecutive pivots stored in dedicated buckets. This allows efficient SIMD implementations for both partitioning of buckets and scanning the list of pivots to find the bucket to append newly inserted elements to. The SimdQuickHeap has amortized expected complexity O(log n) per operation, which improves to O(frac 1Wlog n) in non-degenerate cases, where W is the n

ALT Priority queues are data structures that maintain a dynamic collection of elements and allow inserting new elements and removing the smallest element. The most widely known and used priority queue is likely the implicit binary heap, even though it is has frequent cache misses and is hard to optimize using e.g. SIMD instructions. We introduce the SimdQuickHeap, a variant of the QuickHeap that was introduced by Navarro and Paredes in 2010. As suggested by the name, the data structure bears some similarity to QuickSort. We modify the data layout of the original QuickHeap to have all pivots adjacent in memory, with elements between consecutive pivots stored in dedicated buckets. This allows efficient SIMD implementations for both partitioning of buckets and scanning the list of pivots to find the bucket to append newly inserted elements to. The SimdQuickHeap has amortized expected complexity O(log n) per operation, which improves to O(frac 1Wlog n) in non-degenerate cases, where W is the n