

I build and teach how you can build cool tech - 🛠️🤖 15+ years as Fullstack Software & AI Engineer & Startup Founder
Joined September 2011
- Tweets511
- Following232
- Followers142
- Likes793
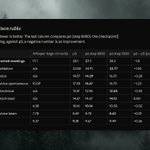


Day 7 of my 30-day local AI challenge: my Spanish speech model, trained on my Mac, is getting closer to Whisper.
One change this round: I fine-tuned the audio encoder from layer 3 up with LoRA, which adds 4.87M trainable params. Same data as before, 8000 steps.
On real meetings, hand-corrected, WER went 28.1% → 27.1%. Whisper large-v3-turbo gets 17.1%.
On spontaneous speech (Common Voice) it went 17.9% → 16.7%. Whisper gets 10.1%.
On volunteer recordings it's 9.7% vs Whisper's 9.4%, only 0.3 points behind.
The lesson: the checkpoint with the best validation WER wasn't the best model. Step 3500 won on validation but was worse on real meetings, 28.3%. I kept step 8000.
Whisper is still ahead on every test. The gap is closing, though.
Devs: do you pick checkpoints by validation loss or by a held-out real-world set?

Prompt:
Go online and research all the things that have happened in information security in the past 5 days. Today is October 24, 2026. Then fix any security issues everywhere in the server. Ask me questions if you need to

Fix the security issues on your server with this prompt for Codex/GPT-6 Astra. You can try Claude Code/Opus 5.5 too but the stupid auto classifier may block you.
You need to have connected your Codex project to your server via ssh before.
"Go online and research all the things that have happened in information security in the past 5 days. Today is October 24, 2026. Then fix any security issues everywhere in the server. Ask me questions if you need to."


Eduardo Aguirre retweeted

LA MEJOR INVERSIÓN DE TOKENS QUE PUEDEN HACER HOY, prompt: "Haz una auditoría de seguridad de este equipo, repórtame los problemas que encuentres" Y sigan las recomendaciones de su agente de confianza.
I ported it to @Claude Code and made it open source. And it works for PHP and @nodejs too.
@OpenAI built a security skill for Codex.
Your website shouldn't be less secure just because you use a different coding agent.
Here's the repo 👇
github.com/masteread/php2she…


If you are wondering whether your website is affected, we have packaged a Codex skill to help check.
Point your Codex at this repo to guide you through it: github.com/openai/php2shell-…

Hola! las personas que tienen equipos que construyen o utilizan PHP y node.JS
Se detectaron brechas importantes de seguridad a nivel global en ambos lenguajes.
Comparto para que puedan comparitr con equipos técnicos y los puedan blindar:
nodejs.org/en/blog/vulnerabi…
php.net/archive/2026.php#202…


I know the world use English as main language but when I see every day a new release like this one I can’t help thinking that Spanish / Hispanic developers we also should be doing this

Today we’re releasing Underdog Bark 3.0, the #1 frontier speech model
It's a tiny 163 MB download as accurate as NVIDIA’s Parakeet (15x bigger). It beats OpenAI's Whisper large-v3 (57x bigger)
It's fast- transcribes 1 min of audio in <0.25s on a Macbook. On recorded meetings (AMI), Bark 3.0 gets 7.82% of words wrong. Parakeet gets 9.42%. OpenAI's Whisper large-v3 gets 13.63% error rate
Bark runs on both your Laptop & Phone. It’s free and open source under CC-BY 4.0
Try private on-device meeting notes & dictation, powered by Bark, in Underdog today: underdog.ai/bark

Day 6, and funnily enough we're on v6 of my Spanish speech-to-text model.
Lesson of the day: public benchmarks lie a little.
On standard test sets, v6 is now close to Whisper:
• Lab recordings: 10.1% vs 9.4% WER
• Common Voice LatAm: 8.5% vs 7.8%
• FLEURS: 9.9% vs 6.6%
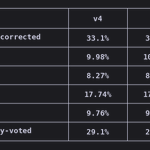
But on real meetings, hand-corrected, the gap is still big: 33% vs 17%. Real audio is messy: crosstalk, background noise, people trailing off.
The biggest win came from real data: on real calls voted on by the community, error dropped from 29.1% (v4) to 20.1% (v6). Training on what people actually sound like beats squeezing another decimal out of clean audiobooks.
If you speak Spanish, you can help: record a few phrases here 👉 escucho.ai/labs/training. It takes under a minute and it's anonymous.
Devs: what's your best trick for closing the gap between benchmark WER and real-world WER?


Day 5 of my 30-day local AI challenge: my Spanish speech-to-text model went from 57.6% → 24.6% → 10.9% WER in 3 versions.
Still building on @TslShahir's EG2-Transcribe idea: a frozen EmbeddingGemma 2 turns audio into vectors, and a small 86M-param reader picks one whole word every 40 ms. Only the reader is trained.
Where it stands vs Whisper:
• FLEURS Spanish: 10.9% vs 6.6%
• Lab recordings: 10.8% vs 9.4%
• Common Voice LatAm: 10.2% vs 7.8%
• Spontaneous Spanish: 19.5% vs 10.1%
• Speed: ~80× real time vs ~20×
Fair-test notes:
• v2, v3 and Whisper were measured with the same rules, same audio, and voices the reader never heard in training.
• v1 used different rules, so it's only a rough comparison.
The gap is clearly spontaneous speech: fillers, false starts, people talking over each other.
Devs, I'd love your take:
1. How would you close the spontaneous-speech gap? More conversational data, or a different decoding strategy?
2. Whole-word dictionary (~307k words) vs subwords for Spanish: worth switching?
3. What Spanish test set should I add next?
Drop your ideas below 👇 I'll test the best ones and credit you.

Day 4: first results! Inspired by @TslShahir's EG2-Transcribe (built on EmbeddingGemma 2), my Spanish ASR went from 57% to ~24% WER, and it runs 81× real time vs Whisper's 20×.
Whisper still wins on accuracy (6.6%). Long way to go. More soon. 🧵

Claude use claude to build claude

Claude writes about 90% of Claude Code's code.
From June to September, merged PRs more than doubled while the share reverted fell by more than 40%.
We wrote about how we changed code review to get there, and how to adopt it:
claude.dev/blog/solving-code…

Eduardo Aguirre retweeted

Claude writes about 90% of Claude Code's code.
From June to September, merged PRs more than doubled while the share reverted fell by more than 40%.
We wrote about how we changed code review to get there, and how to adopt it:
claude.dev/blog/solving-code…