

i teach robots to use their hands @markovrobotics formerly Yale PhD student, Linguistics M.A., Yochan lab member
San Francisco, California
Joined September 2023
- Tweets17
- Following100
- Followers208
- Likes147


kstechly retweeted
super excited to partner with @ltx_io for a Day 0 launch with them!

Introducing LTX-2.5, the world model the world builds on.
One of the biggest upgrades yet to the model already powering film, robotics, and real-time workflows. Higher pixel fidelity, multishot scenes that hold together across cuts, and a pretrained foundation built to be finetuned across domains.
Plus: Diffusion Fidelity Rendering, a new rendering approach built for pixel quality that holds up frame by frame, even on a cinema screen.
This isn't a tool you rent. It's a foundation you build on, open and yours.
kstechly retweeted

Toward general dexterity
We are training robot policies that learn a rich and coherent physical representation of the world by conditioning on multimodal observations
Here’s a small glimpse of what we’ve been building:
Task: Pick the ramen cup and place it in the box
Given the current world state, the model generates a multimodal trajectory; here we show the decoded video and the corresponding actions executed on the humanoid
kstechly retweeted

So @kayastechly 🎓 from @ASU yesterday. Kaya was a rather unusual Yochanite-- didn't take any courses or do theses with me; and wasn't even in a CS degree!
She was ever present in lab, and lunches though--and a force in all group meetings and many papers.
She will be missed..

kstechly retweeted
PSA for #ICLR2025 authors frantically making posters: Stop worrying! Just prompt o3 and GPT-4o and you will have an AGI-ready poster in seconds! Here is one @kayastechly and @karthikv792 cooked up--and it looks fully legit from poster distance!


I will be at #ICLR2025 and look forward to chatting about LRMs/reasoning/planning etc. Easiest way to run into me would likely be at our poster 👇 on Thursday (10AM poster #219). DM/Whova if you would like to meet. (Fwiw, this is my first time attending ICLR.. 😳)

kstechly retweeted
📢Delighted to share that our analysis of the planning abilities of 🍓 o1 has now been accepted to #TMLR @TmlrOrg . Joint work with @karthikv792 @kayastechly and @21stwarlock. Final version, including DeepSeek R1 results, appearing soon..
All this and more is discussed in our latest report on Planning in 🍓 Fields (👉arxiv.org/abs/2410.02162).
This report also extends the evaluation of o1 models to scheduling benchmarks (since much of what goes under "planning" in LLM benchmarks--such as Travel Planning, Trip Planning, Meeting Planning etc. are really scheduling problems reducible to canonical CSP instances, rather than the more general planning problems reducible to graph search).
(It also includes our speculations on o1's internal operations as an added bonus appendix.. 😋 teapaw.org/rao2z/status/184300304…)
(Work lead by @karthikv792 & @kayastechly -- with help from @21stwarlock) 2/

kstechly retweeted
📢"On the Self-Verification Limitations of LLMs in Reasoning and Planning Tasks" arxiv.org/abs/2402.08115 with @kayastechly and @karthikv792 apparently made it to #ICLR2025.. Swimming🏊 to Singapore.. 😎 [The 🧵s below give the details.. ]
📢 "On the self-verification limitations of LLMs in Reasoning and Planning Tasks" arxiv.org/abs/2402.08115 (lead by @karthikv792 and @kayastechly) 👇
Investigates LLM self-verification in three formal benchmarks--Game of 24, Graph Coloring and Planning, and shows that accuracy consistently degrades when LLMs self-verify, but improves when external verifiers are used in a backprompting architecture.
This combines and extends our studies from last October--arxiv.org/abs/2310.12397 and arxiv.org/abs/2310.08118--pr… at #FMDM workshop at #NeurIPS2023). 1/


kstechly retweeted
👉 Our #NeurIPS2024 paper on Chain of Thoughtlessness @ 11AM poster session today (East Hall #3010, 11AM-2pm...). All three of us are here and looking forward to chat/answer qns.. 🙏
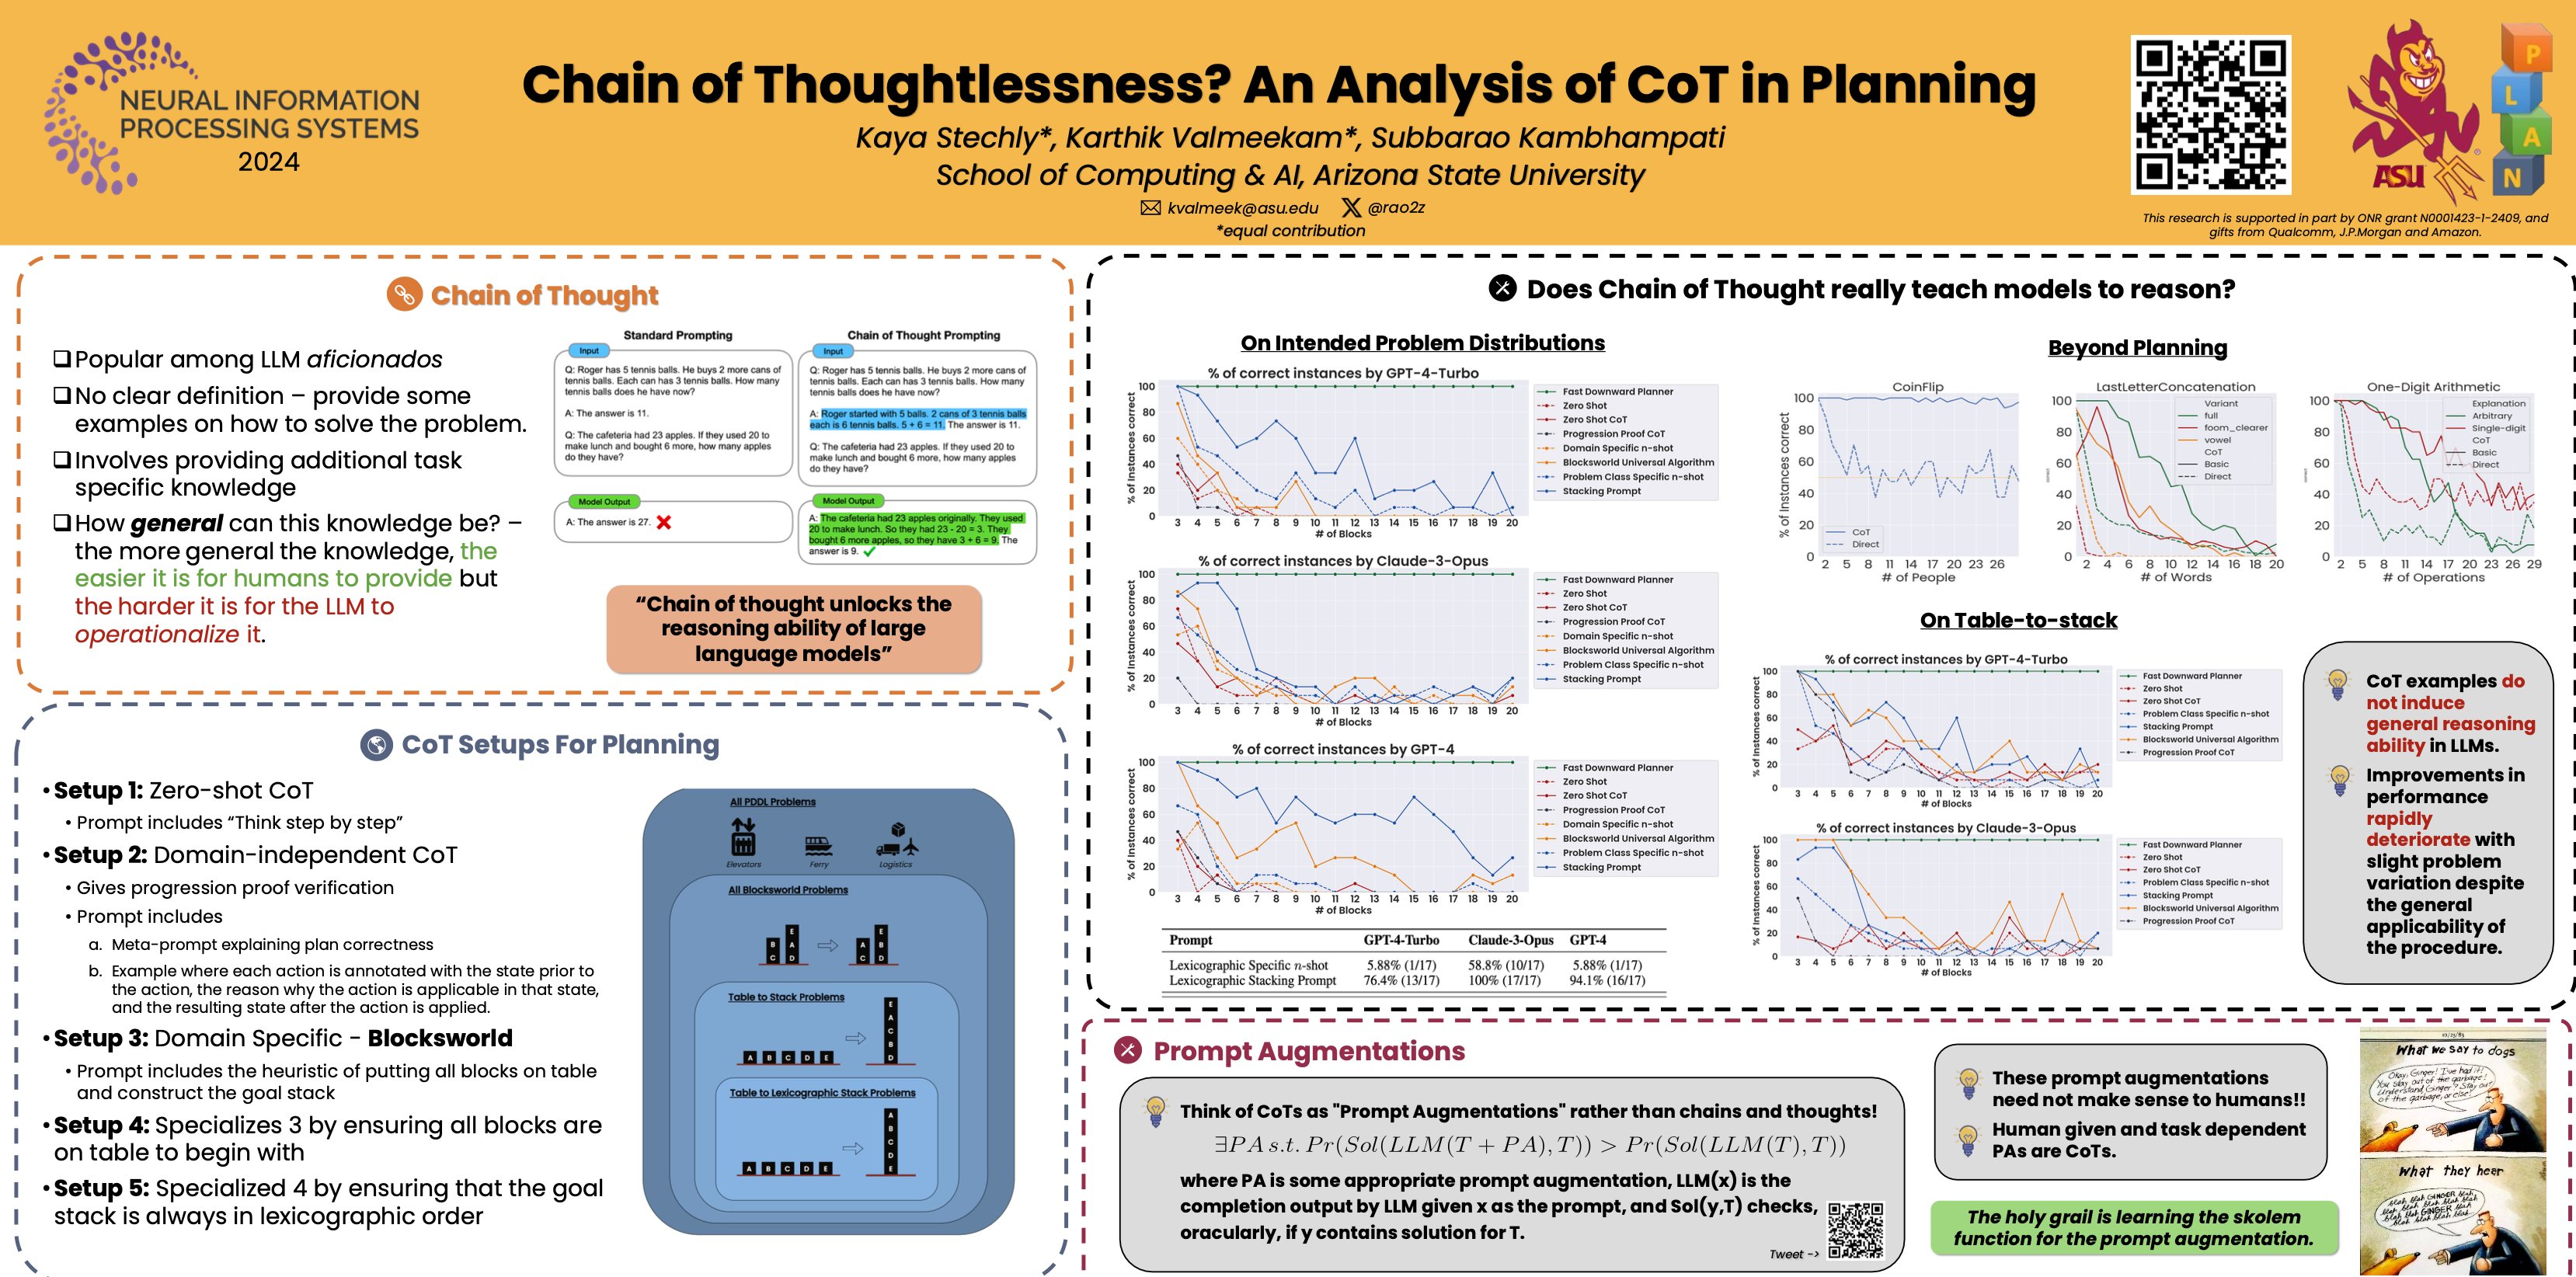
So @karthikv792, @kayastechly, @SaldytLucas and I will be at #NeurIPS2024 starting Tuesday--to present a bunch of things👇. Easiest to catch us at 11th 11AM poster session at our "Chain of thoughtlessness" poster (East hall #3010).
(I am around 10th-13th--and am happy to chat about anything #AI including "Planning: Will they? Won't they?"😋)
👉docs.google.com/document/d/1…

kstechly retweeted
So @karthikv792, @kayastechly, @SaldytLucas and I will be at #NeurIPS2024 starting Tuesday--to present a bunch of things👇. Easiest to catch us at 11th 11AM poster session at our "Chain of thoughtlessness" poster (East hall #3010).
(I am around 10th-13th--and am happy to chat about anything #AI including "Planning: Will they? Won't they?"😋)
👉docs.google.com/document/d/1…
kstechly retweeted
Woo hoo.. Chain of Thoughtlessness paper will be showing up at #NeurIPS2024 🤗 Congrats to @karthikv792 @kayastechly [details below 👇]
📢Thanks to @karthikv792 and @kayastechly's tireless efforts, here is the paper analyzing the (in)effectiveness of Chain of Thought prompting. The good news is that everything I said here and in my talks about CoT delusions still holds. The better news is that Karthik and Kaya have done more extensive experiments both with GPT4 and Claude 3 Opus.
👉 arxiv.org/abs/2405.04776
tldr; LLMs may well be smarter than that dog in the Farside cartoon (although I am sure @ylecun will pushback vociferously😋), but there is little reason to believe that we can advise them the way we advise our friends--and expect them to operationalize that advise..


kstechly retweeted
A research note describing our evaluation of the planning capabilities of o1 🍓 is now on @arxiv arxiv.org/abs/2409.13373 (thanks to @karthikv792 & @kayastechly). As promised, here is a summary (..although you should read the whole thing..) 🧵 1/

So @karthikv792 and @kayastechly stayed up until wee hours and submitted this 18-page note to arXiv; will summarize once it is made public..


kstechly retweeted
📢 "On the self-verification limitations of LLMs in Reasoning and Planning Tasks" arxiv.org/abs/2402.08115 (lead by @karthikv792 and @kayastechly) 👇
Investigates LLM self-verification in three formal benchmarks--Game of 24, Graph Coloring and Planning, and shows that accuracy consistently degrades when LLMs self-verify, but improves when external verifiers are used in a backprompting architecture.
This combines and extends our studies from last October--arxiv.org/abs/2310.12397 and arxiv.org/abs/2310.08118--pr… at #FMDM workshop at #NeurIPS2023). 1/
Can LLMs really self-critique (and iteratively improve) their solutions, as claimed in the literature?🤔
Two new papers from our group investigate (and call into question) these claims in reasoning (arxiv.org/abs/2310.12397) and planning (arxiv.org/abs/2310.08118) tasks.🧵 1/


kstechly retweeted
📢 Check out these posters on LLM Self-Critiquing (in)abilities in reasoning and planning tasks, being presented at the #NeurIPS2023 "Foundation Models for Decision Making" workshop today (12/15) by yochanites @karthikv792 and @kayastechly in Hall E2.


Can LLMs really self-critique (and iteratively improve) their solutions, as claimed in the literature?🤔
Two new papers from our group investigate (and call into question) these claims in reasoning (arxiv.org/abs/2310.12397) and planning (arxiv.org/abs/2310.08118) tasks.🧵 1/
kstechly retweeted
One paper, lead by @kayastechly (w/ @mattdmarq), evaluated the claims over a suite of graph coloring problems. The setup allows for GPT4 guessing a valid coloring in stand alone and self-critiquing modes. There is an external sound verifier outside the self-critiquing loop. 2/
